QyrusAI Named a Visionary in Gartner® Magic Quadrant™ for Agentic Software Quality Assurance Platforms – Read More

Android 17 Beta Testing_ Is Your App Ready

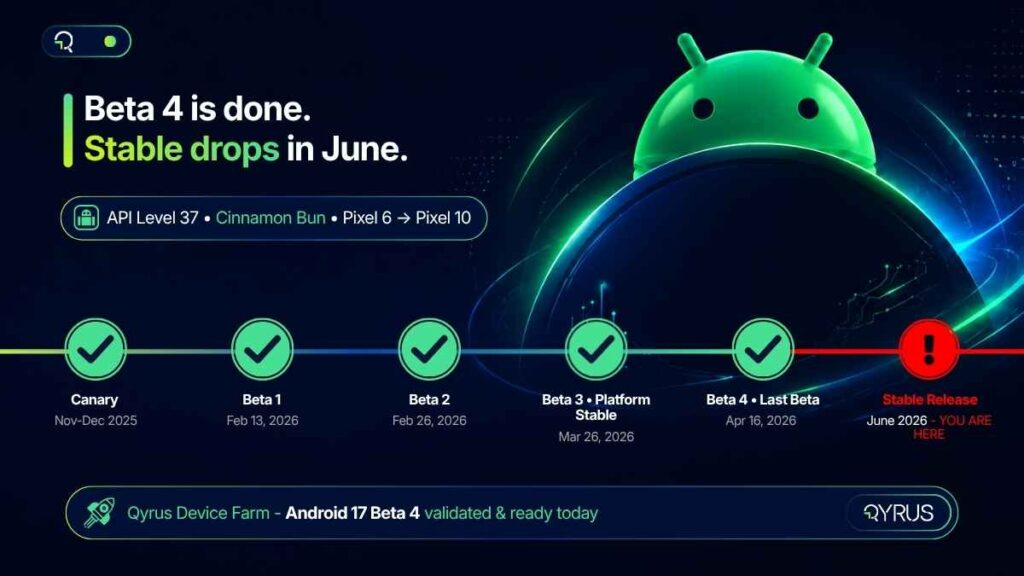
Android 17, codenamed Cinnamon Bun, is weeks away from going stable. Google released Beta 4 on April 16, 2026 — the last scheduled beta before the full public launch expected in June. That is not a soft deadline. The API is locked. Behavior changes are final. There are no more grace periods left in this cycle. 

For QA teams and mobile developers, this moment is the last clear window to validate against what will ship to over three billion active Android devices. And unlike previous cycles, Android 17 is not a cosmetic update. It carries four breaking changes that will silently break mainstream app categories — banking, streaming, fintech, and e-commerce — if they haven’t been tested. 

The good news: Qyrus has already validated Android 17 Beta 4 on its Device Farm. Android 17 devices are available to your team today. The testing environment is ready — the only question is whether your app is. 


Android 17 Release Timeline at a Glance 

Milestone 

Date 

Status 

Action for QA Teams 

Canary / DP Builds 

Nov–Dec 2025 

✅ Complete 

Early API exploration 

Beta 1 

Feb 13, 2026 

✅ Complete 

Start compatibility scans 

Beta 2 

Feb 26, 2026 

✅ Complete 

Handoff API testing 

Beta 3 (Platform Stable) 

Mar 26, 2026 

✅ Complete 

Lock test baselines 

Beta 4 (Last Beta) 

Apr 16, 2026 

✅ Complete 

Final regression runs 

Stable Release 

June 2026 

⏳ Imminent 

YOUR APP MUST BE READY 

android17_timeline

What’s New in Android 17 (Cinnamon Bun): A QA Engineer’s Briefing 

Android 17 (API level 37) is Google’s most significant platform restructuring in several years. Before diving into what breaks, here is what is new — and why each feature creates immediate testing obligations. 

App Bubbles — Any App Can Now Float 

Google has extended the Bubbles system beyond messaging apps to every application on the platform. Users can now long-press any app icon and open it as a floating window that overlays whatever is currently on screen. On tablets and foldables, a Bubble Bar anchors to the taskbar and holds recently bubbled apps. 

For QA teams, this introduces a new class of test scenarios: z-order conflicts (does your app behave correctly when partially obscured by another app’s bubble?), multi-window state preservation when a bubbled session is interrupted, and layout integrity when your app itself is opened as a bubble on a foldable device. 

Handoff API / ‘Continue On’ — Cross-Device State Transfer 

Announced at Google I/O 2026 as ‘Continue On,’ the Handoff API allows users to transfer the active state of an app from one Android device to another. Start composing an email on a Pixel 9 phone, and a suggestion appears on a nearby Pixel Tablet to pick up exactly where you left off. The system synchronizes state via CompanionDeviceManager and supports both native app-to-app transitions and app-to-web fallback. 

The testing implications are significant. Apps that participate in Handoff need to correctly serialize state, handle graceful fallback when the native app isn’t installed on the receiving device, and maintain session continuity over WiFi under variable network conditions. 

Native App Lock — System-Level Biometric Protection 

For the first time, Android ships a built-in App Lock that requires no third-party vault app. Users long-press any app icon, select ‘App lock,’ and choose their authentication method — PIN, pattern, password, or biometric. Notifications from locked apps are masked: instead of showing content, users see ‘New message’ or ‘New notification.’ 

This is a critical feature for fintech, healthcare, and banking apps. Testing must cover the full authentication flow, correct masking of notification content for locked apps, and behavior after failed authentication attempts. 
android17_breaking_changes

Desktop Interactive PiP — External Monitor Support 

Building on Android 16’s desktop mode foundations, Android 17 Beta 3 introduced Interactive Picture-in-Picture (iPiP) for external display sessions. When a Pixel device is connected to a monitor, apps run as fully interactive floating windows — not static mirrors. Widgets scale correctly, and the Bubble Bar is available for multitasking. 

Apps that interact with external displays now need to be tested in this mode, validating input handling, widget rendering, and interactive state when the app runs as a floating iPiP window. 

Frosted Glass / Material 3 Expressive UI 

Android 17 applies a system-wide translucent Gaussian blur effect — a frosted glass aesthetic — to the volume panel, power menu, notification shade, and Quick Settings. This is the most visually disruptive change for screenshot-based test assertions. Any test suite relying on exact pixel matching against Android 16 baselines will fail immediately. Visual regression baselines need to be reset entirely before your first Android 17 test run. 

Digital Wellbeing: Pause Point 

Android 17 introduces Pause Point — a 10-second interstitial screen that appears before opening an app the user has marked as distracting. For QA teams, this is relevant for any automation flow that launches an app after a user has configured digital wellbeing restrictions. Test scripts that assume immediate app launch will break if the device under test has Pause Point enabled. 

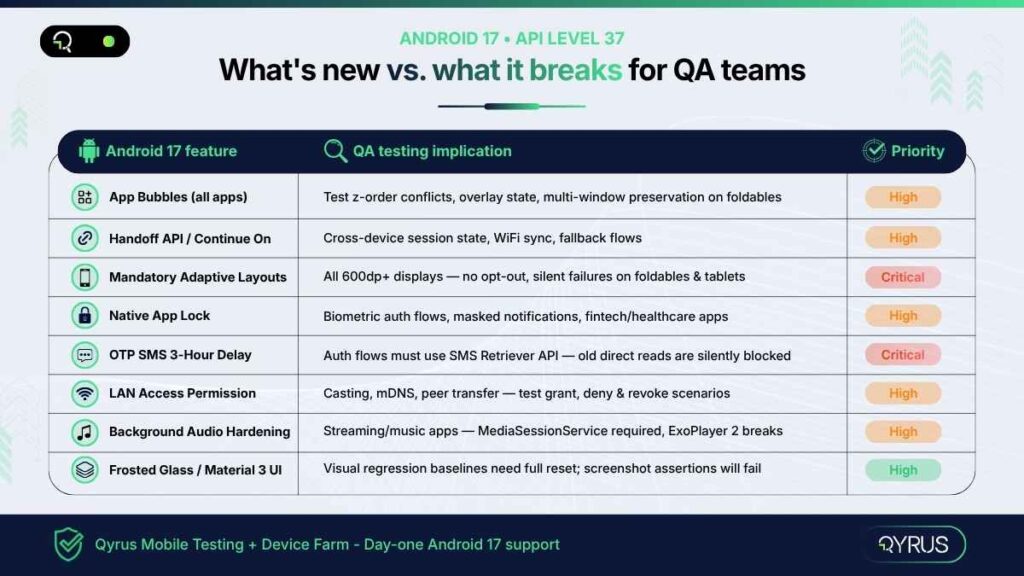
 Android 17 Features vs. QA Testing Implications 

Android 17 Feature 

QA Testing Implication 

Complexity 

App Bubbles (All Apps) 

Test z-order conflicts, overlay state, multi-window preservation 

High 

Handoff API / Continue On 

Cross-device session state, fallback flows, WiFi sync 

High 

Mandatory Adaptive Layouts 

All tablet/foldable UI — no opt-out, silent breakage risk 

Critical 

Native App Lock 

Biometric auth flows, masked notifications, fintech/healthcare apps 

High 

OTP SMS 3-Hour Delay 

Auth test flows must use new SMS Retriever API path 

Critical 

LAN Access Permission 

Casting, mDNS, peer transfer — all need explicit grant now 

High 

Background Audio Restrictions 

Streaming/music apps — MediaSessionService foreground service required 

High 

Frosted Glass / Material 3 UI 

Visual regression baselines will need full reset 

Medium 


The Silent App-Killers: Android 17 Breaking Changes You Cannot Ignore 

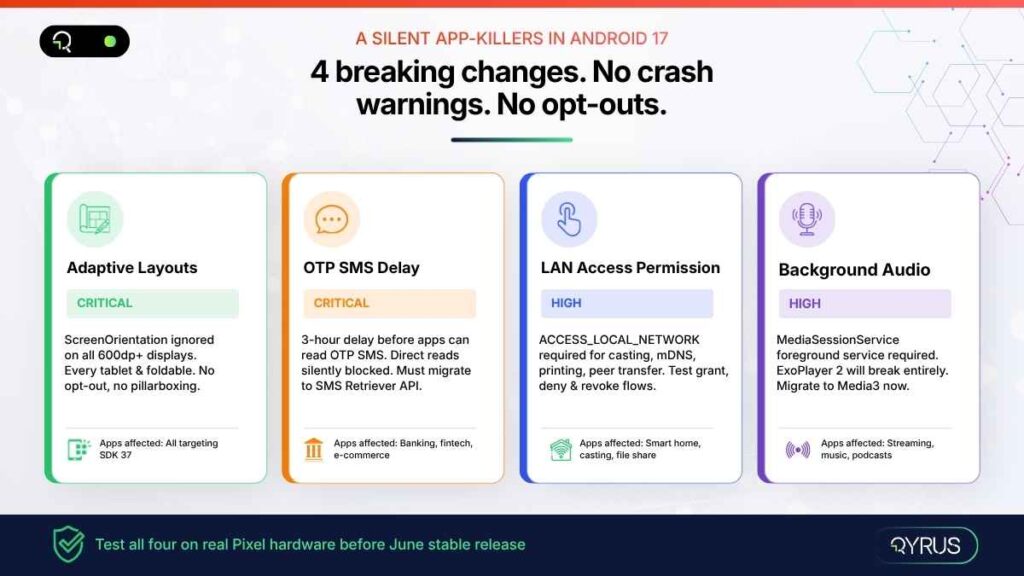
New features generate headlines. Breaking changes generate production incidents. Android 17 ships four behavior changes that will affect mainstream app categories at scale — and none of them announces itself with a crash. They surface as subtle regressions, failed test flows, and user-facing errors after the stable release ships. 

⚠  If your app does any of these four things and you have not tested on Android 17 Beta 4, you have a production incident waiting in June. 

1. Mandatory Adaptive Layouts — No Opt-Out, No Warning 

Starting with API level 37, Android completely ignores the screenOrientation, resizeableActivity, minAspectRatio, and maxAspectRatio manifest attributes on any display wider than 600dp. That means every tablet and every foldable device on the market. 

Your app will fill the entire screen window regardless of what your manifest says. There is no pillarboxing, no opt-out. The failure mode is not always a crash — it is often far subtler. A camera preview stretched sideways. Navigation buttons pushed off-screen on a Pixel Fold. User state lost silently when the device is rotated. These are the kinds of bugs that reach production and damage reviews before anyone realizes what happened. 

Every app targeting SDK 37 must be tested across at least three screen form factors: a standard phone, a foldable, and a tablet. This is not optional from a Play Store compliance perspective. 

2. OTP SMS 3-Hour Delay — Banking and Fintech Alert 

Android 17 introduces a mandatory three-hour delay before most apps can programmatically read SMS messages containing a one-time password. The SMS_RECEIVED_ACTION broadcast is withheld, and SMS provider database queries are filtered for apps targeting API level 37. 

Exemptions are narrow: the default SMS app, assistant apps, and apps that have correctly implemented the SMS Retriever or SMS User Consent APIs. Apps that read OTP codes directly from SMS — a common pattern in banking, e-commerce checkout flows, and two-factor authentication — will silently fail after the update. 

The QA implication is direct: your OTP authentication test flows must be updated to simulate the new API path, not the legacy direct SMS read. Any test that validates a login or checkout OTP flow using the old pattern will produce a false pass on Android 16 and a production failure on Android 17. 

3. Local Network Access Requires Explicit Runtime Permission 

Apps can no longer discover or communicate with devices on the local network without an explicit user grant. Android 17 introduces the ACCESS_LOCAL_NETWORK permission (part of the NEARBY_DEVICES group), which triggers a system permission prompt identical to the photo and contacts pickers. 

The scope of impact is broad: screen mirroring and casting, wireless printing, Chromecast integration, smart home device discovery via mDNS, and peer-to-peer file transfer all require this explicit grant. Apps that use any of these features need to test three scenarios: the user grants the permission, the user denies it, and the user revokes it mid-session. Graceful degradation — not crashes — must be the result in all three cases. 

4. Background Audio Hardening — Streaming Apps Must Adapt 

Android 17 strictly enforces new restrictions on background audio interactions for apps targeting API level 37. Audio playback, audio focus requests, and volume adjustments made while the app is not visible to the user now require a foreground service using MediaSessionService. 

Apps that still use the deprecated ExoPlayer 2 library (com.google.android.exoplayer2) will break entirely — not degrade gracefully. Google’s Media3 library (stable since March 2026) is the required migration path. If your streaming, podcast, or music app has not migrated from ExoPlayer 2 to androidx.media3, Android 17’s stable release is the forcing function. 

Test scenarios must cover background audio initiation, audio focus handling when another app takes focus, and correct foreground service lifecycle management.
Android17_feature_qa

Why Real Device Testing Matters More Than Ever with Android 17 

Emulators have their place in development. They do not have a place as your primary Android 17 test environment. 

Android 17’s most significant changes — App Bubbles, Desktop iPiP, Handoff API, and adaptive layout enforcement — all involve hardware-specific behavior that emulators cannot replicate faithfully. The Bubble Bar behaves differently on a Pixel Fold than it does on a Pixel Tablet. Desktop Interactive PiP requires a physical external monitor connection. The Handoff API depends on real WiFi communication between two physical devices. Biometric bypass for App Lock testing is simply not possible on an emulator. 

There is also the fragmentation dimension. Android 17 supports Pixel 6 through Pixel 10 — five hardware generations with meaningfully different screen sizes, aspect ratios, foldable form factors, and chipsets. The adaptive layout changes that look fine on a Pixel 9 can silently break the camera interface on a Pixel Fold. Testing a single device is not a regression suite. 

Network conditions matter too. The Handoff API synchronizes state over WiFi via CompanionDeviceManager. The three-hour OTP delay creates new timing dependencies in authentication flows. Testing these scenarios on a real device with configurable network profiles — simulating 4G, LTE, congested WiFi — is the only way to catch timing-sensitive failures before they affect users.

Real Device Testing Checklist for Android 17: 

✓ Standard phone (Pixel 9 or Pixel 8) — core regression baseline 

✓ Foldable device (Pixel Fold) — mandatory adaptive layout validation 

✓ Tablet (Pixel Tablet) — Bubble Bar and desktop multitasking 

✓ External display session — Desktop Interactive PiP 

✓ Two-device setup — Handoff API / Continue On flows 

✓ Network profiles — OTP timing, Handoff sync under variable connectivity 

Qyrus Has Already Validated Android 17 Beta 4 — Here’s What That Means for You 

The Qyrus team validated core platform compatibility with Android 17 Beta 4 on the Device Farm. Android 17 devices are available to clients today — no waiting for the stable release to begin testing. 

But device availability is just the starting point. Each of Android 17’s breaking changes maps directly to a specific Qyrus capability that makes testing it faster, more thorough, and more maintainable. 

Android 17 Challenges Mapped to Qyrus Capabilities 

Android 17 Testing Challenge 

Qyrus Capability 

Adaptive layout regression on foldables & tablets 

Visual Testing on real Pixel Fold / Pixel Tablet devices in the Device Farm 

OTP SMS delay — new auth flow testing 

Verify OTP action type + real Pixel devices with proper SMS Retriever flow 

App Lock biometric testing 

Biometric Bypass (Beta) + Instrumentation on dedicated devices 

Handoff API / cross-device state testing 

Multi-device sessions with network shaping via Device Farm 

Background audio restrictions 

Automated scripts with Healer AI for locator maintenance after media API changes 

Frosted Glass UI visual regression 

Visual Testing baseline comparison — auto-flag rendering differences 

Full regression across Pixel 6–10 

Parallel execution across device pool — all generations available Day One 


Device Farm: Day-One Access, Real Hardware, Secure Cloud 

  • 99.9% real device availability — no emulators, no queuing surprises 
  • Pixel 6 through Pixel 10 across all generations, including Pixel Fold and Pixel Tablet 
  • Network shaping: configure bandwidth, latency, and packet loss to simulate real-world Handoff API and OTP timing conditions 
  • Dedicated private devices available for clients requiring biometric configuration (App Lock testing) 
  • ISO 27001 and SOC 2 Type 2 compliant cloud — enterprise security, no compromise 
  • Day-one OS support: Qyrus delivered Android 16 on its release date; Android 17 follows the same commitment 
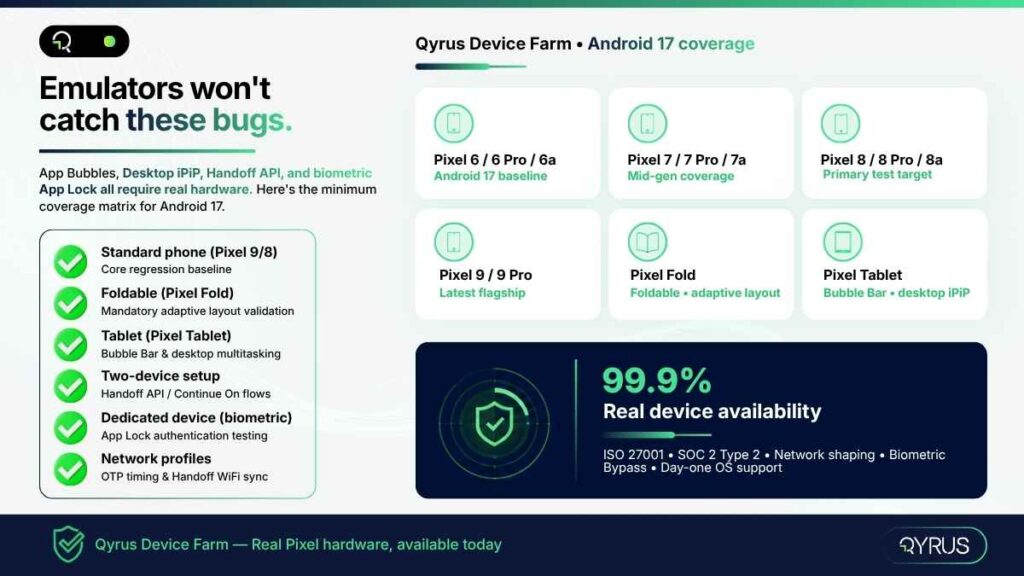
android17_device_checklist

How to Start Android 17 Beta Testing on Qyrus in 4 Steps 

Your team does not need to wait for the stable release. Android 17 Beta 4 devices are available on the Qyrus Device Farm now. Here is how to get your first test run done today. 

  1. Log in to Qyrus — or request Android 17 Beta 4 device access if you are a new client. Android 17 is available on compatible Pixel devices in the Device Farm. 
  1. Upload your APK and configure your project — create a new project or import your existing test suite. Qyrus supports JSON and XLSX import for existing scripts. 
  1. Select your Android 17 device pool — choose Pixel 6 through Pixel 10 for a full generational sweep, or target Pixel Fold and Pixel Tablet specifically for adaptive layout and Bubble Bar validation. 
  1. Run your regression suite — prioritize the four breaking-change areas first — adaptive layouts on foldables, OTP authentication flows, LAN-dependent features, and background audio playback. Enable Healer AI on your first run to auto-correct any locators broken by the Material 3 Expressive UI changes. 

Use network profiles to simulate variable connectivity for Handoff API testing. Schedule parallel runs across your device pool to compress what would be a multi-day regression into a single execution window. 

 Frequently Asked Questions: Android 17 Beta Testing 

What is Android 17’s codename and API level? 

Android 17 is codenamed ‘Cinnamon Bun’ and uses API level 37. It is the seventeenth major release of the Android platform, following Android 16 (Baklava, API level 36) which shipped in June 2025. 

When does Android 17 stable release? 

The stable release is expected in June 2026, aligned with Google’s new Q2 major SDK release cadence. Pixel 6 through Pixel 10 devices will receive it first. Samsung, OnePlus, Motorola, and other OEMs typically follow three to six months after Google’s stable launch. 

Which Pixel devices support Android 17 Beta? 

Android 17 Beta is supported on Pixel 6, Pixel 6 Pro, Pixel 6a, and all newer Pixel models through the Pixel 10 lineup. Pixel 5 and older are not eligible. Select Motorola devices in certain regions have also launched a manufacturer beta program. 

What apps are most at risk of breaking on Android 17? 

Four app categories face the highest risk: (1) Banking and fintech apps that read OTP codes directly from SMS without using the SMS Retriever API; (2) Apps that restrict screen orientation on tablets and foldables — this opt-out no longer exists at API level 37; (3) Streaming and music apps that rely on ExoPlayer 2 for background audio; (4) Any app that uses LAN discovery for casting, printing, or peer-to-peer transfers without requesting the new ACCESS_LOCAL_NETWORK permission. 

How is Android 17 different from Android 16 for QA teams? 

Android 16 focused primarily on UI adaptability — making apps resizable by default on large screens. Android 17 goes further: it removes the opt-out entirely, adds cross-device state transfer via the Handoff API, introduces system-level App Lock with biometric masking, and enforces three new privacy defaults (OTP delay, LAN permission, contacts picker) that directly affect how authentication and networking flows must be tested. The breaking changes in Android 17 are more widespread and less visible than Android 16’s. 

Can I test Android 17 without a physical Pixel device? 

You can use the Android Emulator for initial API compatibility checks. However, the most impactful Android 17 changes — App Bubbles on foldables, Desktop Interactive PiP, Handoff API cross-device flows, and App Lock biometric testing — cannot be reliably validated on an emulator. Real device testing on a cloud-based device farm is the only way to catch hardware-specific regressions and multi-device interaction scenarios before they reach your users. 

What happened to Android 17 Developer Previews? 

Google replaced the traditional Developer Preview program with continuous Android Canary builds starting with the Android 17 cycle. Canary builds are updated throughout the year as features pass internal testing, rather than being bundled into quarterly preview releases. This change is designed to give developers earlier and more continuous access to new platform capabilities. 

 The Clock Is Running 

Beta 4 is done. The API is locked. June is not a future event — it is the current month. 

The four breaking changes in Android 17 — mandatory adaptive layouts, OTP SMS delay, LAN access permissions, and background audio restrictions — are not edge cases that affect niche apps. They affect banking flows, streaming sessions, casting features, and every app that targets tablets and foldables. That is most production apps in most enterprise portfolios. 

The window to catch these regressions in a controlled testing environment, fix them before users see them, and push a compliant update to the Play Store is open right now. In a few weeks, it closes. 

Qyrus Device Farm has Android 17 Beta 4 validated and ready. Real Pixel devices across all supported generations — from Pixel 6 through Pixel 10, including Pixel Fold and Pixel Tablet — are available today. Your team does not need to wait for stable to start. 

Start your Android 17 testing on Qyrus today. 

Book a demo

Explore Mobile Testing 

Explore Device Farm

A data breach at a financial institution costs an average of $6.08 million, a figure 22% higher than in any other industry. Over 50% of members will switch financial institutions after a single poor digital experience, while over 80% of regression testing remains completely manual.  

This whitepaper is for QA directors, IT leaders, and application teams who have felt that gap. It shows, through published case study outcomes and an independent Forrester ROI study, how a unified, AI-powered platform closes them.  

Core Insights & Feature Deep-Dive 

What’s Inside the Whitepaper? 

This whitepaper maps the specific fracture points in credit union and regulated financial QA environments and names the limitations of the incumbent testing platform tools.  

Key Business Insights: 

  • 213% ROI Achieved: See the breakdown of an independent study showing a $1M net present value for top banking institutions.  
  • Sub-6-Month Payback Period: Learn how the platform pays for itself quickly through massive operational and quality efficiency gains today.  
  • $6.08M Data Breach Cost: Discover how automated testing reduces the frequency of costly defects.  
  • 80%+ Manual Testing Reduced: See how teams successfully transitioned slow manual regression suites into automation.  

Master the Qyrus Orchestration Toolkit 

Learn how to leverage specialized single-use agents that bridge the gap between legacy point solutions and true continuous automated validation:  

  • TestPilot Execution Agent: Instantly creates and executes tests from any live digital banking platform application screen autonomously.  
  • TestGenerator Tool: Converts user requirements and PDF specifications into automated, deep financial testing scenarios easily.  
  • Healer Script Automation: Automatically self-heals broken test scripts when monthly upgrades modify underlying digital banking UI components completely.  
  • Echo Synthetic Data: Generates realistic financial test data on demand that is parameterized and privacy-safe.  
  • API Builder Engine: Virtualizes APIs before live environments are available to enable early core integration pipeline testing.  
  • Rover Explorer Tool: Autonomously explores complex banking applications to identify unexpected anomalies or paths.

Ready to Eliminate Quality Failures? 

Fill out the form to download your copy of the guide and protect your critical banking member trust. 

As featured in The Forrester Total Economic Impact Study. 

“The real power of Qyrus is that we have this extremely broad testing capability in one tool, run in the cloud, and reusable across our teams.”  

— Executive Lead at Shawbrook Bank. 

June Release Notes

Welcome to the June release!  

In June, our engineering teams focused on injecting deep operational intelligence, enterprise flexibility, and rock-solid platform infrastructure into your daily testing workflows. 

Across every service layer, we are delivering enhancements that eliminate friction, maximize execution visibility, and give you far greater control over how you manage and scale your automation suites.  

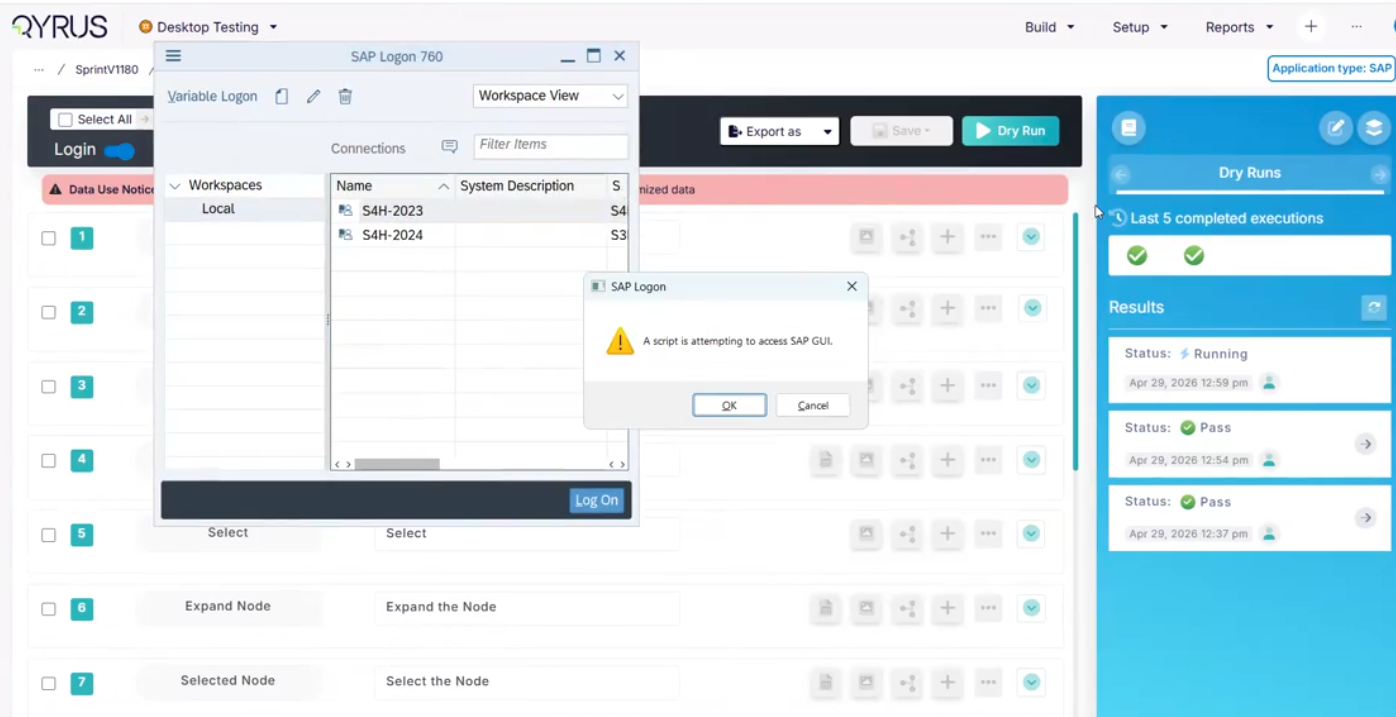
In Web Testing, Test Generator v2 has taken a massive leap forward by expanding its AI-driven capabilities to handle advanced coding and API interactions natively. Desktop Testing receives an influx of precision features specifically designed to streamline complex SAP environments and dynamic grid data extraction. 

Our backend and API testing capabilities have also matured significantly. We’ve introduced highly requested organization tools like drag-and-drop rearrangement and bulk migration workflows, paired with a unified deep-linking model to make cross-team collaboration absolutely frictionless.  

Finally, we’ve fortified our foundational layer with hardened, cloud-resilient session management in the Device Farm and powerful scheduling and execution combos within Test Orchestration. 

Let’s dive into the full breakdown of everything new across the platform this June! 

Web Testing

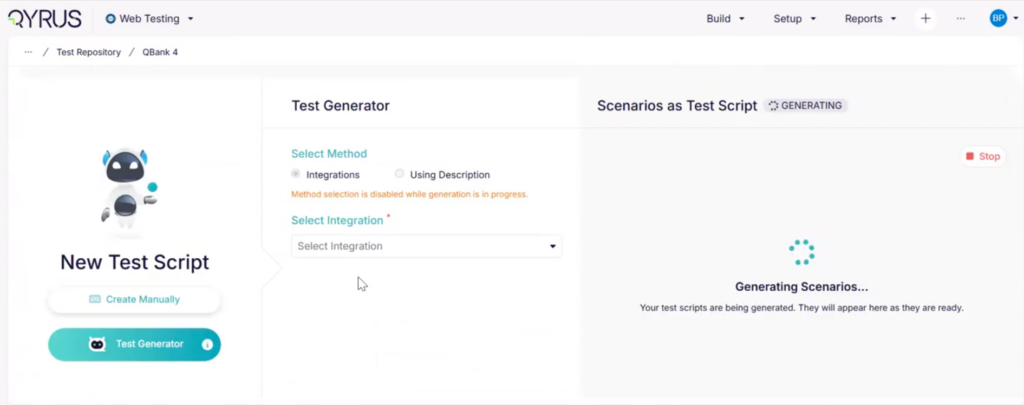
Complete AI Test Generation: Support for Code, APIs, and Variables! 

Complete AI Test Generation

The Challenge:  

When using AI to automatically generate complex web testing scenarios, the system needs to be able to handle more than just basic UI clicks and text inputs. Previously, users utilizing Test Generator v2 were required to add certain missing data fields when the AI attempted to generate advanced actions. Specifically, generated steps for API calls, complex variable data handlers, and embedded JavaScript or JavaCode executions were returning empty or lacking the necessary dummy data, forcing testers to fill in the blanks. 

The Fix:  

We have expanded the capabilities of Test Generator v2 to fully support and populate data for advanced web actions. The AI engine has been updated to accurately generate and fill in the required fields for API Actions, Create Variable Data Handlers, Execute JavaCode, and Execute JavaScript steps directly within the generated test scenarios. 

How will it help?  

This upgrade ensures your AI-generated tests are comprehensive and ready to execute with minimal manual intervention. 

  • Advanced Scenario Automation: Confidently use the AI to generate complex, end-to-end tests that seamlessly blend UI interactions with backend API validations and custom code executions. 
  • Reduced Manual Coding: The AI now intelligently supplies the necessary code structures and dummy data for JavaScript and JavaCode steps, saving your engineers significant manual scripting time. 
  • Robust Variable Handling: Automatically generate and populate variable data handlers, ensuring your dynamic test logic works flawlessly right out of the box. 

Dynamic Data Extraction: Table & Grid Support for Variables! 

Dynamic Data Extraction

The Challenge:  

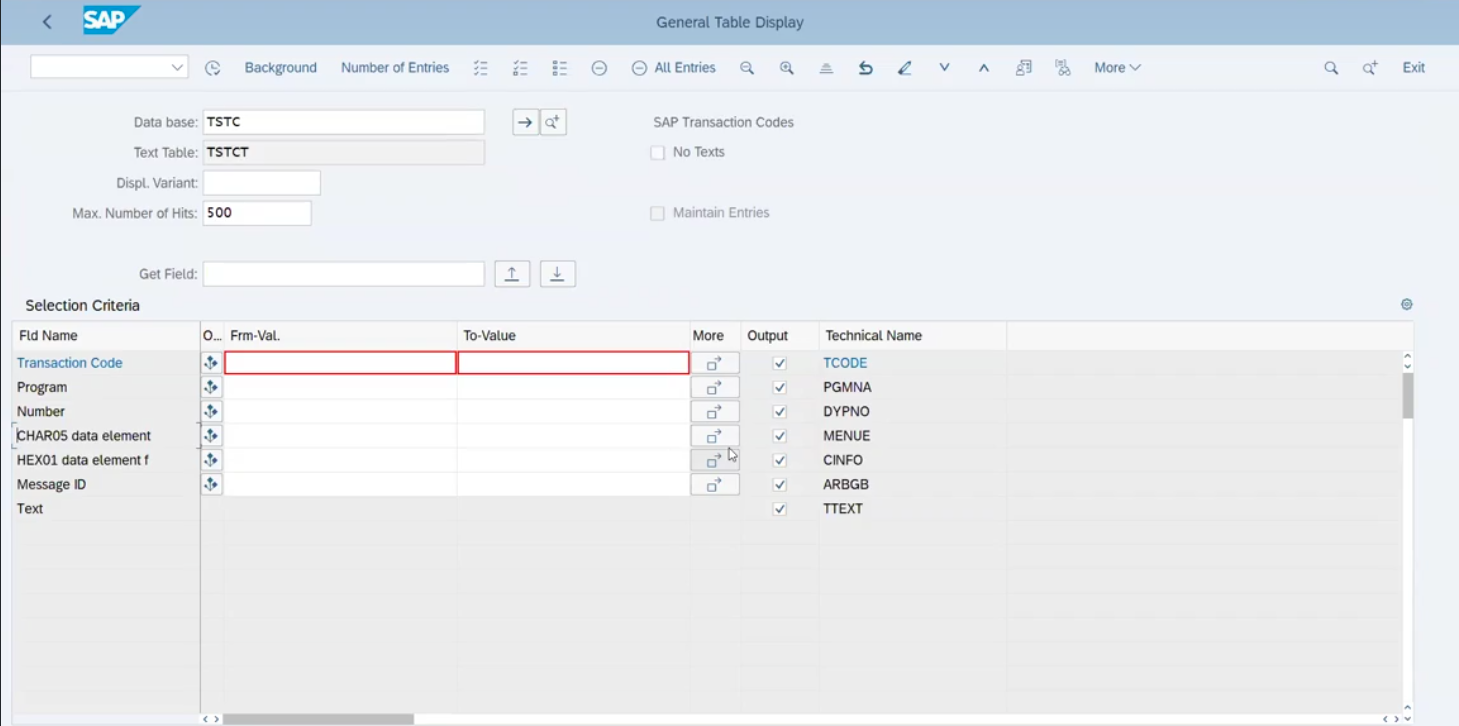
Desktop applications often display critical information—like financial records, inventory lists, or user data—within complex tables and data grids. Previously, extracting a dynamic value from a specific cell within these desktop grids and storing it as a variable was difficult. Testers often had to rely on complex workarounds or custom scripting just to grab a simple value, which slowed down the creation of data-driven test scenarios. 

The Fix:  

We have significantly enhanced the Create Variable action within the Desktop Testing service to natively support table and grid cell inputs. You can now seamlessly target a specific cell within your desktop application’s data grid and directly extract its contents into a variable for use later in your automation script. 

How will it help?  

This enhancement makes interacting with complex desktop data structures simple and straightforward. 

  • Data-Driven Flexibility: Easily capture dynamic data generated during a test (like a newly created order ID or a status code) directly from a table cell to pass into subsequent steps. 
  • Simplified Scripting: Eliminate the need for fragile workarounds or custom code just to read a value from a desktop grid, keeping your automation scripts clean and easy to maintain. 
  • Robust End-to-End Validation: Build stronger assertions by dynamically extracting table data and verifying it against expected outcomes later in your workflow. 

Predictable Connections: Smart SAP Login Logic! 


The Challenge:  

When automating SAP workflows, the rules dictating whether a test script would attach to an existing SAP session or launch a brand-new window were previously implicit and relied heavily on backend exceptions. If a test provided partial login information (like just a client ID), the system’s behavior was unpredictable. This ambiguity often led to duplicate SAP instances cluttering the desktop, consuming system resources, and causing connection confusion during complex test runs. 

The Fix:  

We have completely overhauled the core logic for the “Login to SAP” action, establishing clear, explicit rules for the attach-or-create decision. Now, if a running SAP session perfectly matches the requested username and client, the system seamlessly attaches to it. If the credentials differ, it opens a new connection. Crucially, we removed the reliance on exception-driven fallbacks and updated the action results to explicitly surface exactly which path was taken during the test. 

How will it help?  

This structural upgrade brings absolute control and reliability to your SAP desktop automations. 

  • Eliminate Duplicate Windows: The strict matching rules guarantee that new application windows are only spawned when absolutely necessary, keeping your testing environment clean. 
  • Predictable Execution: Whether you provide full credentials or partial client information, the login action behaves exactly as documented without unpredictable fallback loops. 
  • Clear Traceability: You can now instantly see within your test execution reports whether a script attached to an existing session or created a new one, drastically simplifying script debugging. 

Front and Center: Active SAP Session Monitoring! 

The Challenge:  

When automating complex SAP workflows, visibility is key to ensuring your tests are running as intended. Previously, when utilizing the new “Connect to Existing SAP Window” action, the test execution would successfully proceed, but the SAP GUI often remained hidden in the background. This obscured the live testing steps, making it incredibly difficult for automation engineers to visually monitor the execution in real time or immediately spot UI-level issues as they occurred. 

The Fix:  

We have updated the SAP automation engine to guarantee immediate visibility. Now, whenever a script utilizes the “Connect to Existing SAP Window” command, the platform automatically forces the active SAP application directly to the foreground of your desktop environment. 

How will it help?  

This quality-of-life improvement ensures complete transparency and immediate feedback during your desktop executions. 

  • Real-Time Monitoring: Watch your test steps execute live on the screen, giving you immediate visual confirmation of the application’s behavior and performance. 
  • Faster Debugging: Instantly spot unexpected pop-ups, UI anomalies, or navigation errors the exact moment they happen instead of digging through logs after the test completes. 
  • Streamlined Usability: No more manually hunting for minimized windows or alt-tabbing to find the right screen; the platform actively surfaces the relevant SAP instance right when you need to see it. 

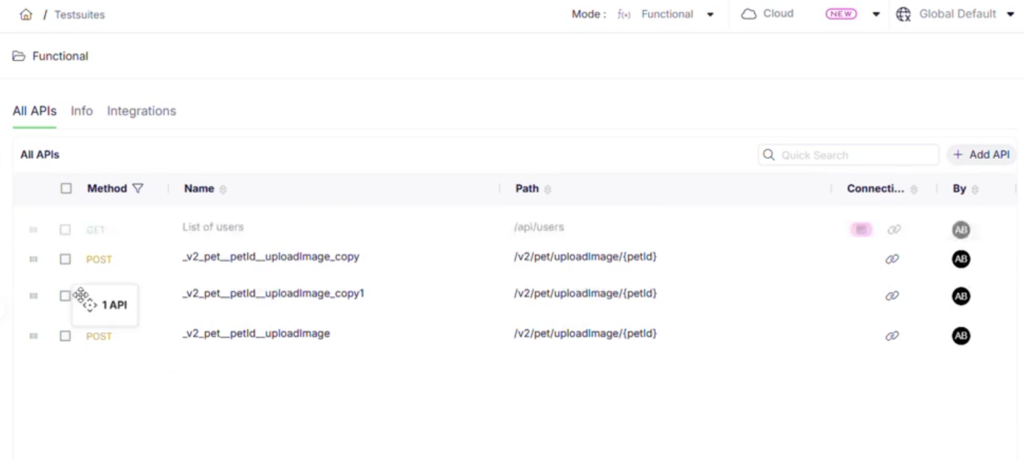
Effortless Organization: Drag-and-Drop API Rearrangement!

Drag-and-Drop API Rearrangement

The Challenge: 

When managing a growing library of API test scripts, keeping your workspace logically organized is crucial for team efficiency. Previously, the list of scripts on the “All APIs” page was rigid. If you needed to reorder your scripts to reflect a specific execution sequence, group related endpoints together, or simply clean up your view, there was no intuitive way to move them around. This lack of flexibility made managing extensive API suites feel clunky and time-consuming. 

The Fix: 

We have introduced fluid drag-and-drop functionality directly to the right-hand side (RHS) “All APIs” page. You can now seamlessly rearrange your entire list of API scripts simply by clicking, dragging, and dropping them into your exact preferred order. 

How will it help? 

This UI enhancement puts you in complete control of how your API workspace is structured. 

  • Intuitive Organization: Visually structure your API scripts exactly how you think about them, effortlessly grouping related tests without relying on rigid naming conventions. 
  • Faster Test Management: Quickly reorder scripts to match natural execution flows or priority levels in seconds, eliminating frustrating administrative overhead. 
  • Streamlined Workspace: Maintain a clean, personalized, and highly navigable project view, making it easier for both you and your team to locate specific endpoints instantly. 

Seamless Sharing: Deep Linking for API Testing!

The Challenge:  

Sharing specific API test artifacts—like a complex script, a failed execution report, or a massive test suite—with team members used to be a hassle. Testers often had to tell colleagues exactly where to click through the platform hierarchy to find the right asset. Additionally, strict team-based silos in QAPI made it difficult to securely share direct links with designated collaborators without hitting frustrating access roadblocks and permission errors. 

The Fix:  

We have introduced comprehensive Deep Linking across the entire API Testing ecosystem, aligning it perfectly with the behavior you already know from Test Orchestration. Every major entity—including Projects, Scripts, Suites, Workflows, and Reports—now automatically generates a unique, shareable deep link ID. Crucially, we also implemented a smart collaborator-based access model for QAPI, meaning authorized collaborators can now instantly access shared deep links even across different individual team setups. 

How will it help?  

This underlying infrastructure update drastically reduces the friction of team collaboration and debugging. 

  • Instant Collaboration: Drop direct links to specific API scripts, suites, or reports directly into your Slack channels or Jira tickets, getting your team looking at the exact same screen instantly. 
  • Frictionless Access: The intelligent collaborator-based model ensures that deep links are both secure and accessible, smoothly granting visibility to explicitly authorized users without manual permission wrestling. 
  • Unified Experience: Deep linking now behaves consistently across both API Testing and Test Orchestration, providing a seamless, predictable sharing experience across the entire Qyrus platform. 

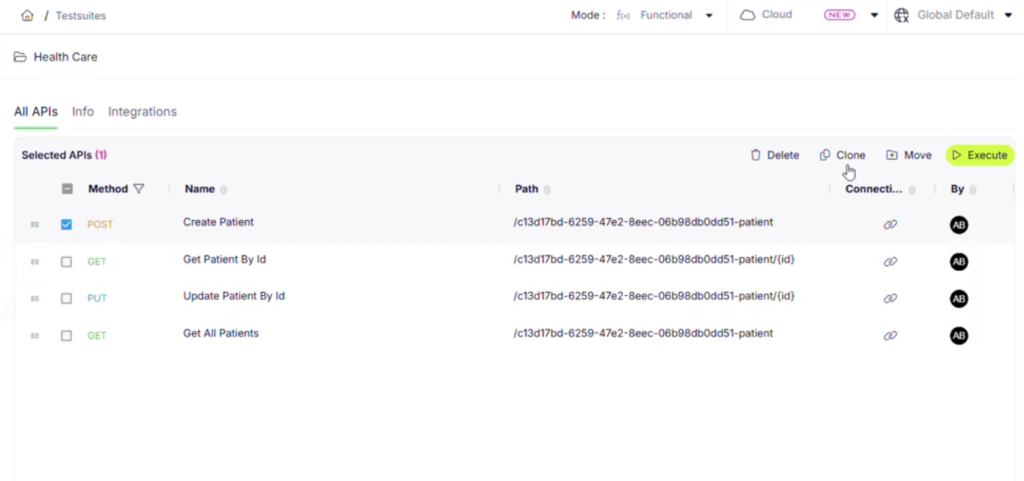
Effortless Reorganization: Bulk Copy & Move for APIs!

Bulk Copy- Move for APIs

The Challenge:  

As your API test coverage expands, test suites inevitably need restructuring. Whether you’re refactoring older tests, creating specialized regression suites, or just cleaning up your workspace, moving or cloning APIs one by one is an incredibly tedious process. Previously, there was no streamlined way to select multiple API scripts and securely transfer or copy them into a different suite, forcing testers into a frustrating loop of repetitive manual actions. 

The Fix:  

We have completely redesigned the workflow for migrating scripts between test suites. You can now bulk-select, copy, and move multiple APIs simultaneously. This update includes intuitive new checkbox triggers, dedicated options within the three-dot menu, and fluid drag-and-drop capabilities within the left-hand panel, giving you total flexibility over how you reorganize your workspace. 

How will it help?  

This redesign drastically cuts down administrative overhead when managing your API library. 

  • Massive Time Savings: Quickly bulk-select dozens of API scripts and move or clone them to a new suite in just a few clicks, eliminating repetitive manual work. 
  • Flexible Organization: Whether you prefer drag-and-drop simplicity or structured menu commands, the new interface adapts to your preferred organizational workflow. 
  • Streamlined Refactoring: Easily break down massive test suites into smaller, targeted collections or combine scripts into comprehensive master suites without breaking a sweat. 

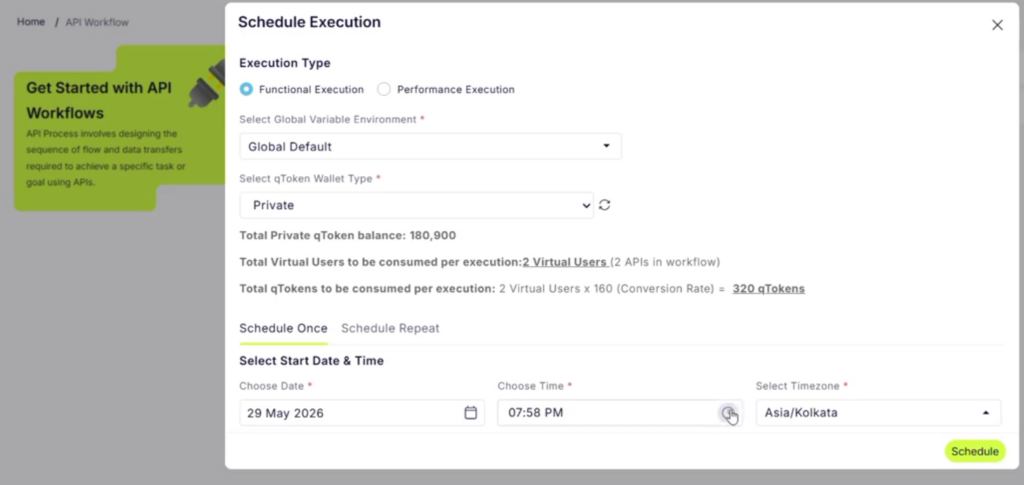
Direct Workflow Automation: Listing Page Scheduling!

Listing Page Scheduling

The Challenge:  

To keep up with continuous integration demands, automation engineers need to schedule their API testing workflows quickly and efficiently. Previously, the workflow listing page served strictly as a static directory. If you wanted to schedule a specific workflow to run automatically, you had to leave the high-level overview, navigate deep into the individual workflow’s configuration settings, and apply your scheduling rules there. This extra navigation loop slowed down management tasks and added unnecessary clicks to a routine process. 

The Fix:  

We have integrated scheduling capabilities directly onto the API workflow listing page. You can now configure, activate, and manage execution schedules for any workflow immediately from the main listing view, supported by an updated, streamlined UI design. 

How will it help?  

This workflow upgrade streamlines your continuous automation planning. 

  • Rapid Automation Planning: Schedule your API testing workflows on the fly right from the directory page, bypassing unnecessary clicks and navigation loops. 
  • Centralized Management: View your list of workflows and adjust their execution rules from a single, unified control pane, making it easier to orchestrate your overall automation strategy. 
  • Frictionless CI Coordination: Quickly coordinate and adjust automated test runs to match changing deployment schedules or sprint deadlines with absolute ease. 

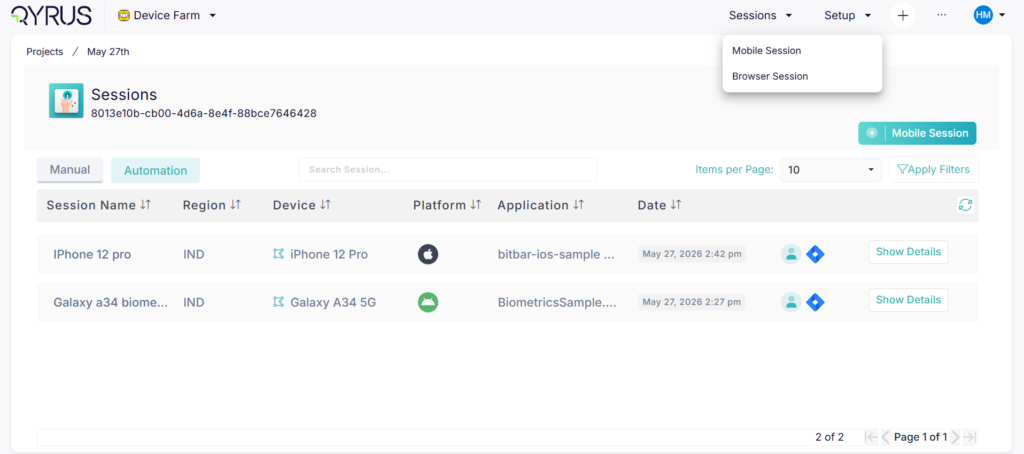
Controlled Rollouts: Feature Flags for AI Device Farm Sessions!

Feature Flags for AI Device Farm Sessions

The Challenge:  

Integrating cutting-edge AI capabilities into real mobile device testing requires careful, managed deployment. Previously, new AI-powered session types in the Device Farm were universally visible in the UI. This made it difficult to perform targeted beta testing, manage resource-intensive features, or selectively roll out experimental capabilities to specific teams without cluttering the interface for the rest of the user base. 

The Fix:  

We have introduced a robust feature flag system (enableDeviceFarmAISession) specifically for AI-powered Device Farm sessions. This backend control allows us to granularly toggle access to these advanced testing environments. To support this controlled rollout, we have also streamlined the user interface by dynamically removing the “AI Session” option from the general Sessions dropdown menu, ensuring it is only visible when explicitly enabled for a specific workspace. 

How will it help?  

This infrastructure update provides absolute control over how AI features are introduced into your testing environment. 

  • Targeted Beta Testing: Safely introduce and test experimental AI capabilities with specific engineering teams without disrupting the standard Device Farm experience for everyone else. 
  • Clutter-Free Interface: Keep the testing UI clean, intuitive, and focused by hiding advanced, specialized AI session options from users who do not actively need them. 
  • Scalable Rollouts: Grant administrators precise, behind-the-scenes control over how and when cutting-edge AI testing tools are deployed across the platform. 

Rock-Solid Device Provisioning: Hardened Provider Lifecycle Handling!

The Challenge:  

Interacting with remote cloud infrastructure requires highly resilient backend communication. Previously, the Device Farm Microservice (DFM) relied on default handling for provider Device Farm sessions. This meant that transient network blips during device readiness checks could cause an entire test session to fail prematurely, while concurrent or duplicate session creation requests could lead to race conditions. Additionally, non-idempotent session termination routines and unmapped SDK exceptions occasionally resulted in generic, unhelpful server errors, making it difficult to pinpoint whether a failure was due to an invalid configuration or a temporary cloud glitch. 

The Fix:  

We have hardened the provider session lifecycle management inside the Device Farm Microservice to drastically increase backend stability. The engine now features distributed create-time locking to eliminate concurrent session creation conflicts, explicit exception mapping (translating specific faults directly to clear HTTP error codes), and dedicated retry and timeout rules for the SDK client. Furthermore, we built transient fault resilience directly into the device polling loop and ensured the session termination endpoint is fully idempotent—meaning it will gracefully clean up resources without throwing errors if a session is already stopped. 

How will it help?  

These deep infrastructure improvements ensure an incredibly stable and predictable remote device testing experience. 

  • Immunity to Transient Blips: Short-lived network fluctuations or minor AWS hiccups will no longer kill your test runs; the platform now intelligently retries and continues polling behind the scenes. 
  • No More Race Conditions: Distributed create-time locking ensures that duplicate or retried device requests are safely queued and managed, preventing conflicting or broken device states. 
  • Graceful Cleanups & Faster Debugging: Clearer error mapping replaces generic server errors with actionable feedback, while idempotent session handling ensures cleaner resource teardowns and fewer noisy, false-alarm logs. 

Resilient Workflows: Combined Optional Execution & Session Persistence!

Combined Optional Execution and Session Persistence

The Challenge:  

In complex test orchestrations, maintaining a continuous state across multiple test steps (Session Persistence) while allowing non-critical steps to fail without stopping the whole run (Optional Execution) is a powerful combination. Previously, these two features were mutually exclusive in Test Orchestration. Turning on “Optional Execution” would automatically force “Session Persistence” off. This meant a failure in an optional setup or cleanup step would either completely kill the persistent session or force teams to split their unified workflows into disconnected parts. 

The Fix:  

We have fully integrated Optional Execution to work seamlessly alongside Session Persistence. The orchestration engine has been updated to handle failures within a persistent session gracefully. Now, if an orchestrated node designated as “Optional” encounters a failure, the platform intelligently preserves the active session state and securely hands it off to the next node in the pipeline instead of tearing down the environment. 

How will it help?  

This update unlocks advanced, highly resilient test scheduling configurations for complex end-to-end scenarios. 

  • Flawless Multi-Step Resiliency: Build extensive end-to-end testing chains that reuse the same active state, confident that minor, non-critical failures won’t tank your entire execution pipeline. 
  • Smart Failure Recovery: If an optional validation or data-gathering script fails mid-session, the platform automatically bypasses the fault, keeps the application state alive, and carries on to subsequent verification steps. 
  • Uncompromised Workflow Logic: Eliminate the need for messy workarounds or custom scripting just to keep a testing window open when a secondary step runs into an unexpected hitch. 

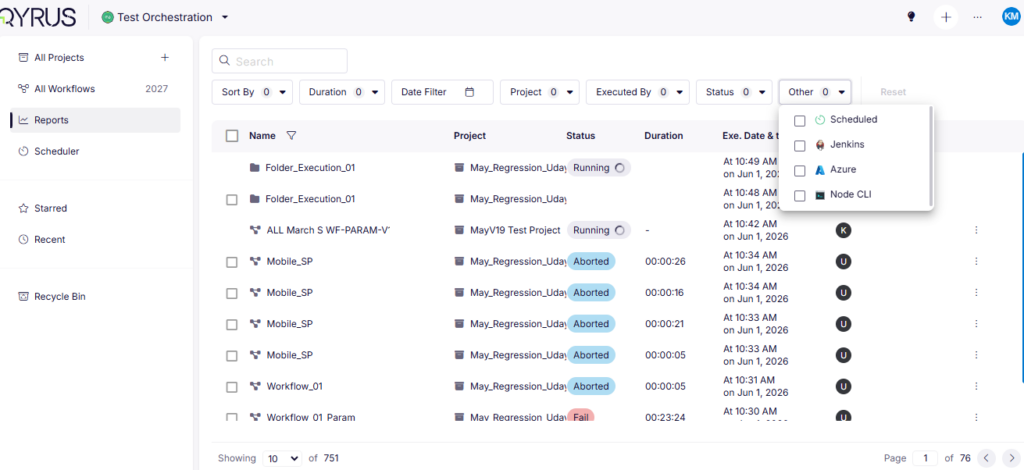
Precision Analysis: Enhanced Report Page Filters!

Enhanced Report Page Filters

The Challenge:  

As enterprise teams scale their automation efforts, the volume of test reports generated daily can become overwhelming. Navigating through thousands of execution records to find a specific run can feel like hunting for a needle in a haystack. Previously, limited filtering options on the Test Orchestration Reports page made it difficult to quickly isolate runs based on how they were triggered or configured, creating administrative bottlenecks during post-execution analysis. 

The Fix:  

We have significantly upgraded the Reports Page with a suite of new, advanced filtering options. You can now slice and dice your test data using specialized Schedule Type and Other filters. This allows you to dynamically narrow down your execution history by specific parameters, including Once, Hourly, Daily, Weekly, Scheduled, and Session Persisted execution profiles. 

How will it help?  

These new filters give you total control over your reporting data, dramatically speeding up triage and auditing tasks. 

  • Instant Execution Triage: Quickly separate routine, automated nightly regression runs from manual, ad-hoc test executions with a single click. 
  • Isolate Persistent Sessions: Effortlessly track down and review reports tied specifically to your Session Persisted workflows to evaluate state retention across multi-step runs. 
  • Streamlined Audit Trails: Seamlessly monitor recurring test patterns (such as hourly health checks or daily smoke tests) to identify historical flake rates or performance trends across specific schedules. 

Ready to Leverage June’s Innovations? 

We are committed to providing a unified platform that not only adapts to your evolving needs but also streamlines your critical processes, empowering you to release high-quality software with greater speed and confidence. 

Eager to explore how these advancements can transform your testing efforts? The best way to appreciate the Qyrus difference is to experience these new capabilities directly. 

Ready to dive deeper or get started? 

Book a Personalized Demo

The truth about test automation is pretty simple: most teams use up time looking after their tests than they do making them. The World Quality Report says that looking after tests uses up to 50 percent of the test automation budget. For teams that have to deal with more than 1,000 tests it gets even worse. Up to 60 percent of all the time spent on quality assurance goes into this. This is not a problem with how people work. The real problem is the framework they are using. 

When you pick a test automation framework, you are not just choosing a tool. You are making a decision that affects how your tests will work overtime. If you make a choice, your team can work faster and feel more confident. If you make a bad choice, you will spend all your time fixing scripts that break every time something small changes like a button being moved.  

The following sections will help you look at the types of test automation frameworks. We will see what makes BDD and TDD approaches different from each other. Test automation frameworks are a part of this. We will also look at the role of component testing, in test automation strategies. We will talk about the problems that come with taking care of code-centric test automation frameworks. Test automation frameworks are still a part of this. Then we will see how AI-native testing platforms are handling those problems in a way.What Is a Test Automation Framework? 

A test automation framework is like a plan that shows how to create, run and keep tests for a software project. It gives rules, reusable parts, ways to handle test data steps to run tests and systems to report results. This helps keep automation consistent as test coverage expands. This difference is important. Selenium and Playwright are tools. A framework built on Playwright with test data, simple test scripts and integration with integration/continuous deployment (CI/CD) is a framework. The framework is like a structure. The tool is just one part of it. A well-designed test automation framework typically includes: 

  • Test environment setup for version management, environment configurations, and prerequisites 
  • Test data management for sourcing, storing, and passing data between test cases 
  • Test execution mechanisms that control how tests are triggered and run 
  • Logging and reporting for capturing results, screenshots, logs, and failure details 
  • CI/CD integration for incorporating automated tests into delivery pipelines 
  • Reusable components such as shared libraries, functions, and utilities that reduce duplication 

Together, these elements provide the structure needed to manage automation at scale. They help teams standardize how tests are developed, executed, and maintained across projects and environments. As more tests are added the framework helps keep things consistent and easy to maintain.  

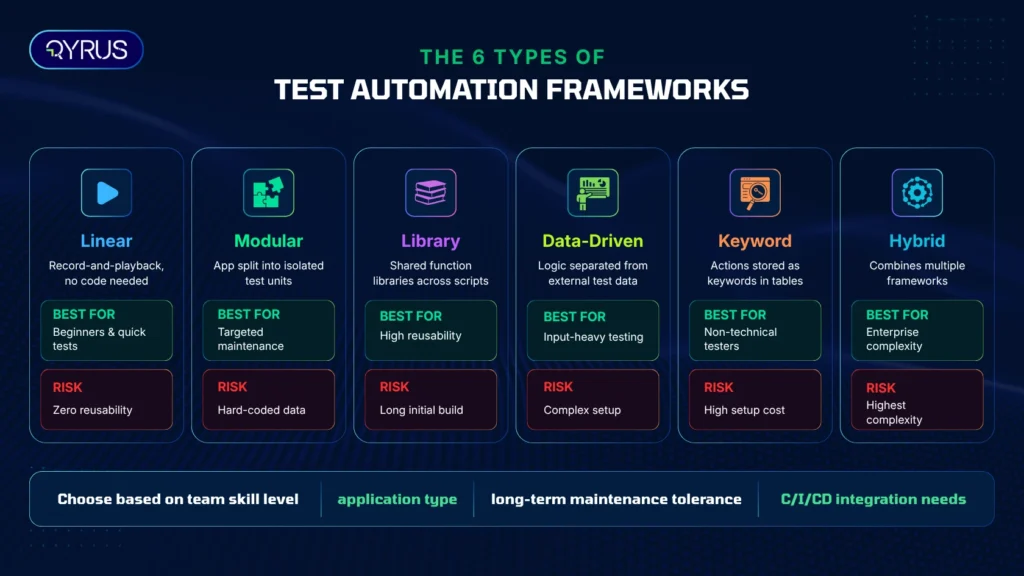
The 6 Types of Test Automation Frameworks Explained 

Not all automation testing frameworks are built the same. Each type makes a different trade-off between ease of setup, scalability, reusability, and required programming knowledge. Here are the six you need to know. 

qyrus-framework-types

1. Linear (Record-and-Playback) Framework 

The simplest entry point into test automation. A tester records each user action, navigation, inputs, clicks, and the tool plays them back as a test script. No coding is required. Scripts are generated automatically and run sequentially. 

Best for: beginners, quick validations, and short-term projects with minimal change cycles. 

Key limitation: test data is hard-coded directly into each script. If your application changes, even a single UI element, every affected script needs manual updates. This framework does not scale. 

2. Modular Testing Framework 

Modular testing breaks the application under test into isolated units, login, checkout, search, and creates an individual test script for each. Larger test scenarios are assembled by combining these modules in sequence. 

The abstraction layer is this framework’s core strength: changes to one module do not cascade into the rest. This makes targeted maintenance far more efficient than the linear approach. 

Key limitation: test data is still hard coded at the module level, so running the same scenario with multiple data sets means duplicating scripts. Programming knowledge is also required to build and manage the module structure. 

3. Library Architecture Framework 

A natural evolution of the modular approach. Instead of organizing by application section, this framework identifies common functions, login, form submission, API calls, and groups them into a shared function library that any test script can call. 

The result is a higher degree of reusability. A single function handles repeated action across the entire test suite. Update the function once, and every script that calls it benefits automatically. 

Key limitation: test data remains hard-coded. Building and maintaining the shared library requires solid programming expertise, and initial development time is longer than simpler approaches. 

4. Data-Driven Framework 

Here is where things get meaningfully more powerful. A data-driven framework separates test data from script logic entirely. Test scripts are written once; data is stored externally in files such as Excel spreadsheets, CSV files, SQL tables, or JSON. The framework reads each row of data and executes the same script with a different dataset on each pass. 

One script. Dozens of test scenarios. This approach is ideal for input-heavy applications, registration flows, payment processing, search, where you need to validate the same logic with many different values. 

Key limitation: setting up a data-driven framework requires an experienced engineer who can manage external data sources and write the connection logic between the data file and the test scripts. Initial setup investment is high. 

5. Keyword-Driven Framework 

A framework driven by keywords extends the separation principle. Keywords — simple action labels like ‘ClickButton’, ‘EnterText’, or ‘VerifyPageTitle’ — are kept in an external table together with the objects they operate on. During the test execution, the engine interprets each keyword, associates it with the relevant code, and carries out the action. 

The primary benefit is easy access. Non-technical stakeholders can access and even participate in test design without needing to code. One keyword may be utilized in various test scripts, and tests can be developed separately from the application being tested. 

Main drawback: the upfront setup expense is substantial and requires a considerable amount of time. Keyword tables and object repositories need to be diligently managed. As the test suite expands, managing keywords becomes a separate administrative burden. 
 

6. Hybrid Testing Framework 

As automation programs grow, teams often combine multiple framework approaches instead of relying on just one. For example, a team may use a data-driven model for handling large test datasets while using keywords to simplify test creation and maintenance. This combination is commonly referred to as a hybrid framework. Most enterprise test automation environments converge on hybrid frameworks because real-world applications are complex enough to need flexibility. A hybrid framework can support multiple testing types, accommodate mixed team skill sets, and adapt as the application evolves. 

Key limitation: Building and maintaining a hybrid framework demands experienced engineers, strong documentation, and disciplined governance. Without it, hybrid frameworks become the most expensive kind to maintain. 

Framework Comparison at a Glance 

Framework Type 

Best For 

Key Limitation 

Linear / Record-and-Playback 

Beginners, short-term projects 

Not reusable; breaks on any change 

Modular 

Structured apps, targeted maintenance 

Hard-coded data; needs coding skills 

Library Architecture 

High reusability needs 

Long initial build; coding expertise required 

Data-Driven 

Input-heavy, multi-scenario testing 

Complex setup; data management overhead 

Keyword-Driven 

Non-technical stakeholders in QA 

High initial cost; maintenance at scale 

Hybrid 

Enterprise, complex applications 

Highest complexity; demands strong governance 


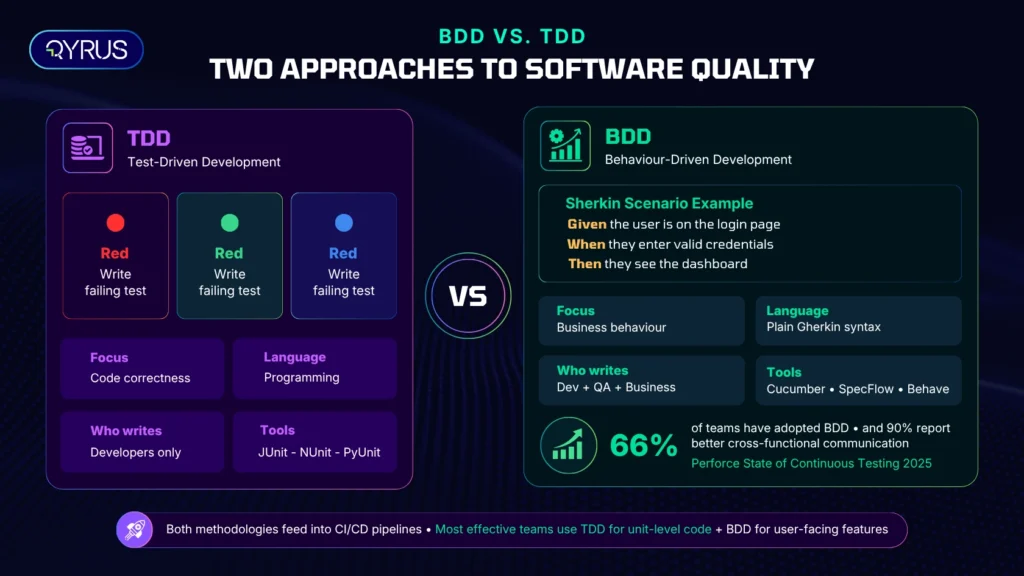
BDD vs. TDD: Two Philosophies That Shape Your Framework Choice 

Test-Driven Development (TDD) and Behavior-Driven Development (BDD) are two development methodologies that have an impact on how teams create their automation frameworks. They are often talked about together. They really deal with different problems. 

qyrus-bdd-vs-tdd

What Is Test-Driven Development (TDD)? 

 
TDD is an approach for developers which is simple and repeatable. 

Here is how it works: 

  • Create a test that fails at first. 
  • Write enough code so the test passes. 
  • Then improve the code. 

This is called the Red-Green-Refactor cycle. Developers must follow this way of working, which is a method and also a discipline. 

The objective is code accuracy. TDD makes developers think about how the code will work, what could go wrong and what will happen if something fails. They do this before they start writing the code. This means that each part of the code has a test that was written before the code itself.  

TDD is most effective at the unit level: testing individual functions, methods, or classes in isolation. Popular TDD frameworks include JUnit (Java), NUnit (.NET), and PyUnit (Python).  

What TDD does not address well is bridging the gap between the side of things and what the business actually needs. When we write a test in Java, it checks if a function gives us the answer. It does not tell us if we built the feature that the business really wanted. TDD is about making sure the code works. It does not say if we are building the right thing. The business wants certain features, and TDD does not always address this. 

What Is a Behavior Driven Development (BDD) Framework? 

BDD evolved from TDD specifically to bridge that gap. Where TDD is written in programming languages and read by developers, BDD is written in plain, structured language that business stakeholders, product managers, and QA engineers can all read and contribute to. 

 The language used for BDD is called Gherkin. It is a way of describing how the code should work using a Given/When/Then format. This format describes what the user will see when they use the code. 

				
					Feature: User Login 

  Scenario: Successful login with valid credentials 

    Given the user is on the login page 

    When they enter a valid username and password 

    Then they should be redirected to the dashboard


Non-technical stakeholders can easily check this scenario without needing to know any code. The BDD test turns into a plan that the whole team agrees before they start building anything. When the test works, the feature is complete. If the test fails, everyone can see where the problem is. The team can then fix the issue and make sure the feature works as expected. 

The adoption figures reflect how much teams value this collaboration. According to the 2025 State of Continuous Testing Report by Perforce, BDD adoption has reached 66% among development teams, and 90% of teams that adopted BDD report better communication across functions.  Popular BDD frameworks include Cucumber (multi-language), SpecFlow (.NET), and Behave (Python). 

TDD vs. BDD: Side-by-Side Comparison 

Dimension 

TDD 

BDD 

Focus 

Code correctness 

Business behaviour 

Written in 

Programming language 

Plain language (Gherkin) 

Who writes tests 

Developers 

Developers, QA, and business stakeholders 

Test level 

Unit / component 

Integration / acceptance 

Collaboration scope 

Technical team 

Cross-functional team 

Best suited for 

Internal code quality 

User-facing features and workflows 

Popular tools 

JUnit, NUnit, PyUnit 

Cucumber, SpecFlow, Behave 


The most effective teams do not choose one over the other. They apply TDD to low-level components, where code correctness is the primary concern, and BDD to user-facing features, where alignment with business requirements matters most. The two methodologies complement each other rather than compete. 

Playwright Component Testing vs. Cypress Component Testing: What’s the Difference? 

 When people become more skilled at testing, they usually start using component testing. This is like a step between unit tests and full end-to-end (E2E) runs.  Of pretending the whole application is there or just looking at one function component testing puts a real component in a real browser and lets testers use it like a real user would. They can click on things, type, and hover over things. They can also control what the component looks like and how it works. This way you get to see what the component really looks like in a browser without having to set up the application, which can be slow and unreliable. 

 There are two frameworks that people use for this in 2026: Playwright and Cypress. Both mount components in a real browser. They differ sharply in architecture, speed, and developer experience. 

Playwright Component Testing 

 Playwright is backed by Microsoft. It uses a way of working that talks directly to browsers using the Chrome DevTools Protocol (CDP). This design makes it 20 times faster than browser-in-process frameworks and delivers significantly lower test flakiness rates. 

Playwright component testing is parallel by default, free to run at scale, and supports TypeScript, JavaScript, Python, Java, and C#/.NET. As of early 2026, Playwright averages 20–30 million weekly NPM downloads, and the State of JavaScript 2025 survey recorded a satisfaction score of 91%, the highest ever measured for a testing framework at this scale. 

Reach for Playwright when:  you need to do things and at the same time. It is also good if your team is used to working with async/await patterns. If you need to work with languages or if you are starting a new project Playwright is a good choice. 

Caveat: Playwright’s component testing feature is still marked experimental. The API surface may change between releases. 

Cypress Component Testing 

Cypress works inside the browser with the application you are testing.This architecture makes it exceptionally fast for debugging: the time-travel GUI lets engineers step backward through test execution frame by frame, which is genuinely the best visual debugging experience available in any testing framework today. 

 Cypress testing for parts of the application is solid and reliable. It is part of the same tool you use for end-to-end testing with Cypress. This means you only have to think about one way of doing things, and you only have to set it up. The people who make extras, for Cypress have made a lot of tools that work well with it like tools to check how things look and tools to make sure everything is accessible. 

Reach for Cypress when: you already run Cypress for E2E testing, your team prizes interactive visual debugging, or your application has a complex custom bundler configuration that Cypress can reuse. 

Playwright vs. Cypress: Head-to-Head 

Dimension 

Playwright 

Cypress 

Architecture 

Out-of-process (CDP) 

In-browser (same run loop) 

Speed 

Faster (parallel by default, free) 

Moderate (Cloud plan for parallelism) 

Language support 

JS, TS, Python, Java, C# 

JavaScript / TypeScript only 

Debugging experience 

Trace viewer (excellent for CI) 

Time-travel GUI (best for local dev) 

Component testing status 

Experimental 

Stable / GA 

CI cost 

Lower (free parallelism) 

Higher (Cypress Cloud subscription) 

Best for 

Greenfield, multi-language, scale 

Existing Cypress suites, frontend DX 


The honest 2026 verdict: for new projects, Playwright is the stronger default choice. Cypress remains compelling for teams as it already invested in its ecosystem and for anyone who finds its debugging experience genuinely more productive. Both are excellent tools, but both are still code-first frameworks, which brings us to the problem that neither fully solves. 

The Real Problem with Traditional Test Automation Frameworks: Maintenance 

Selecting a framework type is the easy part. Keeping it alive is where most teams fail. 

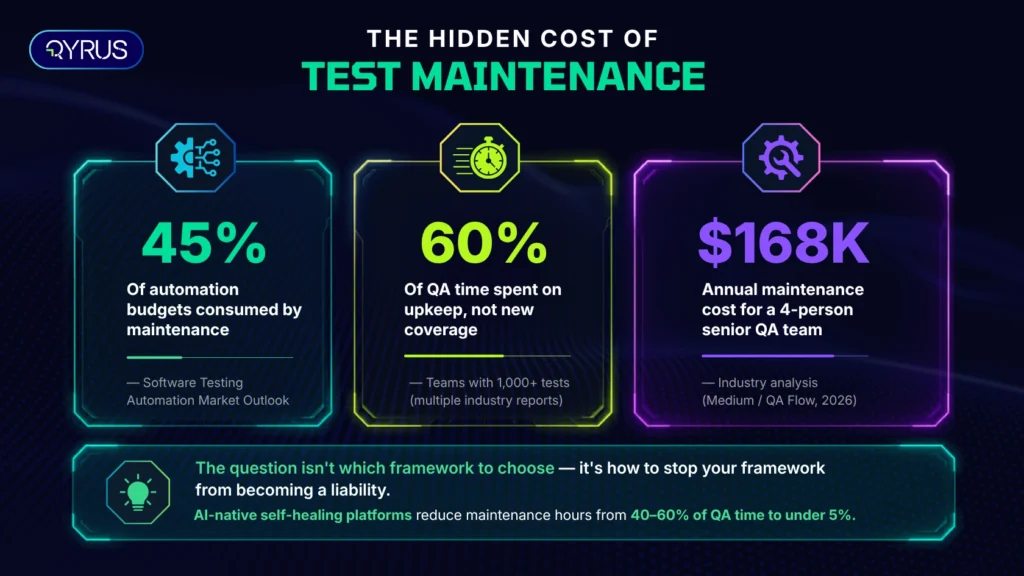
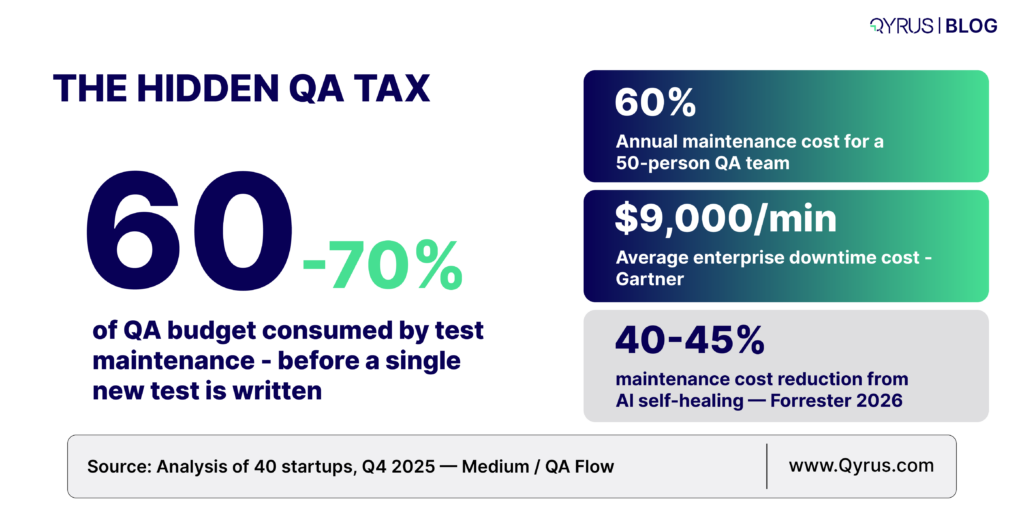
Consider the numbers: maintenance consumes 45% of automation budgets on average. Teams maintaining more than 1,000 tests report spending 60% of their time on upkeep rather than new test development. Across a four-person senior QA team, where each engineer earns roughly $140,000 per year, that translates to approximately $168,000 annually spent on maintaining tests, not improving coverage. 

qyrus-maintenance-stat-card

The root causes are consistent regardless of which framework type a team chooses: 

  • Brittle locators: element IDs, XPaths, and CSS selectors break every time the UI is updated. Even minor redesigns require manual script triage across hundreds of tests. 
  • Hard-coded test data: without clean data separation, any change to the underlying data model requires touching individual scripts rather than a central source. 
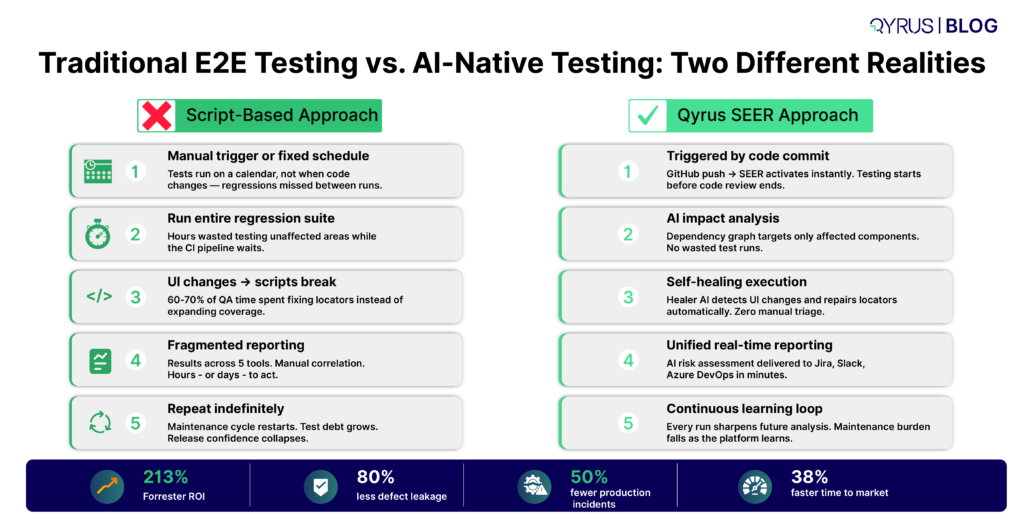
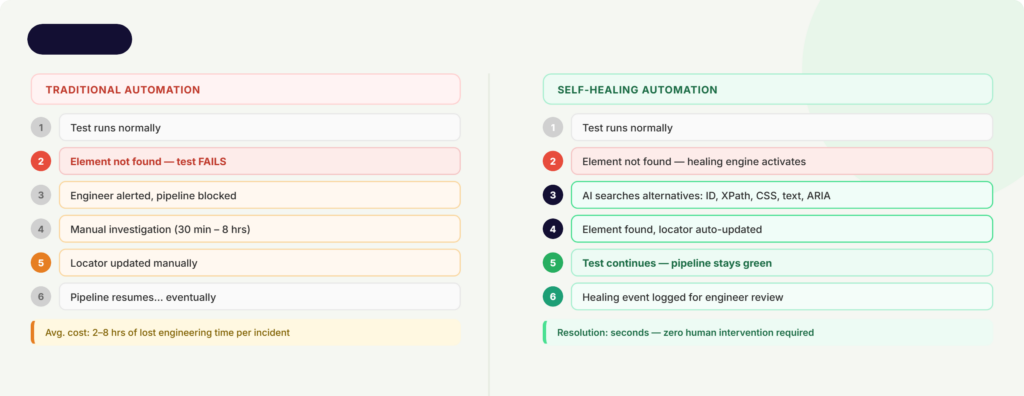
  • No self-healing: traditional frameworks are passive. When something breaks, a human must diagnose, locate, and fix it. The framework itself offers no intelligence about what changed or why. 

Here is the pattern across engineering teams that analysis has consistently surfaced: 60–70% of QA time goes to test upkeep. Only 30–40% goes to add coverage or review results. That ratio is backwards, and code-first frameworks, no matter how well architected, cannot correct it on their own. 

The question that matters most is not which framework type to choose. It is: how do you stop your test automation framework from becoming a liability the moment your application starts moving quickly? 

45% 

of automation budgets consumed by test maintenance 

— Software Testing Automation Market Outlook, IntelMarketResearch 

How Qyrus Takes the Framework Burden Off Your Team 

Qyrus is not another code-first framework with a cleaner UI. It is an AI-native, no-code testing platform built to solve the maintenance problem at its root, not patch it after the fact. Where traditional frameworks require skilled engineers to build, maintain, and repair the infrastructure around testing, Qyrus makes that infrastructure autonomous. 

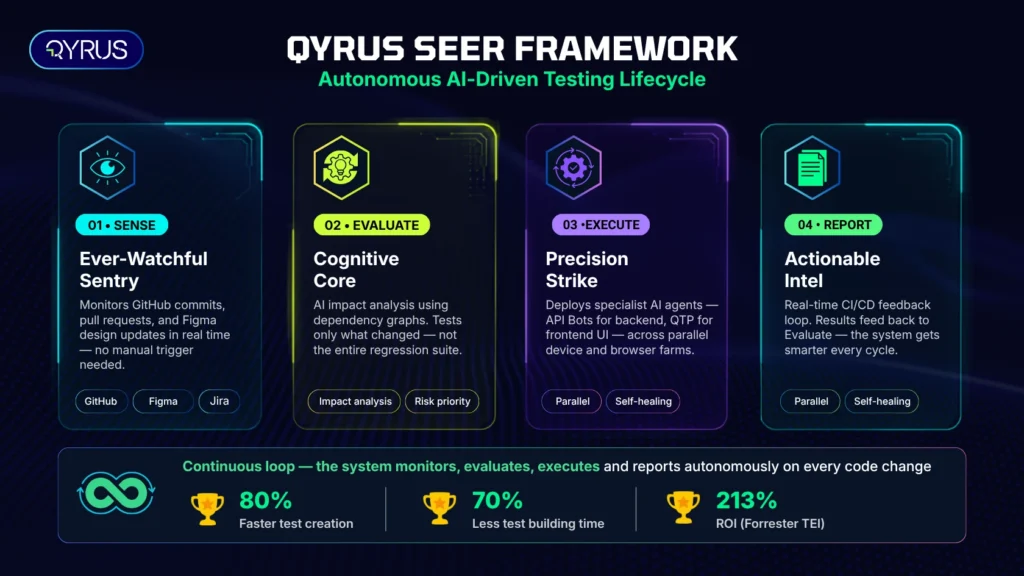
The SEER Framework: Autonomous Test Orchestration 

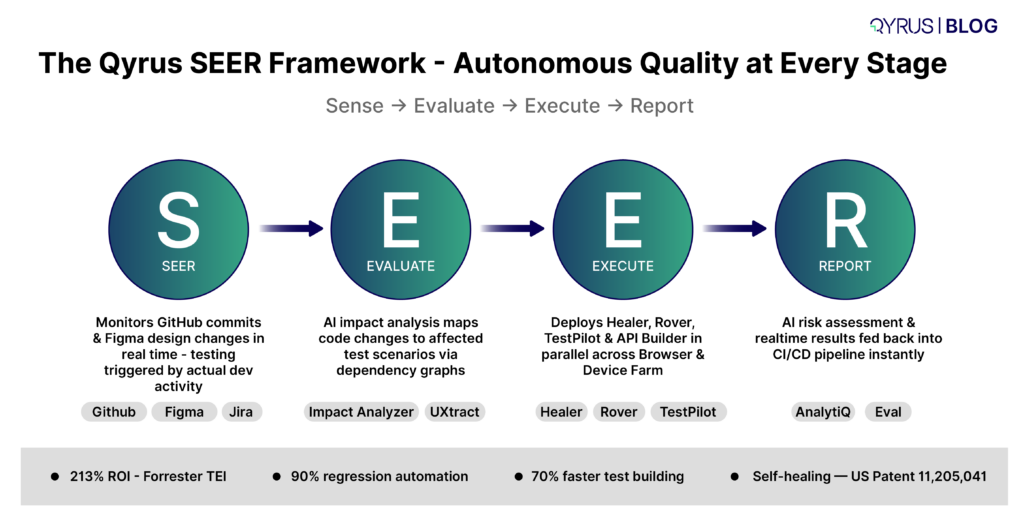
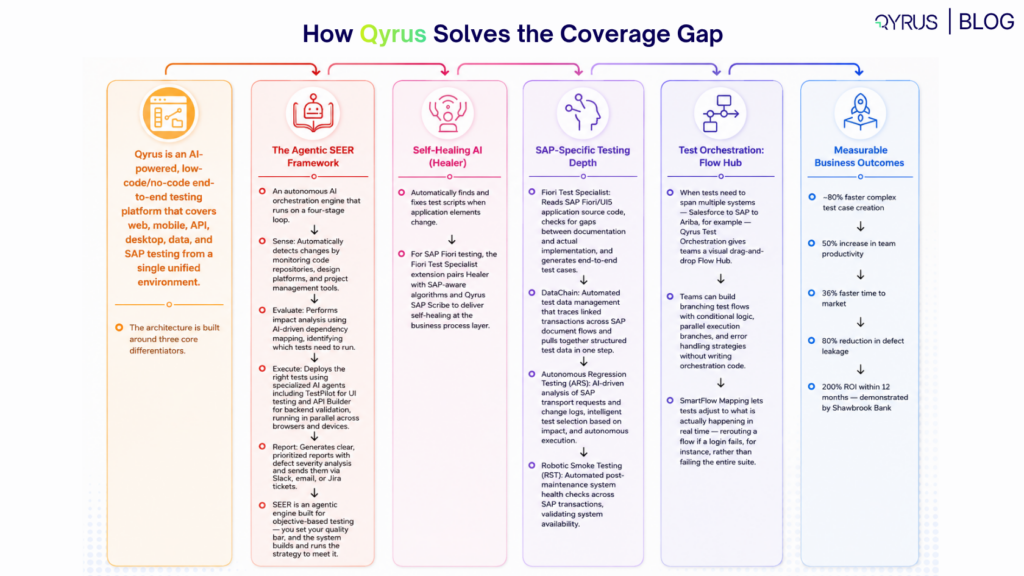
At the core of Qyrus sits the industry-first SEER (Sense, Evaluate, Execute, Report) framework, an agentic AI engine that manages the entire testing lifecycle without manual hand-offs. 

  • Sense: monitors code repositories (GitHub) for commits, merges, and pull requests; detects UI/UX changes in Figma as they happen 
  • Evaluate: performs automated impact analysis using static analysis and dependency graphs, identifying exactly which APIs and UI test scenarios are affected by a change, not the entire regression suite 
  • Execute: autonomously deploys the right specialist agents, API Bots for backend validation, Qyrus Test Pilot (QTP) for frontend testing, without human selection 
  • Report: delivers real-time insights into test outcomes and coverage, feeding results back into the CI/CD pipeline as a continuous learning loop 

The SEER framework means your test automation framework no longer waits to be told a change occurred. It observes, responds, and executes, continuously. 

qyrus-seer-framework

Healer AI: Self-Healing That Actually Works 

The single biggest cause of framework maintenance overhead is broken locators. Qyrus solves this with Healer AI, a patented self-healing engine (U.S. Patent 11,205,041 B2) that references a successful baseline script and automatically suggests updated locators (ID, Class, XPath) when UI elements change. 

When Healer detects a failed step due to a UI change, it scans the application, identifies the corrected element, and applies the fix, without a human ever opening the script. For web testing teams, this directly attacks the locator fragility that accounts for the majority of maintenance work. 

No-Code Test Building at Scale 

Qyrus offers 115 distinct action types across web, mobile, and API testing, all accessible through a low-code/no-code interface that requires no programming knowledge to operate. Tests can be created manually, imported from Jira tickets, or generated from natural language descriptions via Nova AI. 

TestGenerator+ goes further: it analyses your existing scripts and automatically generates additional test scenarios to fill coverage gaps, categorizing each new scenario by criticality (Low, Medium, High, Critical) before any human reviews the output. 

Parallel Execution Across a Real Device and Browser Farm 

For mobile testing and web testing alike, Qyrus provides access to a cloud-based browser farm (Chrome, Edge, Firefox, Safari, including previous and custom versions) and a real-device farm covering Android and iOS. Tests run in parallel across all of them simultaneously, with zero infrastructure overhead. 

This eliminates the device lab maintenance that typically consumes a separate slice of QA budget and removes the bottleneck of sequential test runs that inflate feedback cycle times. 

A Unified Platform Across Every Testing Type 

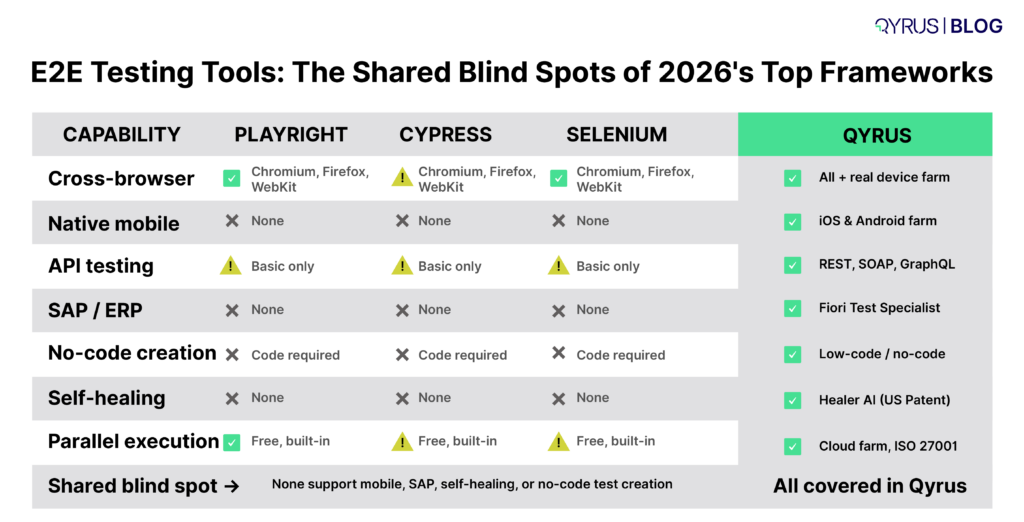
Traditional frameworks are fragmented by testing type: one tool for web, another for mobile, another for API testing, another for SAP. Each one has its own maintenance burden, its own script library, and its own skill requirement. Qyrus consolidates Web, Mobile, API, Desktop, SAP, and Data testing into a single platform, one interface, one team, and one source of truth. 

The Numbers 

Metric 

Qyrus Impact 

Test case creation speed 

~80% faster for complex scenarios 

Team productivity 

50% increase 

Test building time 

70% reduction via AI-driven, codeless features 

ROI 

213% within 12 months (Forrester TEI study) 

Production incidents 

50% reduction through proactive AI detection 


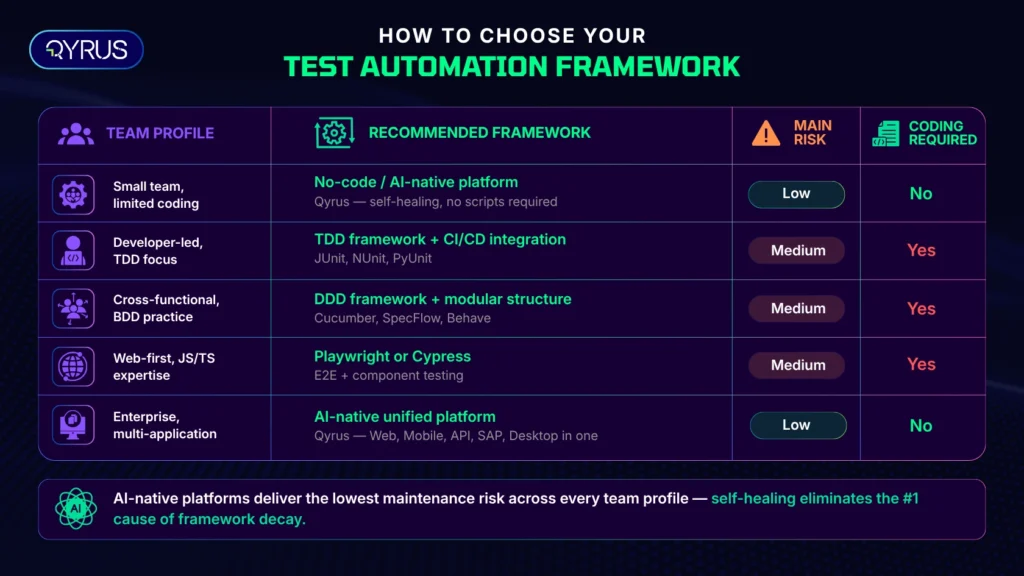
How to Choose the Right Test Automation Framework for Your Team 

qyrus-framework-decision-matrix

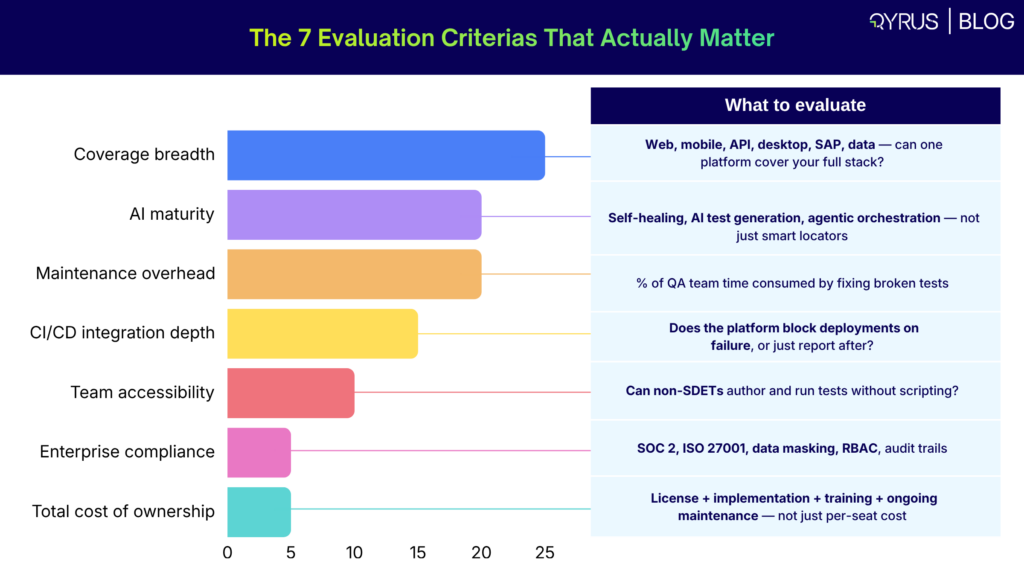
There is no universally correct framework. The right choice depends on five factors that are specific to your team, your application, and your risk tolerance. 

  1. Team skill level: Code-first frameworks (Playwright, Cypress, Selenium) require engineers who can build, govern, and maintain them long-term. If your team includes non-technical QA contributors or you are resource-constrained, a no-code or low-code platform substantially lowers the barrier to entry and the ongoing cost of ownership. 
  1. Application type: Web-only applications have the widest framework choice. Mobile applications narrow the field to frameworks with Appium support or native real-device testing. Cross-platform environments, web, mobile, API, and backend together, need either a unified platform or a deliberately integrated multi-framework strategy. 
  1. Testing methodology preference: If your team practices BDD, your framework needs native Gherkin/Cucumber support and reporting that non-technical stakeholders can read. If you are TDD-heavy, unit-level framework depth matters more than business-language output. 
  1. CI/CD integration needs: Your automation framework should integrate natively with the tools already in your pipeline, Jenkins, Azure DevOps, GitHub Actions, Bitrise, TeamCity. Frameworks that require custom plugins or workarounds to connect create integration debt that compounds over time. 
  1. Maintenance tolerance: This is the factor most teams underweight. Ask honestly: how much of your annual QA budget can sustainably go to maintaining tests rather than building new ones? If the honest answer is ‘not 45%’, then a framework with self-healing AI or no-code test repair is not a luxury; it is a financial necessity. 

Quick Decision Guide 

Team Profile 

Recommended Approach 

Small team, limited coding resources 

No-code / AI-native platform (e.g. Qyrus) 

Developer-led, unit-testing focus 

TDD framework (JUnit, PyUnit) + CI/CD integration 

Cross-functional team, BDD practice 

BDD framework (Cucumber, SpecFlow) + modular structure 

Web-first, advanced JS/TS expertise 

Playwright or Cypress (E2E + component testing) 

Enterprise, multi-application landscape 

Hybrid framework or unified AI-native platform 


Frequently Asked Questions About Test Automation Frameworks 

What is a test automation framework? 

A test automation framework is a structured set of guidelines, tools, and reusable components that govern how automated tests are built, executed, and maintained, providing consistency, scalability, and reduced long-term maintenance cost across a team’s testing process. 

What are the main types of automated testing frameworks? 

The six primary types are: Linear (Record-and-Playback), Modular, Library Architecture, Data-Driven, Keyword-Driven, and Hybrid. Each makes different trade-offs between ease of setup, scalability, and required programming knowledge. 

What is the difference between BDD and TDD? 

TDD (Test-Driven Development) is a developer-centric methodology where tests are written before code, using programming language-specific frameworks like JUnit or NUnit. BDD (Behavior-Driven Development) evolved from TDD and uses plain-language Gherkin syntax (Given/When/Then) so that business stakeholders, QA engineers, and developers can all read and contribute to test scenarios. TDD focuses on code correctness; BDD focuses on business behavior. 

What is a BDD example using Gherkin syntax? 

A simple BDD example for a login feature: Given the user is on the login page / When they enter valid credentials / Then they should be redirected to the dashboard. This scenario is readable by anyone on the team, no coding knowledge required. 

What is Playwright component testing? 

Playwright component testing mounts individual UI components in a real browser, rather than a simulated DOM, and lets testers interact with them using real events. It offers fast, parallel-by-default execution and supports multiple programming languages. As of 2026, it is marked experimental but is widely used in production by engineering teams that prioritize speed and parallelism. 

Do I need coding knowledge to use a test automation framework? 

For traditional code-first frameworks like Selenium, Playwright, or Cypress, yes, you need solid programming knowledge. For no-code and AI-native platforms like Qyrus, you do not. Qyrus offers 115 action types accessible through a visual interface, along with AI-powered test generation from plain-language descriptions and Jira tickets. 

Stop Maintaining Frameworks. Start Shipping Quality. 

The type of test automation framework your team chooses matters. But in 2026, what matters more is whether that framework can keep up with your application, without consuming half your QA budget in maintenance the moment it does. 

Code-first frameworks, whether linear, modular, data-driven, or even Playwright and Cypress, are powerful tools in skilled hands. But they are fundamentally passive systems. They break when your application changes. They wait for humans to fix them. They accumulate debt quietly until the team starts dreading the test suite rather than trusting it. 

The teams that will lead on software quality in the years ahead are those whose testing infrastructure adapts, self-heals, and integrates continuously, not those who schedule sprint time to patch broken locators. 

Qyrus is built for that standard. If you are ready to move beyond the maintenance trap and build a test automation strategy that scales with your product, book a demo with the Qyrus team today and see the SEER framework in action. 

Qyrus Blog Featured Image thumbnail 2026-2

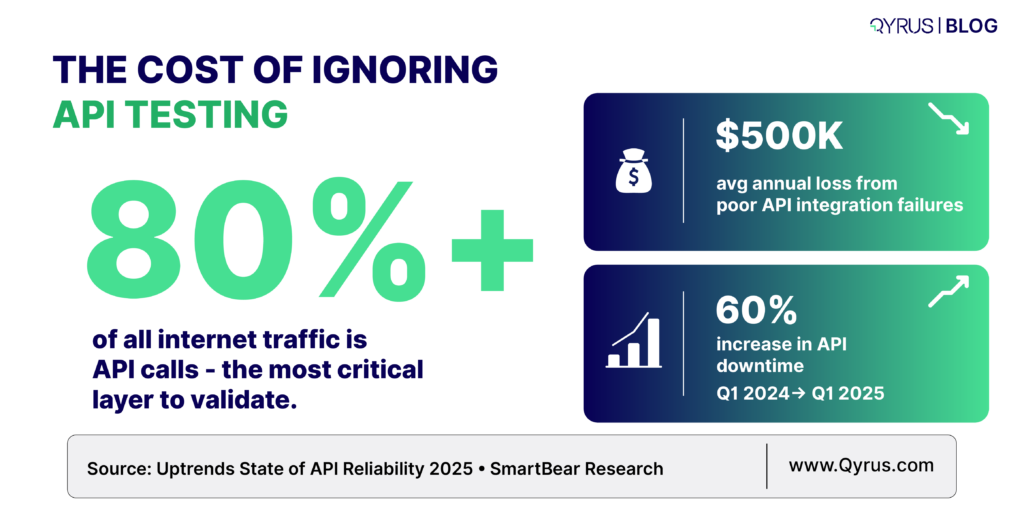
83% of public APIs are built using REST architecture  

REST API testing is the process of validating the requests, responses, authentication mechanisms, error handling, and performance characteristics for a RESTful web service — without touching the user interface.  

It is one of the most powerful techniques a development team can implement to catch defects early, add contracts between services, and ensures product works before every release. 

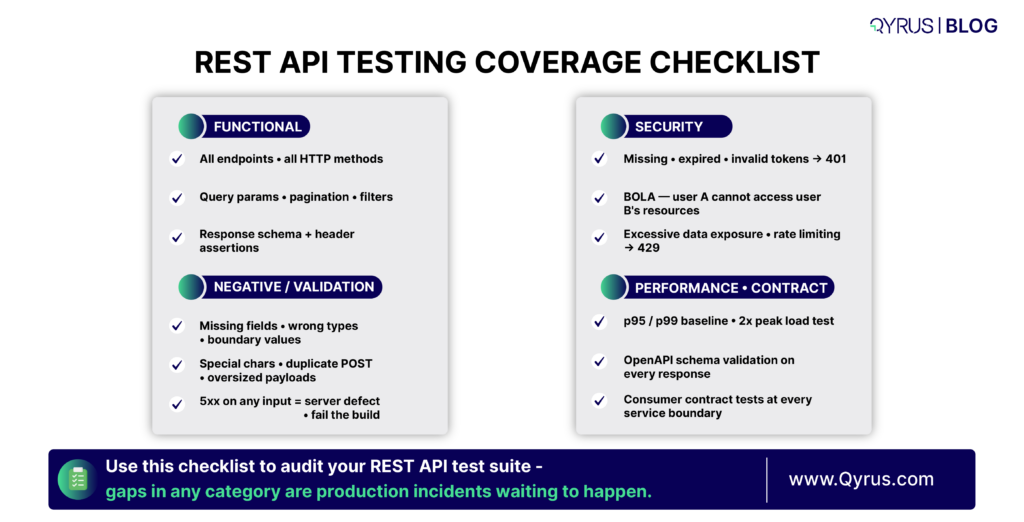
This guide explains everything you need to know about REST API testing. It covers: 

  • What REST API testing actually checks 
  • The important HTTP methods and status codes you should test 
  • The main types of testing (functional, performance, security, and contract) 
  • How to automate your tests effectively 
  • The right tools to use — and what separates professional testing from basic, random testing 

If you’re trying to build your very first API test or improving an existing test suite, you’ll find practical techniques that you can start using right away. 

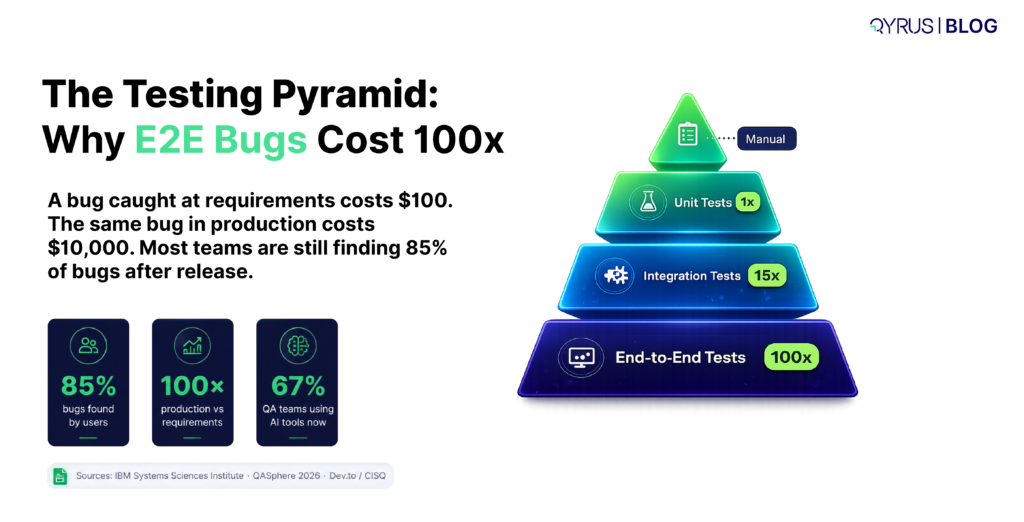
THE COST OF IGNORING

What Does REST API Testing Mean? 

REST (Representational State Transfer) APIs interact with each other over HTTP. They accept structured requests and return structured responses — usually with JSON. Because they sit between the frontend and the backend, it’s the most important integration point in a application. Every mobile app, every web dashboard, and every microservice dependency runs through them. 

REST API testing verifies that this contract behaves exactly as documented. It checks that the API returns the right data, puts the authentication correctly, handles invalid input properly, performs within acceptable latency limits, and exposes no security vulnerabilities. 

The business case is direct. According to Forrester’s research on autonomous testing platforms, while there are more than 50% companies targeting coverage but only 23–25% of them have actually automated test coverage. The gap is not due to tooling issues it’s in testing strategy. 

Teams that run happy-path functional tests while ignoring contract validation, negative-path coverage, and performance baselines. Qyrus helps reduce that gap. 

 Key Stat 

 A single integration failure can cost companies up to $500,000 per year — yet most teams still under-invest in API test coverage beyond basic functional checks. 

Understanding HTTP Methods: The Foundation of Test Cases 

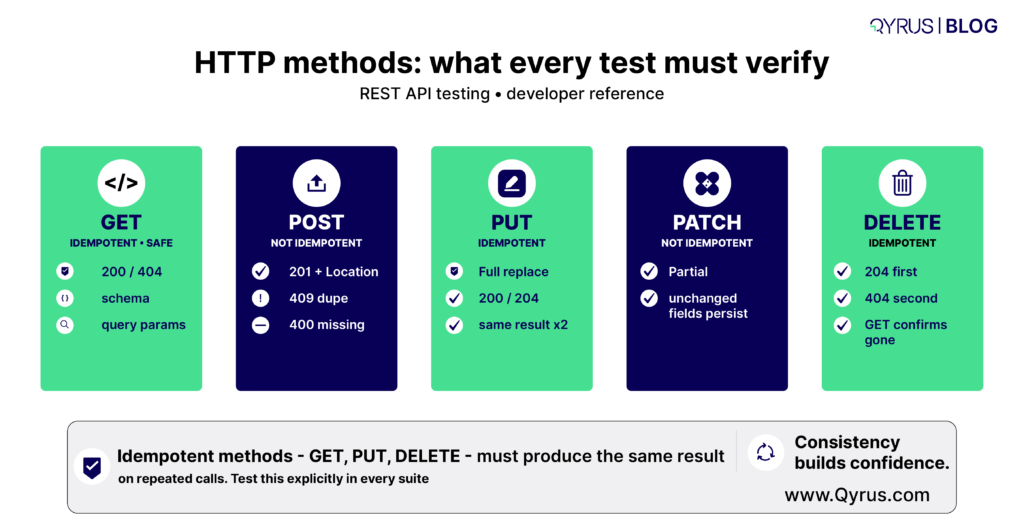
Every REST API test case begins with an HTTP method. Understanding what each method is supposed to do — and what invariants it must uphold — explains what you need to verify. 

HTTP Method 

Operation 

Idempotent? 

Safe? 

Key Test Focus 

GET 

Retrieve a resource 

Yes 

Yes 

Response body shape, status 200/404, query param handling 

POST 

Create a resource 

No 

No 

Request validation, 201 on success, duplicate handling 

PUT 

Replace a resource 

Yes 

No 

Full body replacement, 200/204, missing field behavior 

PATCH 

Partially update a resource 

No 

No 

Partial update accuracy, unchanged field preservation 

DELETE 

Remove a resource 

Yes 

No 

204/200 on success, 404 on missing, idempotency 

rest api testing

Idempotency is a critical testing invariant: If you call GET, PUT, or DELETE multiple times with the same inputs must produce the same result. Your test suite should verify this — particularly for DELETE, as here a second call against an already-deleted resource should return 404, not 500. 

HTTP Status Codes: What Your Tests Must Verify 

Status codes are the only way to understand what happened with the API. Just checking for a 200 OK response is not enough. A good test must also verify if the response body contains the correct data, the expected side effects actually happened and if the error cases are properly handled. 

Relying only on a 200 status means you’re missing the full picture. That’s why you need to know about codes. 

2xx — Success Codes 

  • 200 OK: Standard success for GET, PUT, PATCH. It means the response body matches the expected schema. 
  • 201 Created: Must accompany POST requests that create resources. Verify the Location header points to the new resource. 
  • 204 No Content: Common for DELETE and some PUT operations. The body must be empty — assert that explicitly. 

 4xx — Client Error Codes 

  • 400 Bad Request 
    We get it when the request is badly formed — for example, invalid JSON, missing fields, or wrong data types. Always test these “negative” cases. 
  • 401 Unauthorized 
    Triggered when no login token is sent or the token is invalid. Test this on every protected endpoint. 
  • 403 Forbidden 
    It happens in cases where the user has a valid token but doesn’t have permission for that action. We need to check that role-based access control and see if it works correctly. 
  • 404 Not Found 
    Returned when the requested resource doesn’t exist. Test with both correct-looking and incorrect IDs. 
  • 409 Conflict 
    Happens during duplicate actions or when a business rule is broken (e.g., creating the same record twice). Make sure the error message is clear and helpful. 
  • 422 Unprocessable Entity 
    Gets triggered when the request looks correct but fails specific validation rules. We need to check that each field shows a proper error message. 
  • 429 Too Many Requests 
    We get it when someone exceeds the rate limit. You must verify that the Retry-After header is included so the user knows when to try again. 

 5xx — Server Error Codes 

5xx errors should never be a designed response to valid or invalid client input. If your tests produce 500 responses against documented inputs, that is a defect. Test suites should treat any unexpected 5xx as an automatic failure, regardless of the specific code. 

The Six Dimensions of REST API Testing 

A comprehensive REST API test strategy covers six distinct test types. Most teams focus on functional testing and leave the rest partially or completely uncovered — which is where production incidents originate. And that’s exactly where we should start. 

1. Functional Testing 

In functional testing we verify that the API does what its documentation says. This means testing every endpoint with valid inputs (happy paths) and asserting on the response status, body structure, data types, and field values. It also means testing with boundary values, edge cases, and combinations of optional parameters. 

Key assertions that we must include: 

  • Status code matches the documented response for this scenario 
  • Response body matches the documented schema (field names, types, required vs. optional) 
  • Returned data matches the data that was submitted or the known state of the system 
  • Headers include correct Content-Type and any documented custom headers 
  • Response time is within an acceptable threshold (even in functional tests, set a loose SLA assertion) 

 Functional testing answers the question — “Does the API do what it’s supposed to do?”

2. Negative Testing and Input Validation 

Negative testing verifies that the API fails safely and informatively when given invalid inputs. This is where most functional test suites stop short — and where the most damaging production bugs hide. 

For each endpoint, design tests that send: 

  • Missing required fields 
  • Wrong data types to check strings where integers are expected, and vice versa. 
  • Boundary violations — values one step beyond the documented minimum and maximum 
  • Special characters, Unicode edge cases, and SQL-like injection strings in string fields 
  • Extremely large payloads to probe size limits 
  • Malformed JSON or XML 

In all of of the cases above your API should return a 4xx status code with a structured error message that shows which field failed and why. A 500 response to any of these inputs is a defect. 

Best Practice Here is to  

Use equivalent partitioning to merge inputs into valid and invalid classes, then select representative test cases from each class. Combined with boundary value analysis, this approach will help generate the highest defect-detection output based on per test case written. 

3. Contract Testing 

Contract testing is process that ensures the API’s actual responses matches with the specification it publishes. In most cases typically an OpenAPI (previously known as Swagger) document. This is different from functional testing, which checks behavior. Contract testing checks the shape. 

A developer who changes a field’s type from integer to string, renames a field, or removes a response property may not realize how many consumers that silently breaks. Contract tests catch these breaking changes before they reach production. 

In a microservices architecture, consumer-driven contract testing goes further: each consumer service publishes the specific fields and behaviors it depends on, and those contracts become automated tests run against the provider. Tools like Pact implement this pattern. The OpenAPI specification is your contract artifact — treat it as a first-class test input, not just documentation. 

4. Performance Testing 

Performance testing checks if the API can match its latency and throughput requirements under real and peak loading conditions. A functional test that passes at one user can recreate catastrophic performance regressions that only appear at scale. 

Key metrics that we need to check for: 

  • p50, p95, p99 response latency — not just averages, which mask tail latency 
  • Throughput in requests per second (RPS) at target load 
  • Error rate under load — any increase above the baseline is a regression 
  • Database query time and CPU time breakdown to identify specific bottlenecks 

You should run your performance tests with realistic data volumes. Because an endpoint that returns a response in just 50 milliseconds with 100+ records can suddenly take 8 seconds or more when working with 90,000+ records.  

These kinds of performance issues often only appear when you use production-scale data. That’s why it’s important to create and define performance baselines early so you can enforce them in your CI/CD pipeline. 

5. Security Testing 

REST API Security Testing is done to make sure your authentication and authorization are put across correctly and sensitive data is protected and the API is not vulnerable to usually known attack patterns. The OWASP API Security Top 10 is the good resource to check on what to test. 

What needs to be covered: 

  • Authentication Bypass 
    Test every protected endpoint by trying: no token, an expired token, a malformed token, and a token from a different environment. 
  • Broken Object-Level Authorization (BOLA) 
    Check that a user cannot view or change another user’s data by simply changing IDs in the URL or request body. 
  • Excessive Data Exposure 
    Make sure the API doesn’t return more information than it should — especially sensitive data like personal information (PII), internal IDs, or secrets. 
  • Mass Assignment 
    Try sending extra fields that are not documented in the API (via POST or PUT) and verify the API safely ignores or rejects them. 
  • Rate Limiting 
    Confirm the API limits how many requests you can make and returns a 429 Too Many Requests response with a Retry-After header. 
  • Injection Attacks 
    Send dangerous inputs like SQL code, command injection strings, or SSRF payloads into text fields to ensure the API blocks them. 

6. Integration and End-to-End Testing 

Integration testing is the process to validate a sequence of API calls and to check if it produces the correct system state. This goes beyond testing individual endpoints in isolation — it tests workflows.  

For example: create a user, authenticate as that user, create a resource under that user’s account, verify the resource appears in a list endpoint, then delete it and verify it no longer appears. 

End-to-end tests check the entire flow by connecting multiple services together.They make sure data moves correctly from one service to another. In a microservices setup, this means the output from one API becomes the input for the next API — and the final result matches the expected business outcome. This is why API process testing or API chaining tools are so important. 

Automating REST API Testing: Strategy and CI/CD Integration 

Manual API testing with tools like Postman or cURL is good for exploration and debugging — but it does not scale to production-grade quality assurance. But once your API has more than a handful of endpoints, manual verification becomes inconsistent, time-consuming, and impossible to repeat reliably across every code change. 

So with automated API testing we can solve this by turning your test scenarios into repeatable, machine-executable checks that run without human intervention — on every commit, every pull request easily. 

There are three levels to this: 

Level 1: Local Developer Tests 

Developers run a fast subset of API tests before committing code. This suite should complete in under two minutes and cover the most critical endpoints and happy paths. The goal is immediate feedback during development, not comprehensive coverage. 

Level 2: CI Pipeline Gate 

Every pull request triggers the full test suite. This suite includes all functional tests, negative tests, contract tests, and a lightweight performance assertion (e.g., p95 < 500ms). The pipeline blocks merges on any failure. This is where the bulk of your defect detection happens. 

Level 3: Scheduled and Production Monitoring 

A smaller set of smoke tests runs continuously against staging and production environments to catch regressions that only appear in live infrastructure — configuration drift, third-party dependency failures, or data-volume-related degradations. 

Architecture Note 

Independent nodes in your test workflow should run in parallel. Sequential execution is the default in most frameworks but is rarely necessary — most API tests have no dependency on each other’s execution order. Parallelization can reduce a 30-minute suite to under 10 minutes with no additional infrastructure cost. 

Rest API automation: 3 Level CI/CD

Parameterization and Data-Driven Testing 

A single test script contains logic: it sends a request, receives a response, and checks whether the result matches expectations. What changes between scenarios is the input — the payload, the query parameters, the authentication credentials, the edge case values.  

Data-driven testing separates that variable input from the fixed logic, so one script can help to validate multiple other scenarios without repeating a line of assertion code. 

This is useful when: 

  • We are testing the same endpoint with valid inputs from different user roles 
  • You merge boundary and equivalence class testing with a controlled input matrix 
  • Regression testing against a library of historical production requests that previously caused failures 

Service Virtualization for Dependency Management 

REST APIs frequently depend on other services — third-party APIs, payment gateways, authentication providers, or downstream microservices. When those dependencies are unavailable, unreliable, or expensive to call in test environments, service virtualization (also called API mocking) allows you to simulate their responses with controlled, deterministic behavior. 

Service virtualisation solves this by replacing real dependencies with simulated stand-ins that return controlled, predictable responses. Instead of calling the actual payment gateway, your test calls a mock that always responds with a specific status code, payload, or latency. 

REST API Testing Checklist 

Use our Qyrus designed checklist when designing test coverage for a new or existing API: 

Functional Coverage 

  • All documented endpoints covered with at least one happy-path test 
  • GET, POST, PUT, PATCH, DELETE each tested per endpoint where applicable 
  • Query parameters tested individually and in combination 
  • Pagination tested: first page, last page, beyond last page, invalid page values 
  • Filtering and sorting parameters tested with valid and invalid values 

 Negative and Validation Coverage 

  • All required fields tested for absence 
  • All fields tested for wrong data types 
  • Boundary values tested for numeric and string-length constraints 
  • Special characters and encoding edge cases tested in string fields 
  • Duplicate creation attempts tested for POST endpoints 

 Security Coverage 

  • All protected endpoints tested with missing, expired, and invalid tokens 
  • Object-level authorization tested: can user A access user B’s resources? 
  • Response bodies audited for excessive data exposure 
  • Rate limiting verified on public-facing endpoints 

 Performance Coverage 

  • Baseline latency established for all critical endpoints 
  • Load test run at 2x expected peak traffic 
  • p99 latency asserted in CI pipeline 
  • Large dataset response times tested 

 Contract Coverage 

  • All responses validated against OpenAPI schema 
  • Breaking change detection integrated into CI 
  • Consumer contracts validated against provider for each microservice boundary 
REST API TESTING COVERAGE CHECKLIST

Common REST API Testing Mistakes to Avoid 

Even experienced teams fall into these patterns. Each one creates a blind spot that eventually produces a production incident. 

  • Testing only the happy path 
    This is the biggest mistake. If your tests never try invalid tokens or bad inputs, you don’t actually know if your authentication works. 
  • Asserting only on status codes 
    Just checking for a 200 OK response is not enough. A 200 with wrong data, missing fields, or old information is still a bug. Always check the full response body too. 
  • Ignoring idempotency 
    Not checking that GET, PUT, and DELETE give the same result when you call them multiple times with the same data. 
  • Hardcoding test data 
    Tests that rely on specific data already existing in the system are very fragile. Instead, create and clean up your test data automatically in every test. 
  • Skipping performance baselines 
    Adding a simple check like “response time under 500ms” only takes a few minutes. Without it, you won’t notice when a slow database query gets released to users. 
  • Treating all 5xx errors as acceptable 
    Any 5xx server error on a valid request (or even invalid ones that are documented) should fail your test. It means something is wrong on the server. 
  • Not testing authentication expiry 
    Tokens expire. You must test that your API correctly returns 401 Unauthorized for expired tokens and that the token refresh process works properly. 

How Qyrus Accelerates REST API Testing 

Building and maintaining a comprehensive REST API test strategy at the scale described in this guide is non-trivial. The discipline requires careful test design, robust parameterization, reliable service virtualization, and tight CI/CD integration — all of which accumulate maintenance overhead over time. 

Qyrus is a unified, AI-powered testing platform that addresses the full lifecycle of REST API testing without requiring deep scripting expertise. Its codeless environment supports functional, performance, and security test runs against REST, SOAP, and GraphQL APIs. Nova AI analyzes API responses and automatically generates assertions for headers, JSON body, JSON Path expressions, and schema validation — dramatically accelerating the test creation phase. 

For teams dealing with external dependencies, the Qyrus API Builder can generate mock APIs from a natural language description, providing immediate service virtualization without manual configuration. API Process Testing supports end-to-end workflow validation by chaining multiple REST calls, extracting response data using JSON path expressions, and passing it into subsequent requests — precisely the kind of integration testing that catches real-world defects. 

The platform integrates natively with CI/CD pipelines including Jenkins and Azure DevOps, and connects directly to test management tools like Jira, Xray, and TestRail. Performance runs capture p50, p95, p99 latency, throughput, and active thread counts with built-in graphical reporting. 

If your team is looking to build a REST API testing program that goes beyond happy-path functional checks — one that covers contract validation, security, performance baselines, and automated regression — explore what Qyrus API Testing can do for your team. 

 Summary: Key REST API Testing Concepts 

Concept 

Why It Matters 

HTTP Method Idempotency 

GET, PUT, DELETE must return the same result on repeated calls — a critical invariant to verify. 

Status Code Assertions 

Always assert the exact expected status code per scenario — not just 2xx vs non-2xx. 

Negative Testing 

Invalid inputs must return structured 4xx errors, never 5xx. 

Contract Testing 

OpenAPI schema validation catches silent breaking changes before they reach consumers. 

Performance Baselines 

Establish p95/p99 thresholds early and enforce them in CI. 

Security Test Cases 

Auth bypass, BOLA, and excessive data exposure must be tested on every protected endpoint. 

Service Virtualization 

Mock unavailable dependencies to test error-path behavior deterministically. 

Data-Driven Automation 

Parameterized tests multiply coverage with minimal maintenance overhead. 


Frequently Asked Questions:  

Q: What is the difference between REST API testing and UI testing? 

UI testing validates the application through its graphical interface by checking clicks, forms, and visual elements. REST API testing validates the backend service directly by sending HTTP requests and checking responses, without any browser or UI. API tests are usually 3–10x faster, can run early in development, and help find bugs more precisely. The two approaches complement each other: API tests catch backend logic issues while UI tests verify the end-user experience. Most teams achieve the best results with a 70/30 split — more API tests than UI tests. 

 Q: How do I test REST API authentication and authorization correctly?  

Authentication testing ensures the API accepts valid credentials and rejects invalid ones. For every protected endpoint, you should test at least four cases: a valid token (expects success), no token (expects 401), an expired token (expects 401), and a malformed token (expects 401). Authorization testing checks that a valid token only allows actions permitted by the user’s role. The most important test is Broken Object-Level Authorization (BOLA) — verifying that User A cannot access or modify User B’s data by changing IDs in the request. It should return 403 Forbidden, not 200. 

Q: What is contract testing and when should I add it to my test suite? 

Contract testing verifies that the API’s actual responses match the schema defined in your OpenAPI specification. It checks field names, data types, and required fields. You should add contract testing once you have a published OpenAPI spec and at least one consumer (frontend, mobile app, or another service) depending on the API. In microservices, it is especially valuable early on to catch breaking changes that functional tests might miss. 

Q: What HTTP status codes should my negative test cases target? 

Your negative tests should cover these status codes: 400 Bad Request (malformed payload, missing fields, type mismatch), 401 Unauthorized (missing or invalid token), 403 Forbidden (authenticated but not permitted), 404 Not Found (resource doesn’t exist), 409 Conflict (duplicate or business rule violation), 422 Unprocessable Entity (valid syntax but fails validation), and 429 Too Many Requests (rate limiting). Any 5xx response to a documented request is considered a server-side defect and should fail the test. 

Q: How should I approach REST API performance testing? 

Start by establishing a latency baseline for your critical endpoints under low load. Record p50, p95, and p99 response times. Then run load tests at expected peak traffic and at twice that volume. Focus on key metrics: throughput (requests per second), error rate under load, and tail latency (p95/p99). Add simple performance assertions (e.g., p95 < 500ms) into your CI pipeline. Always test with realistic data volumes, as performance can degrade significantly with larger datasets.

Qyrus Blog Featured Image thumbnail 2026-3

Here is a number that should make every engineering leader uncomfortable: a bug caught during requirements costs $100 to fix. The same bug, discovered in production, costs $10,000. That is a 100x multiplier, and according to IBM’s Systems Sciences Institute, it has held true across decades of software development. 

Yet despite this well-documented reality, 85% of website bugs are still found by users, not QA teams. 

The reason is not a lack of effort. It is a structural mismatch between how fast software is being written and how well teams can test it. AI coding tools like GitHub Copilot and Amazon CodeWhisperer are writing between 20–40% of all new code at major tech companies. Developers ship faster than ever. But testing, anchored to brittle scripts, fragmented toolchains, and manual maintenance cycles, has become the new bottleneck standing between code and confident release. 

This is the velocity gap. And it is widening. 

In 2026, the question is no longer whether to automate end-to-end testing. It is which approach actually works at scale: the open-source code-first frameworks that dominate developer surveys, or the emerging generation of AI-powered platforms that promise to do far more than run scripts. 

This guide cuts through the noise. We compare the leading end-to-end testing tools including Playwright, Cypress, Selenium, and AI-powered alternatives, on the dimensions that matter to real teams: maintenance burden, CI/CD integration, cross-platform coverage, and long-term ROI. Whether you are a QA engineer evaluating your next framework, a developer tired of fixing flaky tests, or an engineering manager building a business case for tooling investment, you will find a clear, honest picture of where the market stands and where it is going. 

qyrus-testing-pyramid

What Is End-to-End Testing (And Why Traditional Approaches Are Failing) 

End-to-end (E2E) testing validates a complete user journey, from the first click through backend processing, database updates, and confirmation screens, as a single, continuous flow. Unlike unit tests, which verify individual functions, or integration tests, which check how modules interact, E2E tests simulate real user behavior across interconnected systems. They answer the question every business actually cares about: does this work, end to end, the way a real user would experience it? 

The testing pyramid places E2E tests at the top for a reason. They offer the most comprehensive validation but also carry the highest cost: slower to run, harder to build, and notoriously difficult to maintain as applications change. 

That maintenance challenge is where most teams quietly lose the plot. According to analysis of 40 startups conducted in Q4 2025, teams spend 60–70% of QA time on test upkeep, with only 30–40% going to new coverage or actual results review. The consequence: enormous engineering investment producing diminishing returns. 


Maintenance burden: 60–70% of QA time is spent on test upkeep, not new coveragehttps://medium.com/qa-flow/the-hidden-test-automation-maintenance-cost-consuming-50-of-qa-time-a8a462cd9084 

Production cost multiplier: A bug caught in requirements costs $100. The same bug in production costs $10,000 which is a 100x difference. https://betterqa.co/bug-fixing-costs-throughout-sdlc/User-detected bugs: 85% of website bugs are found by users, not QA teams.

https://dev.to/esha_suchana_3514f571649c/the-hidden-24-trillion-crisis-why-software-quality-cant-wait-57eiDowntime cost: Average enterprise downtime costs $9,000 per minutehttps://testomat.io/blog/software-bug-cost/


The “shift-left” movement exists precisely because of these economics: catch defects early, when they cost almost nothing to fix, rather than in production, where they cost everything. But shifting left requires test automation that actually runs reliably in CI/CD pipelines, integrates with GitHub Actions and Azure DevOps, and does not collapse every time a developer renames a button. 

Traditional E2E testing tools were not built for this reality. They were built for a world where applications changed slowly, QA engineers had months to build scripts, and the average test suite had hundreds, not thousands, of tests to maintain. That world is gone. 

THE HIDDEN QA TAX

Playwright, Cypress, and Selenium: Strengths, Limitations, and When to Use Each 

Three frameworks dominate the end-to-end testing conversation in 2026. Each earns its place for specific use cases. Each also carries real limitations that enterprise teams routinely discover too late. 

Playwright 

Built by Microsoft and now holding 45.1% adoption among QA professionals, with a 91% satisfaction rating in the State of JS 2025 survey, the widest gap over Cypress ever recorded, Playwright has become the go-to framework for new projects in 2026. 

Its advantages are substantial. Playwright supports Chromium, Firefox, and WebKit natively, meaning true cross-browser coverage including Safari on a single codebase. It is 3.2x faster than Selenium in parallel execution, offers built-in parallelization at zero additional cost, and its auto-wait functionality eliminates most timing-related flaky tests. Multi-language support, including JavaScript, TypeScript, Python, Java, and C#, makes it accessible to polyglot teams. 

Playwright’s limitations matter for enterprise buyers. It requires coding expertise — business analysts and manual testers cannot create or maintain tests without developer support. It covers web only; mobile native apps, desktop applications, and SAP/ERP systems are entirely out of scope. There is no self-healing: every UI change that breaks a locator requires manual triage and repair. And while the framework is free, its value depends entirely on the engineering time needed to build and maintain scripts. 

Best for: JavaScript/TypeScript teams building modern web apps who need cross-browser coverage and strong CI/CD integration. 


Cypress 

Cypress pioneered the developer-friendly testing movement and still holds a loyal following, currently at 14.4% adoption, among frontend JavaScript teams. Its in-browser execution model delivers the most intuitive debugging experience in the category: time-travel debugging that lets you step backward through DOM snapshots is something neither Playwright nor Selenium offers natively. 

The trade-offs are significant. Cypress supports Chromium-based browsers only, no Firefox WebKit, no Safari. It does not support mobile app testing, desktop apps, or any ERP platform. Its architecture limits tests to single-domain scenarios, which creates real friction in enterprise applications that span multiple subdomains or authentication systems. Its cloud parallelization requires a paid subscription: teams running 1,000 tests daily can expect to spend $400–800 per month on Cypress Cloud, compared to near-zero incremental cost on Playwright. 

Best for: Frontend-focused JavaScript teams who value interactive debugging and work exclusively within a single-domain web app. 


Selenium 

Selenium has been the backbone of enterprise browser automation for nearly two decades. Over 31,000 companies report active Selenium usage. It supports every major programming language, every major browser, and virtually every CI/CD tool in the market, and it is entirely free. 

But Selenium’s market share has declined to 22.1% in 2026 for a reason. Its WebDriver architecture introduces HTTP overhead that makes it measurably slower than Playwright. More critically, Selenium has no self-healing whatsoever: every UI change requires manual locator updates across every affected test. For large enterprises with thousands of tests, this maintenance burden consumes entire QA teams. Reporting, test management, and parallel execution all require additional third-party tools assembled from scratch. 

Best for: Large enterprises with established Java, Python, or C# test suites, polyglot teams, and the engineering capacity to manage a high-maintenance framework. 


The three frameworks compared across the dimensions enterprise teams care about most: 


Dimension 

Playwright 

Cypress 

Selenium 

Browser Support 

✅ Chromium, Firefox, WebKit 

⚠️ Chromium only 

✅ All major browsers 

Mobile Testing 

❌ Web emulation only 

❌ Not supported 

❌ Not supported 

API Testing 

⚠️ Basic support 

⚠️ Basic support 

⚠️ Basic support 

SAP / ERP Testing 

❌ None 

❌ None 

❌ None 

Coding Required 

⚠️ Yes (JS/TS/Py/Java/C#) 

⚠️ Yes (JavaScript) 

⚠️ Yes (multi-language) 

Parallel Execution 

✅ Built-in, free 

⚠️ Paid cloud tier 

⚠️ Requires Selenium Grid 

Self-Healing 

❌ None 

❌ None 

❌ None 

CI/CD Integration 

✅ Native (GitHub Actions, Azure DevOps) 

✅ Good (cloud dashboard) 

✅ Via plugins 


The shared blind spot across all three frameworks is not a flaw you can engineer around, it is an architectural reality. None offers unified coverage across Web, Mobile, API, Desktop, and SAP. None provides self-healing automation. None can generate tests from a Jira ticket or a natural language description. For teams whose testing scope ends at the browser, these frameworks deliver real value. For enterprises validating end-to-end business processes that span ERP systems, mobile apps, APIs, and web frontends, they are the wrong foundation. 

E2E Testing

Why Most Teams Are Paying More Than They Think for E2E Testing 

Open-source frameworks appear free. They are not. The license costs nothing; the engineering time to build, run, and maintain them costs everything. 

The average enterprise QA team running a mature Selenium or Playwright suite does not use one tool, it uses five. Selenium or Playwright handles web UI. Postman or a REST Assured library handles API testing. Applitools or Percy handles visual regression. TestRail or Jira manages test cases and results. Each tool has its own license, its own learning curve, its own reporting format, and its own maintenance overhead. Results from these tools exist in different systems, require manual correlation, and cannot produce a unified picture of end-to-end coverage. 

The maintenance bill compounds as test suites grow. Research across enterprise QA teams puts the figure starkly: a 50-person QA organization with a 70% maintenance burden has 35 engineers spending their entire working time keeping existing tests functional, at an average cost of $100,000 per engineer, that is $3.5 million annually spent on maintenance rather than new coverage. 


Annual maintenance cost: A 50-person QA team burns approximately $3.5M per year on test maintenance alonehttps://www.virtuosoqa.com/post/intelligent-test-maintenance 

Self-healing ROI: Forrester data puts the maintenance cost reduction from self-healing tests at 40–45%https://brijeshdeb.medium.com/top-trends-in-testing-in-2026-and-what-does-it-mean-for-testers-and-business-leaders-a1a44bd64761 

Market growth: The automation testing market reached $40.44B in 2026 and is heading to $78.94B by 2031 at 14.32% CAGRhttps://www.mordorintelligence.com/industry-reports/automation-testing-market 

AI adoption: 67% of QA teams now use at least one AI-powered testing tool — up from 21% in 2024https://qasphere.com/blog/ai-in-software-testing/ 


Flaky tests compound the damage further. When test results are unreliable, engineering teams stop trusting CI/CD pipelines. They reintroduce manual validation steps. They delay releases “just to be safe.” The automation that was supposed to accelerate delivery becomes another bottleneck, and the test suite becomes a liability rather than an asset. 

The answer is not a better open-source framework. Playwright is already excellent at what it does. Selenium is already mature. The answer is a fundamentally different architecture, one built for the realities of 2026: heterogeneous application stacks, AI-accelerated development cycles, non-technical team members who understand business processes but cannot write JavaScript, and enterprise deployments that span SAP, Salesforce, mobile apps, and custom web applications in a single end-to-end flow. 


The New Generation of E2E Testing Tools: AI-Powered, Agentic, and Unified 

“AI-powered” has become one of the most overused labels in the testing industry. Almost every tool now claims it. Most mean something narrow: autocomplete for test scripts, or a visual recorder with an AI icon. The distinction that matters is not whether a tool uses AI, it is what the AI actually does and at what stage of the testing lifecycle it operates. 

Genuinely agentic AI testing platforms do something categorically different. They do not wait to be told what to test. They sense changes in the development environment, a new commit to GitHub, a design update in Figma, a modified Jira story, and respond autonomously: analyzing impact, selecting relevant tests, executing them in parallel, self-healing broken locators, and delivering results back into the CI/CD pipeline before a human has reviewed a single line of changed code. 

The market signal is unambiguous. Gartner forecasts that 40% of enterprise applications will include task-specific AI agents by the end of 2026, up from less than 5% in 2025. The World Quality Report 2025–26 found 89% of organizations piloting or deploying generative AI in quality engineering, but only 15% have achieved enterprise-scale deployment. That gap between pilot and production is where the competitive advantage lives. 

Three capabilities separate genuine AI-native platforms from AI-washed frameworks: 

  • Self-healing locators: When UI elements change, the platform automatically identifies and updates the affected locators, no manual triage, no broken pipelines. Forrester data puts the maintenance cost reduction from self-healing at 40–45%. 
  • Autonomous test generation: Tests created from Jira tickets, natural language descriptions, Figma designs, or existing scripts, not from hand-written code. This democratizes testing: business analysts who understand workflows can create coverage without engineering degrees. 
  • Unified coverage: A single platform validating Web, Mobile, API, Desktop, SAP, and Data in one continuous flow, eliminating the fragmented toolchain that fragments results, multiplies maintenance, and obscures the true picture of end-to-end quality. 


The codeless testing segment reflects this shift directly: 39% of companies are now actively evaluating codeless automation tools, according to recent market analysis. The driver is not cost savings alone, it is the recognition that the skills needed to understand business processes and the skills needed to write automation scripts rarely overlap. 

For enterprise teams managing SAP S/4HANA landscapes, Salesforce environments, or cross-platform mobile and web applications, the calculus is clear: a unified AI platform that maintains its own tests costs less over three years than an assembly of open-source frameworks that demand constant human maintenance. The question is which platform delivers that promise at enterprise scale. 

How Qyrus Delivers True End-to-End Testing — Across Every Layer of Your Stack 

Most end-to-end testing platforms validate one layer of the stack. Qyrus validates all of them. 

Qyrus is a unified, AI-powered testing platform that covers Web, Mobile, API, Desktop, SAP, and Data testing in a single interface with no fragmented toolchain, no manual correlation across systems, and no separate license for each testing discipline. It is recognized by Forrester, Gartner, and ISG as a leader in intelligent automation and autonomous testing. 

The SEER Framework: Autonomous Quality at Every Stage 

At the core of Qyrus is the industry-first SEER (Sense, Evaluate, Execute, Report) framework, an autonomous AI orchestration engine that manages the entire testing lifecycle as a continuous feedback loop, not a scheduled event. 

  • Sense: Qyrus continuously monitors GitHub repositories for commits, merges, and pull requests, and observes design changes in Figma in real time. Testing is triggered by actual development activity not a calendar. 
  • Evaluate: Specialized AI agents perform automated impact analysis using static analysis and dependency graphs, mapping code or design changes to the specific API and UI test scenarios most likely to be affected. Only relevant tests run, not the entire regression suite. 
  • Execute: The platform automatically deploys the right agent for the right job: API Bots for backend validation, the Qyrus Test Pilot (QTP) for frontend UI testing, Rover for autonomous exploratory coverage, and Healer for self-healing maintenance. Tests run in parallel across a scalable, ISO 27001 and SOC 2 Type 2 compliant browser and device farm. 
  • Report: Results are delivered in real time back into the DevOps pipeline, detailed coverage metrics, step-level screenshots, video recordings, and AI-driven risk assessments, so teams know not just what failed, but what to fix first. 
Qyrus SEER Framework

Single-Use AI Agents: A Specialist for Every Testing Challenge 

Where most platforms bolt AI onto existing workflows, Qyrus deploys purpose-built Single-Use Agents (SUAs), each an expert in a specific domain: 

  • Healer (US Patent 11,205,041 B2): When UI elements change, Healer automatically analyses the update and repairs affected test scripts. Self-healing, not just self-flagging. This directly attacks the 60–70% maintenance burden that drains enterprise QA budgets. 
  • NOVA: Reads Jira tickets, Azure DevOps stories, or plain-text descriptions and automatically generates comprehensive functional test scenarios. Business teams participate in QA from day one. 
  • TestGenerator+: Analyses existing test scripts and generates new scenarios to fill coverage gaps, categorized by criticality ensuring regression suites stay comprehensive as applications evolve. 
  • Rover: An autonomous exploratory testing engine that navigates applications without human direction, identifying anomalies, crashes, and bugs in areas scripted tests would never reach. 
  • API Builder: Generates fully virtualised, mock APIs from natural language descriptions, enabling backend validation independent of third-party system availability. 


SAP Testing: The Enterprise Differentiator No Competitor Touches 

For organizations running SAP S/4HANA, Fiori, SuccessFactors, or Ariba, Qyrus offers capabilities that Playwright, Cypress, and Selenium cannot begin to match. 

The Fiori Test Specialist reverse-engineers SAP application source code alongside functional specifications and existing manual test cases, generating end-to-end test scripts that understand SAP business processes, not just UI interactions. The proprietary Qyrus SAP Scribe, custom ERP-aware AI models fine-tuned to each customer’s SAP landscape, eliminates the brittle XPath locators that plague traditional SAP automation, replacing them with dynamic object recognition that adapts to metadata changes. 

The platform also supports cross-application orchestration: a single E2E test flow can span Salesforce, SAP, and Ariba across UI, API, and backend layers simultaneously. Prebuilt business process packs cover O2C, P2P, H2R, and PM flows out of the box. 


Test Orchestration: Visual E2E Flow Building for Complex Business Processes 

For teams building complex, multi-platform end-to-end business process tests, the Flow Hub provides a drag-and-drop visual canvas for orchestrating Web, Mobile, and API test scripts into a single continuous workflow. SmartFlow Conditional Mapping adapts to live conditions during execution, rerouting tests dynamically if a user fails a login or a transaction lacks balance, without manual script intervention. 


Seamless CI/CD and Ecosystem Integration 

Qyrus integrates natively with Jenkins, Azure DevOps, Bitrise, TeamCity, and Concourse for CI/CD pipeline execution, and with GitHub and Bitbucket for version control. Test management integrations cover Jira, XRay, and TestRail. Communication integrations include Slack and Microsoft Teams. Tests can be triggered automatically on every commit, scheduled for recurring execution, or run in parallel across the Browser and Device Farm, over 99.9% real device availability, with ISO 27001 and SOC 2 Type 2 compliance. 


The Numbers: What Qyrus Delivers 

  1. ROI: 213% return on investment with a payback period of less than 6 months (Forrester Total Economic Impact study).https://www.qyrus.com/post/forrester-report-tei-2024/ 
  2. Regression automation: 90% automation of manual regression test cases  
  3. Production incidents: 50% reduction in production incidents and downtime through proactive AI defect detection  
  4. Test building time: 70% reduction in test building time through AI-driven and codeless features  
  5. Test case creation: ~80% faster complex test case creation  
  6. Defect leakage: 80% reduction in defect leakage  
  7. Time to market: 36% faster time to market  

These are not framework benchmarks. They are business outcomes with measurable differences in production incident rates, release velocity, and total cost of ownership that translate directly to competitive advantage. A Forrester TEI study commissioned on Qyrus found a 213% ROI with payback in under six months, validated by Shawbrook Bank’s 200% ROI within 12 months of deployment. 

Traditional E2E Testing vs.

How to Choose the Right End-to-End Testing Tool in 2026 

The right E2E testing tool depends on your team’s scope, skills, and scale, not on which framework tops a developer survey. Five questions will clarify the decision faster than any feature comparison: 

  • Do we need web-only coverage, or do our E2E tests need to span Mobile, API, Desktop, or SAP/ERP systems? If the answer is web-only with a coding-fluent team, Playwright is likely your strongest starting point. If your E2E flows cross system boundaries, open-source frameworks will force you to build a fragmented toolchain that multiplies maintenance overhead. 
  • Can our non-technical team members, business analysts, manual testers, domain experts, create and maintain tests? If your QA capacity is gated by automation engineering bandwidth, a codeless or low-code AI platform expands that capacity without proportional headcount growth. 
  • How much of our current QA budget is being consumed by test maintenance? If the answer is more than 40%, the actual cost of your “free” framework already exceeds most enterprise platform licensing fees. Calculate your three-year total cost of ownership before comparing tools on license price alone. 
  • Does our CI/CD pipeline need native integration with GitHub Actions, Azure DevOps, or Jenkins, and do we need parallel execution without paying per-run fees? All major platforms offer CI/CD integration, but the depth, cost, and configuration complexity vary significantly. 
  • Are we prepared to manage, integrate, and train on multiple tools, or do we need a unified platform that covers the full testing lifecycle? Fragmented toolchains work for mature engineering teams with specialized skill sets. Unified platforms are better suited to mixed teams that need one system to own from test creation to defect reporting. 


A simple guide to match team profile to tool choice: 


If your team looks like this… 

Consider this approach 

JavaScript/TypeScript developers, web-only apps, cross-browser needs 

Playwright (free, fast, excellent DX) 

Frontend JS team, Chromium only, heavy debugging needs 

Cypress (best interactive debugging experience) 

Polyglot enterprise team, legacy Java/C# test suites 

Selenium (mature ecosystem, broad language support) 

Enterprise team, Web + Mobile + API + SAP, mixed skills, high maintenance burden, need unified ROI 

Qyrus, AI-powered unified platform with SEER framework, self-healing, and 213% Forrester-validated ROI 


It is also worth acknowledging what this guide is not arguing. Playwright and Cypress are genuinely strong tools for the use cases they were designed for. The engineering teams at companies like Shopify, Vercel, and Stripe who built their E2E suites on Playwright made sound decisions. The argument here is not that open-source frameworks are bad, it is that they are increasingly insufficient as the sole testing infrastructure for enterprises whose applications span systems, teams, and technology stacks that no single framework was ever designed to cover. 

Frequently Asked Questions 

1: What is the difference between end-to-end testing and integration testing?  

Integration testing checks whether two or more modules work correctly when combined, it validates specific connection points between components. End-to-end testing goes further, validating an entire user journey from the first interaction through every system it touches, including the UI, APIs, databases, and backend services, exactly as a real user would experience it. Think of integration testing as checking that two puzzle pieces fit; E2E testing confirms the finished puzzle makes the right picture. 


2: Is Playwright better than Selenium for end-to-end testing in 2026? 

For most new projects, yes. Playwright holds 45.1% adoption among QA professionals in 2026, is 3.2x faster than Selenium in parallel execution, and offers built-in cross-browser support across Chromium, Firefox, and WebKit at zero additional cost. Selenium remains the stronger choice for large enterprises with established Java, Python, or C# test suites and polyglot engineering teams. The honest answer depends on your existing stack, but Playwright wins on speed, modern API design, and CI/CD integration for greenfield projects. 


3: What does “self-healing” mean in end-to-end testing tools? 

 Self-healing refers to a platform’s ability to automatically detect and repair broken test locators when the application’s UI changes, without human intervention. In traditional frameworks like Selenium, Cypress, and Playwright, a renamed button ID or rearranged form element breaks the test and requires a developer to manually update the script. Self-healing tools, powered by AI, identify the changed element, find the correct new locator, and update the test automatically. Forrester data shows self-healing reduces test maintenance costs by 40–45%, directly attacking the biggest hidden cost in enterprise QA. 


4: Can end-to-end testing tools integrate with CI/CD pipelines like GitHub Actions and Azure DevOps? 

 Yes, and seamless CI/CD integration is now a baseline requirement, not a differentiator. Playwright, Cypress, and Selenium all integrate with GitHub Actions, Azure DevOps, Jenkins, and other major CI/CD platforms, triggering test runs automatically on code commits. AI-powered platforms like Qyrus go a step further: they integrate directly into the pipeline and use the commit as a trigger for autonomous impact analysis, parallel test execution, and real-time reporting back to the team, eliminating manual hand-offs entirely. 


5: Which end-to-end testing tool works best for SAP and enterprise ERP applications? 

 None of the major open-source frameworks including Playwright, Cypress, or Selenium, natively support SAP Fiori, S/4HANA, or other ERP platforms. They rely on generic browser automation that breaks frequently against SAP’s dynamically generated control IDs and metadata-driven UI. Purpose-built platforms like Qyrus, with the Fiori Test Specialist and SAP Scribe (custom ERP-aware AI models fine-tuned to each customer’s SAP landscape), are designed specifically for this challenge, eliminating brittle XPath locators, supporting cross-application orchestration across SAP, Salesforce, and Ariba, and generating end-to-end test scripts that understand SAP business processes, not just UI clicks. 


The Future of End-to-End Testing Is Autonomous; Are You Ready? 

The best end-to-end testing tools in 2026 are not just frameworks that run scripts faster. They are intelligent platforms that watch for change, assess impact, execute the right tests autonomously, self-heal when something breaks, and report back to every stakeholder who needs to know, all without a human deciding what to test or manually fixing what breaks. 

The economics of traditional E2E testing have always been difficult. The maintenance burden, 60–70% of QA budget consumed before a single new test is written, has quietly made many automation initiatives liabilities rather than assets. AI-native platforms flip that equation: the cost of testing falls as the platform gets smarter, rather than rising as the test suite grows. 

For teams still evaluating Playwright against Cypress, the comparison is worth making carefully, and both are strong for their intended context. But for enterprises whose definition of end-to-end includes SAP transactions, mobile native apps, REST APIs, and web frontends in a single validated flow, the comparison is not really between frameworks at all. It is between a fragmented assembly of tools that each cover one layer, and a unified platform that covers everything. 

Qyrus delivers 213% ROI (Forrester TEI), 80% reduction in defect leakage, 36% faster time to market, and 90% automation of manual regression cases, not as theoretical benchmarks, but as outcomes validated by enterprise customers across BFSI, manufacturing, retail, and SAP-heavy industries. 

The velocity gap between development speed and QA capacity is not closing on its own. The teams that close it first will ship faster, with fewer production incidents, and at lower total cost than their competitors. That is not a prediction, it is already happening. 


See how Qyrus transforms end-to-end testing for enterprise teams. Request a personalised demo → 

First things first- Your AI coding tools are not the problem.

GitHub Copilot, Amazon CodeWhisperer, and a growing stack of AI development assistants are now generating between 20 and 40 percent of all new code at major technology companies. Your developers are shipping faster than ever before. Feature cycles that once took months now take weeks. Hotfixes that once required sprints go out overnight.

But still your problems keep to rise. Why?

Because your QA team is not able to keep the pace and this gap is widening.

The global automation testing market has already crossed $40.44 billion in 2026 and is projected to hit $78.94 billion by 2031 — companies are clearly pouring money into this problem. But buying tools is not the same as fixing it. Many QA teams have spent heavily and still end up manually stitching together broken pipelines, with three or four tools running web automation, API testing, mobile, and SAP testing in separate silos.

Nearly two-thirds of organizations remain stuck in experimentation or pilot phases, unable to scale AI for real impact

The cost of that fragmentation is not just operational. Every release that goes through patchy test coverage carries defect risk. Every hour your QA engineers spend fixing broken scripts in one tool and rebuilding coverage in another is an hour not spent catching regressions earlier or expanding test breadth.

What this guide gives you is a clear way to make that decision — not a list of tools, but a way to figure out which SaaS test automation platform actually fits your team’s needs, budget, and where you need to be 18 months from now. You will find:

Where Most Platform Decisions Go Wrong

Platform selection failure is not a failure of intent. Most QA directors evaluating automation tools do their homework. They read reviews, sit through vendor demos, and run proof-of-concept tests. The mistakes happen for three specific reasons.

1. Evaluating on Demo Performance, Not Real-World Outcomes

Vendor demos are set up for clean conditions. Every platform looks capable when the test application is simple, the data is tidy, and the integrations are already wired up. The gap between demo and production only shows up after contracts are signed and the first messy E2E flow falls apart.

The smarter approach is to judge platforms on numbers that matter: defect detection rates, test creation speed, regression cycle time, and how much work it takes to keep tests from breaking — all tested against your actual apps and your actual data, not the vendor’s sample project.

2. Ignoring Total Cost of Ownership

License cost is the first number that shows up in a budget conversation. It is rarely the biggest one. For Tricentis Tosca, a mid-size setup with 3–5 users and multiple modules typically runs €40,000–€100,000+ per year in licensing alone — before anyone touches implementation. One Forrester study found a modeled customer spent roughly $150,000 on Tricentis implementation alone. That number rarely shows up in the first proposal.

Across all platforms, the hidden costs follow the same pattern: implementation services, team training, framework setup, and the ongoing hours required to keep test coverage current as the product changes. A platform with cheap per-seat pricing but high upkeep will often cost you more over three years than one that costs more upfront but runs leaner day to day.

3. Underweighting Coverage Breadth

Most platform evaluations zero in on the testing type the team uses most — usually web UI automation. That is fine for the first year. The problem builds up later, when the team needs to extend coverage to SAP, data pipelines, desktop apps, or complex E2E flows, and finds out the platform they locked into does not handle any of that.

The result is the same fragmentation they were trying to get away from — now made worse by migration work, duplicate training costs, and split test repositories.

The 7 Evaluation Criteria’s That Actually Matter

The 7 Evaluation Criteria’s That Actually Matter

Enterprise QA leaders assess platforms based on how well they fit existing quality goals, scale with complex systems, and handle compliance across global operations. The table below lists the seven criteria’s that leaders should anchor every platform evaluation, with suggested weightings based on common enterprise priorities. We suggest you to adjust the weights based on your specific context.

Criteria Weight What to evaluate
Coverage breadth High (25%) Web, mobile, API, desktop, SAP, data — can one platform cover your full stack?
AI maturity High (20%) Self-healing, AI test generation, agentic orchestration — not just smart locators
Maintenance overhead High (20%) % of QA team time consumed by fixing broken tests
CI/CD integration depth Medium (15%) Does the platform block deployments on failure, or just report after?
Team accessibility Medium (10%) Can non-SDETs author and run tests without scripting?
Enterprise compliance Medium (5%) SOC 2, ISO 27001, data masking, RBAC, audit trails
Total cost of ownership High (5%) License + implementation + training + ongoing maintenance — not just per-seat cost

1st Criteria: Coverage Breadth

The single most important question to ask any vendor is: can one platform cover web, mobile, API, desktop, SAP, and data testing? Most platforms say yes to three or four of those. Very few say yes to all six with real depth rather than thin, checkbox support. Before signing anything, ask vendors to show demo of each testing type running on an app that looks like your own tech stack — not a environment purely made for demo.

2nd Criteria: AI Maturity

Not all AI features in testing platforms are the same, we can all agree on that. The market splits into three tiers: AI-native platforms (built from the ground up on AI), AI-augmented platforms (ML features bolted onto older architecture), and AI-labelled platforms (smart locator fallback dressed up as AI). This distinction matters because AI-native platforms tend to cut maintenance by 80–90%. AI-augmented tools land at 30–50%. That gap translates directly into QA team hours and how much coverage they can actually maintain.

AI Platform Tiers and savings

3rd Criteria: Maintenance Overhead

This is the biggest cost driver in any established automation program. Traditional automation frameworks take up 80% of QA budgets just on maintenance. When evaluating any platform, you should ask vendors for documented proof of maintenance reduction — not projected estimates, but real numbers from actual customers. Self-healing accuracy should be something you can verify, not just a claim in a slide deck.

4th Criteria: CI/CD Integration Depth

There is a real difference between a platform that integrates with CI/CD and one that does it well. A basic integration means test results get exported to your pipeline after the fact. A deep integration means the pipeline will be stopped when tests fail, giving your team feedback before code gets merged. For teams running continuous delivery, only that second kind gives you a real quality gate.

5th Criteria: Team Accessibility

If only senior SDETs can write tests, your coverage ceiling is capped by headcount. But in comparison, platforms that support codeless and low-code test authoring let business analysts, manual testers, and junior QA engineers contribute. This difference matters most during regression testing for SAP and ERP flows, where deep knowledge of business processes counts for more than scripting ability.

6th Criteria: Enterprise Compliance and Security

For regulated industries it’s observed that financial services, healthcare, utilities — compliance is not optional. It rules out non-compliant platforms before evaluation even begins. Key requirements include SOC 2 Type II certification, ISO 27001, role-based access control, data masking for sensitive test data, and full audit trails. It is your duty to verify these yourself; do not trust blindly.

7th Criteria: Total Cost of Ownership

Start by creating a three-year cost model before signing. Because a platform with lower upfront costs but heavy ongoing maintenance will often cost more over a full contract term.

Ensure to include: per-seat or per-execution license fees, implementation services, integration development, team onboarding and training, ongoing maintenance hours (calculated at your team’s fully-loaded cost), and the cost of switching platforms if you outgrow the tool. This is the only strategic way you ensure the chances of outcome are on your side.

Platform Comparison

Platform Comparison

Each of the five platforms below is a solid choice for specific use cases. Each also has documented coverage gaps and cost patterns that become significant at enterprise scale. The profiles below draw on public customer reviews, G2 data, analyst reports, and publicly available pricing information — not vendor-supplied content.

Platform Coverage AI Maturity Maint. Overhead CI/CD Compliance TCO
Qyrus Web+Mob+API+SAP+

Data+Desktop

Agentic SEER Very Low Native SOC2+ISO27001 $$
Test sigma Web+Mob+API AI-Native Low Strong SOC2 $-$$
Trecentist Web+Mob+API+SAP AI-Augmented Medium Strong SOC2+ISO $$$$
mabl Web+Mob+API AI-Native Low Strong SOC2 $$$
Katalon Web+Mob+API+Desktop AI-Augmented Medium Good SOC2 $$
ACCELQ Web+Mob+API+Desktop AI-Native Low Strong SOC2 $$$

Please note: TCO tiers above are relative ($ = lower, $$$$ = highest total cost of ownership at enterprise scale). Coverage notation reflects native, production-tested support — not surface-level integrations.

TestSigma

Testsigma is a cloud-native, AI-driven platform with strong credentials in web, mobile, and API test automation. Its Sprint Planner Agent reads Jira boards and automatically generates test coverage for new stories — a feature that can meaningfully speed up coverage for agile teams running short sprints.

The self-healing capability they offer can cut maintenance overhead by up to 90%.

Coverage gap: Testsigma does not offer native SAP or Fiori testing, data pipeline validation, or agentic orchestration for complex E2E business process flows. For enterprises whose testing scope goes beyond standard web and mobile applications, these gaps become hard structural limits rather than minor inconveniences.

Best fit: Cloud-first teams focused on web, mobile, and API coverage with no SAP or legacy enterprise application requirements.

Tricentis

Tricentis is the established enterprise standard for organizations with complex SAP landscapes. Its model-based approach and Vision AI technology are well-regarded for SAP regression testing and large-scale enterprise application coverage. It is also the most expensive platform in this comparison by a wide margin.

According to public sources,  mid-size Tricentis deployments with 3–5 users and multiple modules typically costs €40,000–€100,000+ per year. Named licenses run approximately $3,500–$5,000 per user per year; concurrent licenses run $6,000–$10,000. Implementation services frequently add $150,000+ for large deployments. Every capability — Vision AI, mobile testing, test data management, SAP modules — requires a separate license purchase.

Coverage gap: Real users on G2 consistently flag Tricentis Tosca as not ideal for Salesforce testing. It’s because the learning curve is steep and moreover the script creation process takes significant time. For organizations without dedicated Tricentis-certified engineers, adoption timelines increase out marginally.

Best fit: Large enterprises with SAP as their primary testing challenge, dedicated automation engineering teams, and budget set aside for sustained platform investment.

mabl

mabl is one of the most used platforms for web application testing. It has intelligent test generation, clean CI/CD integration, and easy-to-use interface enabling a fast path to coverage for web-focused teams. Trusted by enterprise names including Workday, Vivid Seats, and JetBlue, it has earned strong customer rating scores for web UI automation.

Coverage gap: mabl does not cover desktop applications as stated by a G2 user. It does not support SAP or data pipeline testing. At scale, teams with test suites larger than several hundred cases report performance slowdowns and unexplained test delays. An important aspect to check before making mabl your enterprise-wide standard.

Best fit: For web-focused teams running moderate test suite volumes, without SAP, desktop, or data testing requirements.

Katalon

Katalon has a larger surface coverage among the five platforms compared here — because it supports web, mobile, API, and desktop testing from a single interface. It  has three authoring modes (record-playback, keyword-driven, and full scripting) make it accessible to mixed-skill teams without forcing everyone into the same workflow. They have a free tier, making it easy to evaluate without a big upfront commitment.

Coverage gap: Katalon’s agentic AI features are less effective as compared to Testsigma or mabl. Advanced scenarios typically require scripting, which brings back the dependency on SDETs for complex flows. SAP testing and data pipeline validation are not supported. For enterprises looking to fully automate complex business process testing without scripting, Katalon starts to show its limits.

Best fit: We see it as a ideal fit for cross functioning teams needing broad surface coverage across web, mobile, API, and desktop, with budget constraints and some scripting capability in-house.

ACCELQ

ACCELQ is built for enterprises with complex business logic validation requirements. Its Generative AI engine builds a live model of the application and uses business rules to suggest relevant test scenarios — a strong capability for organizations with intricate workflow dependencies. Its Salesforce testing depth is among the best in the market.

Coverage gap: Vendor lock-in is a common concern raised by users who need flexibility in their automation framework. SAP Fiori testing depth is limited compared to dedicated SAP testing tools. Data pipeline testing and agentic orchestration across multi-system enterprise flows are not core strengths.

Best fit: Enterprises with Salesforce as the primary application under test, complex business logic validation requirements, and no significant SAP or data testing needs.

Mapping Coverage KPIs to Platform Capabilities

The evaluation framework becomes useful when you tie it to quality outcomes you can actually measure. The five KPIs below are the ones QA directors most often bring to engineering leadership when making the case for automation investment. Each one points directly to a specific platform capability you need to look for.

Mapping Coverage KPIs to Platform Capabilities

KPI Definition Target (12 months) Platform Requirement
Automation Rate % of test cases automated >70% within 12 months Self-healing + codeless authoring
Defect Detection Rate Defects caught pre-production / total defects Improve by 25-30% Agentic coverage + impact analysis
Test Maintenance Effort % of QA time spent fixing tests <20% of QA hours Self-healing AI (Healer)
Test Creation Time Hours to build new test from requirement Reduce by 80% AI test generation (Nova / SEER)
Regression Cycle Time Hours from code commit to green suite Reduce by 50-70% Parallel execution + CI/CD triggers

Two examples show how this mapping helps narrow down vendor choices:

Example 1 — Maintenance overhead is your primary cost driver: Your team currently spends 60% of QA engineering hours maintaining existing test scripts. The KPI target is to bring that below 20% within 12 months. This makes self-healing AI the must-have capability in your evaluation. Platforms without documented, verifiable self-healing accuracy should fall lower on your list, regardless of their other strengths.

Example 2 — SAP regression is your highest business risk: Your organization runs quarterly SAP updates that have historically required 3–4 weeks of manual regression testing. The KPI target is to cut that regression cycle to under one week with 85% automation coverage of critical business processes. This quickly cuts down your vendor shortlist to platforms with native SAP Fiori testing, automated impact analysis of transport changes, and intelligent test prioritization — features that only some of the platforms reviewed here actually deliver at the depth you need in production.

How Qyrus Solves the Coverage Gap

The gap that shows up in every comparison above — SAP, data testing, desktop, and agentic orchestration all covered natively in a single platform — is the problem Qyrus was designed to fix.

Qyrus is an AI-powered, low-code/no-code end-to-end testing platform that covers web, mobile, API, desktop, data, and SAP testing from a single unified environment. The architecture is built around three core differentiators.

Qyrus Solves the Coverage Gap

The Agentic SEER Framework

The heart of the Qyrus platform is the SEER framework — an autonomous AI orchestration engine that runs on a four-stage loop:

This is not AI patched onto an old system. SEER is an agentic engine built for objective-based testing — you set your quality bar, and the system builds and runs the strategy to meet it.

Self-Healing AI (Healer)

Qyrus Healer (US Patent 11,205,041 B2) automatically finds and fixes test scripts when application elements change. When a test fails because of a real UI update, Healer looks at the change, suggests corrected locators, and repairs the script — cutting out the manual debugging that eats up maintenance budgets. For SAP Fiori testing, the Fiori Test Specialist extension pairs Healer with SAP-aware algorithms and Qyrus SAP Scribe (custom ERP-aware AI models fine-tuned to a customer’s SAP landscape) to deliver self-healing at the business process layer, not just the UI locator level.

SAP-Specific Testing Depth

Qyrus provides purpose-built SAP testing capabilities that go beyond what general-purpose platforms offer:

Test Orchestration: Flow Hub

When tests need to span multiple systems — Salesforce to SAP to Ariba, for example — Qyrus Test Orchestration gives teams a visual drag-and-drop Flow Hub. Teams can build branching test flows with conditional logic, parallel execution branches, and error handling strategies (retry with backoff, circuit breakers, saga compensation) without writing orchestration code. SmartFlow Mapping lets tests adjust to what is actually happening in real time — rerouting a flow if a login fails, for instance, rather than failing the entire suite.

Measurable Business Outcomes

 The Phased Implementation Plan: 0–12 Months

Rolling out automation across an enterprise usually takes 12–18 months. AI-native platforms can cut that down by 50–70% compared to traditional frameworks that need a lot of custom development. The most common failure is trying to automate everything in the first sprint and ending up with nothing useful. The phased approach below is set up to show real KPI improvements at each stage, building confidence at each step.

The Phased Implementation Plan: 0–12 Months

Phase Timeline Activities KPI Gate
Phase 1: Foundation Weeks 1–6 Tool selection + CI/CD integration + smoke tests for top 5 user journeys CI/CD pipeline connected; smoke suite passing on every commit
Phase 2: Coverage Build Weeks 7–18 API coverage >70%; regression suite for highest-risk modules; team onboarding complete Automation rate >50%; defect detection rate improving vs. baseline
Phase 3: Scale Weeks 19–52 SAP/data testing live; agentic orchestration for E2E flows; cross-team test reuse Automation rate >70%; regression cycle time reduced by 50%+; maintenance <20% of QA hours

Phase 1 (Weeks 1–6): Foundation

The goal of Phase 1 is a working CI/CD integration and a passing smoke test suite for your five most business-critical user journeys. This phase is about checking that the platform actually works in your setup — your authentication flows, your test data, your pipeline configuration — before you put time into broader coverage.

Activities: Select your platform and sign contracts. Set up CI/CD integration (Jenkins, Azure DevOps, GitHub Actions, or equivalent). Identify your top 5 user journeys by business risk. Build and run smoke tests for those journeys. Verify that failing tests block pipeline deployment.

Common mistake to avoid: Trying to migrate existing test scripts from a legacy platform in Phase 1. Migration brings old problems into the new setup. Start fresh with high-value journeys; migrate in Phase 2 and 3.

Phase 2 (Weeks 7–18): Coverage Build

Phase 2 builds out automation depth across the API layer and your highest-risk regression modules. API tests give you the best return in this phase — they run faster, break less often, and are easier to keep up than UI tests. They also catch integration failures before they show up in the UI.

Activities: Build API test coverage for all public-facing APIs. Find the 10–15 test scenarios with the highest historical defect count and automate those first. Finish team onboarding so all QA engineers can write tests without needing SDET help. Set up test data management workflows.

KPI gate: Automation rate should reach 50% of total test scenarios. Defect detection rate should show a clear improvement versus the pre-automation baseline. Bring these numbers to engineering leadership at the Phase 2 review.

Phase 3 (Weeks 19–52): Scale

Phase 3 extends coverage to the full testing surface — SAP regression, data pipeline validation, desktop application testing, and complex E2E orchestration flows. This phase also sets up the reuse structure that keeps the automation program running on its own: shared function libraries, parameterized test data sets, and cross-team test reuse policies.

Activities: Activate SAP testing modules (Fiori Test Specialist, ARS, DataChain). Build data testing workflows for ETL/ELT pipelines and critical data integrity checks. Set up agentic orchestration for complex multi-system E2E flows. Create shared test function libraries across teams.

KPI gate: Automation rate above 70%. Regression cycle time down by 50% or more versus baseline. Test maintenance overhead below 20% of QA engineering hours. Present a full ROI breakdown to leadership using the KPI model from Section 5.

What to Avoid at Every Phase 

What to Avoid at Every Phase

 The Bottom Line: Choose a Platform That Covers Your Next 18 Months, Not Just Today

The gap between how fast dev teams ship and how fast QA can keep up is real and it is getting wider. The question for QA directors in 2026 is not whether to invest in test automation — that decision was settled years ago. The question is whether the platform you pick can cover everything you need today and everything you will need eighteen months from now.

Testsigma, mabl, Katalon, and ACCELQ all work well for specific situations. Tricentis is the go-to for SAP-heavy enterprises with the budget to match. The coverage gap that each of them leaves — SAP, data testing, desktop, agentic orchestration, or scalable E2E flows — is what ends up forcing a second platform purchase, a migration project, or a structural defect risk.

The seven evaluation criteria in this guide, the KPI model, and the phased rollout plan are here to help you sidestep that problem: make one decision, cover everything, and show measurable ROI at every stage gate.

If your testing scope includes SAP, data pipelines, desktop applications, or complex multi-system E2E flows — and you want a single platform that handles all of them with AI-native automation and no-code authoring — Qyrus is built for exactly that scope.

Ready to close your coverage gap? Book a demo with the Qyrus team and see the SEER framework, Healer AI, and SAP testing capabilities running on applications that look like yours.

Frequently Asked Questions

What is a SaaS test automation platform?

A SaaS test automation platform is a cloud-based software tool that lets QA teams build, run, and manage automated software tests without setting up or maintaining on-premise infrastructure. Modern platforms combine codeless or low-code test authoring, AI-powered self-healing, parallel execution across browsers and devices, and CI/CD pipeline integration — so that teams of varying technical skill levels can build and keep up comprehensive test coverage at speed.

What are the most important evaluation criteria for enterprise QA teams?

For enterprise teams, coverage breadth and total cost of ownership are the two criteria that most teams undervalue. Coverage breadth — whether the platform can genuinely support web, mobile, API, desktop, SAP, and data testing natively — decides whether you end up needing a second or third platform in 18 months. Total cost of ownership, including implementation, training, and maintenance overhead, tells you whether the platform actually pays off over a three-year contract. The seven-criterion framework in this guide gives you a weighted model for structuring your evaluation.

How does Qyrus compare to Tricentis for SAP testing?

Both platforms offer native SAP testing capabilities. The main differences come down to cost, setup complexity, and what each covers outside of SAP. Tricentis is modular and priced that way — each capability (Vision AI, mobile, SAP modules, test data management) needs a separate license, with mid-size deployments typically running €40,000–€100,000+ per year before implementation services. Qyrus provides SAP testing depth — including Fiori Test Specialist, DataChain, ARS, and Robotic Smoke Testing — inside a unified platform that also covers web, mobile, API, desktop, and data testing. For organizations where SAP is one important testing area among several, Qyrus offers broader coverage at a lower total cost.

What KPIs should I track to measure test automation ROI?

The five KPIs that best show automation ROI to engineering and business leadership are: automation rate (percentage of test scenarios automated, target 70%+ within 12 months), defect detection rate (percentage of defects caught pre-production, target 25–30% improvement), test maintenance effort (percentage of QA hours spent fixing broken tests, target under 20%), test creation time (hours from requirement to executable test, target 80% reduction), and regression cycle time (hours from code commit to green test suite, target 50–70% reduction). Setting a baseline before you deploy the platform is essential — without it, you have no way to prove the ROI later.

How long does it take to implement a SaaS test automation platform enterprise-wide?

Enterprise-wide automation rollouts typically take 12–18 months, covering platform selection, CI/CD integration, team onboarding, coverage build, and scaled deployment. AI-native platforms can cut that timeline by 50–70% compared to traditional frameworks that need significant custom development work. Pilot rollouts — covering a defined application scope and team — usually wrap up in 3–6 months and give you the proof you need to roll it out across the organization. The phased plan in this guide covers the first 52 weeks in detail.

What should I look for in AI-powered testing tools?

Three things separate platforms that are actually AI-powered from those that just use the label. First, self-healing test maintenance — where the platform automatically spots and fixes broken test locators when applications change, with accuracy rates you can verify, not just take on trust. Second, AI-driven test generation — where the platform creates test scenarios from requirements, Jira tickets, or application analysis rather than making engineers write every test by hand. Third, agentic orchestration — where the platform picks and runs the right tests in response to a code change, rather than firing the entire regression suite regardless of what changed. Platforms that deliver all three at production quality work very differently — in terms of cost and output — from those that only cover one.

What is the biggest mistake QA teams make when selecting a test automation platform?

Judging a platform by its demo rather than what it can do in the real world. Vendor demos are built for clean conditions and rarely show the coverage gaps that become real problems once you are locked in. The most reliable way to evaluate is a hands-on proof-of-concept using your actual applications, your actual test data, and your actual CI/CD pipeline — scored against the seven criteria in this guide rather than a gut feeling from a vendor-run demo. Asking vendors to show each testing type (web, mobile, API, SAP, data) on a sample of your own application stack is the fastest way to find the gaps that will actually matter for your team.

SAP Testing Tools-Featured Image

Here’s a situation that plays out in enterprises every day: an SAP update goes through. The business team signs off. The technical checklist looks clean. Then, three days after go-live, a purchase order hits an error that nobody caught. Finance scrambles. Supply chain stalls. And IT is left explaining how something this critical slipped through. 

The problem is usually a gap in SAP testing. This gap is often because we do not have automated tests or we are using a testing tool that is not good enough. 

As SAP software is at the heart of how companies work today, it is very important to choose the testing framework. This guide will tell us what we need to look for when we are evaluating an SAP testing platform, the problems that these tools need to solve, and how new tools like Qyrus that use artificial intelligence are changing the way we do quality engineering for SAP systems in companies. Qyrus and other modern tools are making a difference, in how we test SAP software. 

Qyrus SAP testing tools dashboard vs manual testing comparison

The Unique Complexities of Enterprise SAP Testing 

 Let us be honest: most organizations greatly underestimate how complex SAP testing is. It is not about clicking through screens and checking if a transaction posts. SAP environments are deeply connected to each other. A single change in one part of the system can affect other areas like finance, procurement, supply chain, and human resources before anyone realizes what is happening.  To understand why basic automated testing tools fail, consider the broader economic stakes. According to industry research, over 440,000 companies worldwide utilize SAP solutions, allowing 77% of global transaction revenue to flow through an SAP system at some point. When deployments fail, the results are severe: SAP downtime costs enterprises an average of $9,000 per minute.  Because many companies are moving to S/4HANA and making their systems more complex the market for SAP testing was worth over $700 million in 2025 and is still growing at a rate of8.1% CAGR. 

When SAP deployments fail the results are severe: SAP downtime costs companies an average of $9,000 per minute. Because many companies are moving to S/4HANA and making their systems more complex the market for SAP testing was worth over $700 million in 2025 and is still growing at a rate of 8.1% per year. 

Enterprise QA teams face several distinct structural barriers within these landscapes: 

  • Deep customization: Every SAP implementation is unique. Custom ABAP code, bespoke workflows, and organization-specific configurations mean that generic test cases often miss what matters most. Custom ABAP Extensions and Custom Core Code: Because legacy SAP ECC landscapes often carry decades of custom modifications, transitioning to a clean-core architecture on S/4HANA requires deep analysis of custom Z-tables and custom transaction codes (T-Codes) to ensure extensions do not break core business logic. 
  • Cross-module dependencies: Touch one thing in FI/CO and it might surface as a bug in MM (Materials Management) or SD (Sales and Distribution). Testing in isolation will not catch these connections. 
  • IDoc/EDI hidden failures: SAP might report successful processing status while an IDoc has quietly posted the wrong data. This “Green Light Lie” is one of the most insidious risks in SAP testing. 
  • Dynamic UI locators: SAP Fiori and UI5 apps create dynamic control IDs when they are running. Older test automation frameworks rely on static XPath locators, which break when you run scripts against dynamic interfaces.  

Add to that the reality that many QA teams spend 30–50% of their time just on environment setup and data management before a single test case runs, and it becomes clear why simply “having an automation tool” is not enough. 

What Actually Separates Great SAP Testing Tools from Average Ones 

There is no shortage of SAP testing tools on the market. The harder question is: what separates tools that can really solve enterprise problems from a tool that looks good in demos but fails in real-life situations?  

Here are the criteria that matter most: 

1. Native SAP Protocol and UI Awareness  

The tool must understand SAP-specific UI controls, OData services, BAPIs, and IDocs rather than treating SAP like any other web application. A UI5-aware recorder, for example, recognizes SAP Fiori controls natively, which eliminates the brittle XPath locators that cause most automation scripts to fail after the first update. 

It is also important for the tool to understand the business context. There is a difference between a tool that clicks “Create” on a purchase order screen and one that understands what “Create Purchase Order” means in the context of a Procure-to-Pay (P2P) process. 

  1. True End-to-End Business Process Coverage

Transaction-level testing is table stakes. What enterprises actually need is coverage that spans the full  Order-to-Cash (O2C), P2P, or Hire-to-Retire (H2R) workflows across SAP modules and into connected non-SAP applications like Salesforce, Ariba, or custom APIs. 

The best SAP automation tools support cross-application orchestration, passing data seamlessly between systems in a single test flow. If your tool tests SAP in isolation, you’re only seeing part of the picture. 

3. Algorithmic Self-Healing Test Scripts  

Script maintenance is where most automation programs go off the rails. As SAP interfaces change and they change constantly in cloud and Fiori environments, brittle scripts break and engineers spend days fixing them instead of building new coverage. True self-healing means the tool can detect a changed UI element, identify the correct new locator, and update the test script automatically, without human intervention. Not every vendor that markets this capability actually delivers it reliably. 

4. Intelligent Test Data Management 

Test data in SAP is not simple. A single end-to-end test might require a sales order that links to a delivery, an invoice, a financial posting, and an inventory record, all referentially consistent. Creating this manually is a “referential integrity nightmare,” as one analyst put it, and a primary source of testing delays. 

Tools that can automatically trace document flows, extract linked data, and construct complete, production-like test datasets eliminate one of the biggest bottlenecks in SAP QA. 

5. AI-Driven Impact Analysis and Smart Test Selection 

Not every test needs to run with every change. Intelligent platforms analyze SAP transport requests and change logs, identify affected areas, and prioritize testing effort on what’s actually at risk. This is the difference between running a full regression suite that takes three weeks and running a targeted suite that takes hours, with higher confidence. 

6. Backend and API Validation  

UI-based SAP testing misses the engine. Backend validation through OData APIs, BAPIs, and direct database queries provides faster, more stable, and more comprehensive coverage, especially for custom ABAP logic and complex integration points that never surface in the UI at all. 

A Practical Look at the SAP Testing Approaches in Use Today 

Not all SAP testing strategies are created equal. Here’s how the main approaches stack up in practice: 

Approach 

Speed 

Coverage 

Maintenance Cost 

Manual testing 

Very slow 

Incomplete at scale 

High (human effort) 

Script-based automation 

Moderate 

Good if maintained 

Very high (brittle scripts) 

Native SAP tools (CBTA/SolMan) 

Moderate 

SAP-only, limited E2E 

Medium 

AI-powered platforms (e.g. Qyrus) 

Fast 

End-to-end, cross-system 

Low (self-healing) 

Manual testing hit a wall years ago. The challenge now for most enterprises is transitioning away from script-based automation, which worked reasonably well when SAP interfaces were stable, toward something that can keep pace with continuous change. 

That’s where AI-native platforms are making the biggest impact. Over 55% of enterprises have now adopted automated testing tools for SAP platforms — but adoption doesn’t guarantee effectiveness. The quality of the tool matters as much as having one at all. 

How Qyrus Solves the SAP Testing Problem Differently 

Qyrus is purpose-built for the complexity of enterprise SAP environments. Where most testing tools treat SAP as another web application with screens to click through, Qyrus is natively aware of underlying business processes, data structures, and the specific challenges of SAP S/4HANA testing. 

The 3Cs Framework: Testing What Actually Matters 

Qyrus’s approach to SAP testing starts with a strategic filter: focus on what is Critical, Complex, and has Changed. This “3Cs” methodology prevents the all-too-common mistake of running the same broad regression suite regardless of what changed, burning testing resources on low-risk areas while high-risk areas stay under covered. 

Qyrus 3Cs framework Critical Complex Changed SAP testing strategy

Autonomous Regression Testing (ARS): Let AI Do the Heavy Lifting 

 Qyrus’s Autonomous Regression Testing combines proprietary algorithms with SAP Scribe, a set of ERP-aware AI models trained specifically on each customer’s SAP environment. Instead of relying on manual test planning every time a transport moves through the system, it automatically analyzes change logs, traces dependencies, identifies impacted business flows, and determines exactly which regression tests need to run. It also flags coverage gaps and creates additional test scenarios where risk areas are not fully covered. Rather than working from static spreadsheets and assumptions, testing teams receive a prioritized, risk-based regression plan tailored to the actual SAP changes introduced. 

The business impact: 65% faster regression preparation and 50% fewer resources needed to maintain the test suite, with broader coverage, not narrower. 

DataChain: Solving the Test Data Nightmare at the Source 

Test data management in SAP is where many automation efforts quietly fail. Qyrus addresses this with DataChain, an automated TDM capability that takes a single input, such as a sales order number. DataChain automatically traverses the SAP document flow to identify and compile all downstream and upstream linked transactions, including quotations, logistics deliveries, billing invoices, and financial accounting ledger entries.  

The result is a fully structured, referentially consistent dataset ready for testing, with a reported 92% reduction in test data creation time. What previously took days of manual coordination now takes minutes. 

Qyrus DataChain SAP document flow test data automation diagram

Fiori Test Specialist: Built for SAP’s Modern UI 

One of the biggest pain points in SAP S/4HANA testing is the SAP Fiori and UI5 interface. Dynamic control IDs break traditional automation. Business users don’t speak the technical language of XPath. And testing teams spend enormous effort just getting tests to work reliably. 

Qyrus’s Fiori Test Specialist uses proprietary algorithms and the SAP Scribe AI model to reverse-engineer the application’s source code, analyzing views, controllers, manifest files, and annotation files, and automatically generate end-to-end test cases that a traditional recorder would produce, but without the manual recording effort. 

Another key capability is gap analysis. The system checks whether the actual SAP behavior matches the documented process and whether the existing test cases truly validate those flows. 

In many SAP environments, these three areas gradually drift apart over time. Documentation gets outdated, business logic changes, and test cases continue running without covering the latest scenarios. Qyrus helps expose those gaps early by highlighting missing validations, uncovered flows, and inconsistencies before they turn into production issues during deployment or go-live. 

Self-Healing That Actually Works 

Qyrus’s Healer AI (covered by U.S. Patent 11,205,041 B2) is not a marketing feature, it’s a core part of the platform’s ability to stay reliable as SAP environments change. When a test fails because a UI element has moved or been renamed, Healer automatically scans the application, identifies the correct technical field, and repairs the test script. 

In the Fiori Test Specialist workflow, Healer runs interactively during test execution: if an AI-suggested field is incorrect, execution pauses, the application is scanned, and updated values are applied before testing continues. Scripts that would normally require hours of manual debugging are “healed” in minutes. 

API-First Backend Testing: Faster, More Stable, More Comprehensive 

Qyrus’ API-first architecture integrates directly with SAP’s native backend services including OData, BAPIs, IDocs, and direct database queries. This enables validation that bypasses the UI entirely, which is faster, more stable, and catches issues that UI-only testing will never surface. 

For IDoc/EDI testing specifically, Qyrus’ Relationship Spotter feature automatically links incoming IDocs to the business transactions they posted, then compares expected values against actual outcomes, catching the “Green Light Lie” that standard SAP tools are built to miss. 

The platform supports testing of 50–100+ O2C process variants where traditional approaches typically cover 10–20 at most, a material improvement in coverage for organizations with complex or highly customized SAP implementations. 

Robotic Smoke Testing: Confidence After Every Update 

Post-maintenance and post-upgrade system health checks are a constant drain for SAP teams. The ASUG/Worksoft study found that 75% of SAP customers have special “hyper-care” periods after updates, a clear signal that confidence in system stability after change is low. 

Qyrus’ Robotic Smoke Testing (RST) automates these system health checks. A single user can configure and run standard SAP transactions to validate system availability, OS performance, background job status, and external system communications, transforming a multi-team weekend exercise into a reliable, automated process. 

Quantifiable Results: What Enterprises Actually See 

Numbers tell a cleaner story than feature lists. Here’s what enterprises working with modern AI-powered SAP testing platforms report: 

  • 88% effort reduction on critical process testing (documented in a Capital Goods Purchase process case study) 
  • 79% reduction in manual and low-tier work, per the ASUG/Worksoft study of SAP customers using automation 
  • 92% faster test data creation with automated data chain tracing 
  • 65% faster regression preparation with AI-driven impact analysis 
  • 200% ROI within 12 months, as demonstrated in enterprise success stories 
  • 2x higher test breadth with 50% fewer resources, enabled by autonomous regression testing 

These aren’t projections — they’re outcomes from organizations that moved beyond “automating the old way” and adopted platforms that understand SAP testing at a business-process level. 

Qyrus SAP testing automation ROI statistics 88% effort reduction

How Qyrus Compares to Other SAP Testing Tools 

Several SAP testing tools have established strong positions in the enterprise market, but they differ significantly in how they approach automation, maintenance, scalability, and SAP ecosystem support. Some platforms are built around deep SAP GUI automation, while others focus more on end-to-end business process testing across both SAP and non-SAP systems. AI capabilities, implementation complexity, and long-term maintenance effort also vary considerably between vendors. 

Because of this, the “best” option often depends on what an organization is trying to solve. Some enterprises prioritize large-scale regression coverage during SAP transformations, while others focus on reducing maintenance overhead, accelerating release cycles, or enabling business teams to participate more directly in testing. 

Here is a closer look at how the leading SAP testing platforms differ across areas such as SAP support, AI-driven automation, scalability, usability, and overall testing approach, based on publicly available product information, analyst reports, customer reviews, and community feedback. 

Tricentis Tosca 

Tricentis Tosca is one of the most recognized names in enterprise test automation. Its model-based, codeless approach is genuinely powerful, andusers report faster test creation and high reusability of test modules. Tosca supports SAP (including S/4HANA and Fiori), Oracle, Salesforce, and 160+ other technologies, making it a strong choice for organizations managing complex, multi-system landscapes. 

The challenges usually start once teams move beyond the initial evaluation phase. Tosca is widely seen as a premium enterprise platform, and the licensing costs can become significant as adoption expands across larger teams. Many organizations also underestimate the amount of training required early on. While the platform is powerful, new users often need time before they become comfortable building and maintaining automation at scale. 

There are also some practical infrastructure considerations. Tosca still works best in Windows-centric environments, which may not fit neatly into organizations standardizing around cloud-native pipelines or mixed operating system ecosystems. Some of the newer AI-driven capabilities, including Agentic Test Automation and MCP Server integration, are currently more aligned with the cloud offering as well, so on-premise customers may not get access to the latest functionality at the same pace. 


Best for: Large enterprises with dedicated automation teams, existing Tricentis investment, and the budget to scale a model-based testing program across multiple enterprise applications. 

Where Qyrus goes further: Qyrus adds native SAP Scribe AI fine-tuned to each customer’s landscape, autonomous regression test selection from transport logs, built-in test data chain tracing, and IDoc/EDI backend validation — capabilities that go beyond Tosca’s model-based UI automation. 

Worksoft Certify 

Worksoft Certify has a long and respected track record in SAP business process testing. Its codeless capture mechanism works seamlessly with SAP GUI, and its reusable test assets make it genuinely efficient for organizations running large, repetitive regression cycles against stable SAP ECC environments. 

The challenge is where SAP is heading. Reviewers consistently note that web-based testing — especially SAP Fiori — requires significantly more effort in Worksoft than SAP GUI automation. As one user put it directly: “From the SAP side, there is nothing better than Worksoft Certify. However, from the web-based, we are moving towards Fiori… Worksoft has to improve the web-based testing part.” Reports are also cited as not business-user friendly, and the upgrade process is described as lengthy and tedious. 

Best for: Organizations running heavily customized SAP ECC with established, stable business processes where GUI-based automation is the primary requirement. 

Where Qyrus goes further: Qyrus’ Fiori Test Specialist is built specifically for SAP UI5 environments — it reverse-engineers application source code to generate tests without requiring manual recording. Teams migrating from ECC to S/4HANA get immediate Fiori coverage without rebuilding their test library from scratch. 

SAP Solution Manager / CBTA 

SAP’s own native testing tools — Solution Manager and Component-Based Test Automation (CBTA) — are attractive on paper because they come bundled with the SAP ecosystem. The integration with SAP CloudALM and direct access to change request management make them a logical starting point for teams already deep in the SAP stack. 

In practice, however, SAP’s own tools are widely described as complex, difficult to use, and not built for end-to-end testing across integrated non-SAP systems. CBTA configurations are subject to SAP transport management rules, creating administrative overhead. Solution Manager itself reaches end-of-mainstream-maintenance in 2027, adding strategic risk for organizations that have built their testing practices around it. The steeper learning curve and limited cloud capability further reduce its appeal as a primary testing platform. 

Best for: Teams with limited budgets that need basic coverage of core SAP transactions and already have Solution Manager deeply embedded in their ALM processes. 

Where Qyrus goes further: Qyrus covers the full testing lifecycle — including non-SAP systems, API validation, IDoc testing, and mobile — and its AI-driven autonomous regression doesn’t require manual test case management the way CBTA does. It also has no 2027 end-of-life exposure. 

Leapwork 

Leapwork is designed with usability in mind, and that is one of the reasons many teams adopt it. Its visual, no-code interface allows non-technical testers to build automation flows quickly, and its support for SAP GUI, Citrix, and legacy desktop environments has made it a practical choice for organizations dealing with mixed technology stacks.The limitations usually become more noticeable in larger enterprise environments. Some users point to weaker mobile automation capabilities and less detailed reporting compared to more specialized enterprise testing platforms. Pricing is another concern that comes up often. Reported costs of around $100,000 for ten licenses can make the platform difficult to justify for many mid-market teams trying to scale automation across departments. 

Leapwork is also built as a general-purpose automation platform, not a SAP-specific testing solution. While it handles SAP interface automation well, it is not designed around SAP-native areas such as IDoc validation, ERP data dependencies, transport analysis, or deeper end-to-end SAP business-process testing. 

Best for: Teams that need to automate across SAP, Citrix, and legacy desktop systems without deep coding skills and where out-of-the-box simplicity takes priority over SAP-specific depth. 

Where Qyrus goes further: Qyrus is built with SAP-specific intelligence at its core — ERP-aware AI models, transport-level impact analysis, automated document flow tracing, and IDoc validation. These are not features Leapwork was designed for. 

OpenText UFT One (formerly Micro Focus UFT) 

OpenText UFT One is one of the most established functional testing platforms on the market, with over 200 supported technologies including SAP, Oracle, Salesforce, and Citrix. Its longevity means deep integration support and a large community of practitioners with existing knowledge of the platform. 

The platform’s dependency on VBScript — a scripting language widely considered obsolete by modern standards — is a recurring frustration for teams that want to work in Python or JavaScript. Users also report high memory consumption, which creates performance issues in virtualised environments, and several reviewers note that UFT One is better aligned with SAP ECC (GUI-based) than with the Fiori-heavy S/4HANA landscape. As Leapwork’s own competitor comparison noted, UFT One maintenance requires VB and JavaScript skills — a meaningful technical bar for many QA teams. 

Best for: Organizations with long-standing UFT deployments, large SAP ECC estates, existing VBScript expertise, and stable application landscapes where broad technology coverage matters more than AI-driven agility. 

Where Qyrus goes further: Qyrus is designed for the S/4HANA era, with Fiori-native testing, AI-driven script healing, autonomous regression, and no dependency on legacy scripting languages. For teams modernizing their SAP landscapes, Qyrus is the forward-looking choice. 

At a Glance: SAP Testing Tools Compared  

Tool 

SAP Fiori-Native 

AI Impact Analysis 

Self-Healing 

Cross-System E2E 

Best Fit 

Tricentis Tosca 

Yes (model-based) 

Limited 

Vision AI (cloud) 

Strong 

Large enterprise, multi-tool 

Worksoft Certify 

Improving 

Yes (Worksoft Impact) 

Limited 

Strong 

SAP ECC-heavy orgs 

SAP SolMan / CBTA 

Partial 

Basic 

No 

SAP only 

Budget-constrained, simple needs 

Leapwork 

Partial 

No 

Limited 

Moderate 

Mixed legacy + SAP, non-technical teams 

OpenText UFT One 

Partial (ECC-focused) 

No 

AI object detection 

Broad 

Long-standing UFT shops, ECC estates 

Qyrus 

Yes (source-code aware) 

Yes (SAP Scribe AI) 

Yes (patented) 

Yes (SAP + non-SAP) 

S/4HANA migrations, AI-first QA 


A few important caveats on the table above: every product in this comparison is actively evolving, and vendor capabilities can change with each release. Where your organization currently sits on the ECC-to-S/4HANA migration journey, the technical depth of your QA team, and your existing toolchain investments will all influence which platform delivers the best fit. The table is a starting point for your evaluation — not a substitute for a hands-on proof of concept. 

Common Pitfalls When Evaluating SAP Testing Tools 

Before wrapping up, it’s worth calling out a few evaluation mistakes that organizations make repeatedly: 

  • Choosing based on SAP GUI coverage alone. If your organization is on or moving to S/4HANA, you need Fiori support as a first-class capability — not an afterthought add-on. 
  • Treating test data as “someone else’s problem.” The tool evaluation should include a hard look at how test data will be created, managed, and kept consistent across test cycles. 
  • Ignoring maintenance costs. A tool that is cheap to set up but expensive to maintain — because scripts break constantly — is not cost-effective. Ask vendors how their platform handles UI changes and what the actual maintenance burden looks like six months after go-live. 
  • Siloing SAP testing from the broader QA strategy. SAP doesn’t operate in isolation. Any tool that can’t test cross-system workflows — from Salesforce through SAP into Ariba — is limiting your coverage by design. 
  • Underweighting backend validation. Many teams discover too late that their UI-centric test suite passes while underlying data is corrupted. API and backend testing is not optional for SAP environments — it’s essential. 

The Right SAP Testing Tool Makes the Difference Between Go-Live Confidence and Go-Live Fear 

SAP testing has never been more critical — and the window for relying on manual effort or brittle script-based automation is closing fast. With S/4HANA migrations in full swing, Fiori interfaces evolving continuously, and business processes becoming more interconnected by the day, teams need tools that are as sophisticated as the environments they’re testing. 

Qyrus is purpose-built for exactly this moment. Recognized as a Leader in The Forrester Wave: Autonomous Testing Platforms, Q4 2025, Qyrus combines deep SAP awareness, AI-driven automation, self-healing test scripts, intelligent test data management, and cross-system orchestration in a single platform, without requiring a team of automation specialists to keep it running. 

Whether you’re managing a large S/4HANA migration, dealing with relentless Fiori updates, or simply trying to get more out of your existing automation investment, Qyrus delivers the coverage, speed, and confidence your team needs. 

See Qyrus SAP testing in action — book a personalized demo today and find out how much time and effort your team can recover. 

May Release Notes

  Welcome to the May update!  

We’ve focused heavily on deepening platform integration, introducing smarter AI-driven logic, and giving enterprise teams much greater execution flexibility. 

Across our services, we are breaking down silos and accelerating your daily testing rhythms. In Web Testing, we’ve unlocked real-time locator access for seamless SAP scripting and rolled out major intelligence and speed upgrades to Test Generator v2. Desktop Testing sees an influx of pipeline capability with brand-new Jenkins and Azure DevOps plugins, alongside powerful new session persistence that lets you connect directly to existing SAP windows. 

Meanwhile, our underlying infrastructure continues to mature. Test Orchestration has been completely decoupled from individual module licensing to act as a truly independent layer, while also gaining folder-level scheduling to streamline batch execution. We’ve also fortified our mobile capabilities with massive stability upgrades to iOS device streaming, and extended qAPI’s enterprise reach with robust Node CLI enhancements and clearer project management tracking. 

Let’s dive right into the full details of all the powerful new capabilities available on the Qyrus platform. 

Web Testing

Flawless Connections: Enhanced iOS Device Streaming! 

The Challenge:  

When using Test Generator v2 to automatically build test scenarios via integrations, any friction in the generation flow ruins the speed advantage of using AI. Previously, users faced two major hurdles: the initial streaming API could experience a bottleneck—taking up to two minutes just to return a “Generating” status—and auto-generated variable actions lacked structural logic. If a script required multiple variables (e.g., Var 1 through Var 5), the AI didn’t automatically cross-reference its memory to intelligently link those variables to subsequent data handler steps, forcing testers to manually patch the logic. Additionally, path values for generated steps were buried, making it tedious to audit the AI’s structural paths. 

The Fix:  

We have rolled out critical enhancements to Test Generator v2 to optimize both backend performance and AI logic. We dramatically accelerated the initial stream API response time, slashing the latency required to initiate a generation job. On the intelligence front, the AI now automatically names variables inside the “Create Variable” action and intelligently maps those identical variable names to corresponding downstream data handler actions (such as Dynamic Set steps) by referencing its historical memory. Finally, we have explicitly included the exact path values right inside the info section of every step TG generates. 

How will it help?  

These intelligence and speed optimizations turn AI generation into a fluid, hands-off experience. 

  • Instant Generation: No more waiting on spinning wheels. The optimized streaming API kicks off your AI generation jobs almost instantly, accelerating your overall testing velocity. 
  • Flawless End-to-End Variable Logic: The AI now handles multi-variable data mapping seamlessly. If your test scenario creates five variables, the system automatically tracks them in its memory and binds the correct variable to subsequent dynamic steps without manual intervention. 
  • Transparent Step Auditing: With path values clearly visible in the info section of each generated step, you can immediately inspect, verify, and debug the exact navigation paths the AI mapped out. 

Seamless SAP Scripting: Real-Time Locator Access! 

The Challenge: 

Building automated tests for complex SAP web interfaces (like SAP Fiori) requires highly specific, often intricate element locators. Previously, gathering these unique SAP locators meant testers had to frequently break their workflow—jumping between separate recording sessions, external inspection tools, or complex documentation just to copy and paste the correct identifiers into their test steps. This context-switching drastically slowed down the test creation process and increased the risk of manual errors.  

The Fix: 

We have fully integrated SAP Recorded Locators directly into the Web Testing builder. Now, while you are actively constructing your test steps on the canvas, you have immediate, real-time access to the specialized SAP locators you need without ever having to leave the test building interface.  

How will it help? 

This workflow enhancement removes the friction of testing complex SAP environments. 

  • Accelerated Test Building: Say goodbye to context-switching. You can now design, configure, and assign the correct SAP locators fluidly within a single, unified workspace. 
  • Pinpoint Accuracy: By pulling recorded locators directly into your builder, you significantly reduce the risk of typos or incorrect element identification, ensuring your tests are robust from the start. 
  • Developer-Friendly Experience: This seamless integration makes building complex SAP web tests faster, more intuitive, and far less tedious for your automation engineers. 

Seamless CI/CD Integration: Jenkins & Azure Plugins for Desktop Testing! 

Jenkins & Azure Plugins for Desktop Testing

The Challenge:  

As organizations modernize their deployment pipelines, manual testing interventions create significant bottlenecks. Previously, triggering automated scripts for Desktop applications required users to step outside of their primary CI/CD workflows. Without native plugins for popular orchestration tools, teams had to rely on cumbersome manual triggers or complex, custom-built scripts to initiate their Desktop Testing suites, resulting in disjointed delivery pipelines and slower release cycles. 

The Fix:  

We have officially introduced dedicated Jenkins and Azure DevOps plugins specifically for the Desktop Testing Service. These new plugins empower you to seamlessly trigger and manage your automated desktop application scripts directly from your existing CI/CD pipelines, bringing the service up to parity with our Web, API, and Mobile testing offerings. 

How will it help?  

This integration bridges the gap between your desktop application builds and your automated testing ecosystem. 

  • Unified Workflows: Manage your entire testing strategy—across Web, Mobile, API, and now Desktop—from a centralized CI/CD control plane. 
  • Frictionless Automation: Automatically execute robust desktop automation scripts the moment a new build is deployed, eliminating manual handoffs and accelerating your time-to-market. 
  • Developer Flexibility: Empower your engineering teams to seamlessly embed desktop quality gates into the familiar Jenkins or Azure environments they already use every day. 

Continuous Execution: Connect to Existing SAP Windows! 

Connect to Existing SAP Windows

The Challenge:  

When automating complex desktop workflows within SAP GUI, test scripts traditionally forced a brand-new application instance to launch for every execution. If a test failed midway or if an engineer wanted to resume a specific sequence after manual intervention, they were forced to restart the entire SAP login and navigation flow from scratch. This rigid behavior created duplicate windows, consumed unnecessary system resources, and drastically slowed down test debugging and multi-step process validations. 

The Fix:  

We have implemented powerful session persistence capabilities within the Desktop Testing Service. Using a robust “attach-to-window” mechanism for Windows environments, we’ve introduced a dedicated ‘Connect To Existing SAP Window’ action. This allows your desktop automation to intelligently detect and hook into an already-open SAP session instead of triggering a fresh launch. 

How will it help?  

This workflow upgrade brings true continuity to your desktop SAP automation. 

  • Resume Without Restarting: Easily continue an automation flow exactly where it left off, or seamlessly transition between manual steps and automated executions without losing your session state. 
  • Optimize System Resources: Prevent your desktop environment from being cluttered with redundant, duplicate SAP application instances during iterative testing and debugging. 
  • Accelerate Debugging: By bypassing the initial login and navigation sequences, automation engineers can rapidly test and refine specific downstream actions directly within an active SAP window. 

Secure & Streamlined: QloudBridge Encryption & Login Upgrades!

The Challenge:  

QloudBridge acts as the vital tunnel connecting your local desktop environments to the Qyrus cloud platform. Any weakness in how this data is encrypted during transit poses a significant security risk for enterprise teams handling sensitive test data. Additionally, a clunky or unstable login flow creates unnecessary friction when engineers are trying to spin up local testing sessions. When underlying build issues cause these connections to drop unexpectedly, it disrupts automated runs and delays the entire testing cycle. 

The Fix:  

We have significantly enhanced the QloudBridge security architecture by rolling out updated, enterprise-grade encryption protocols alongside a completely refined, smoother login flow. In tandem with these security hardening measures, we have successfully resolved underlying infrastructure and build bottlenecks that were previously causing minor connection instability. These updates have been fully verified on our staging environments and are operating exactly as expected. 

How will it help?  

This underlying infrastructure update provides a more resilient and secure testing foundation. 

  • Hardened Data Security: Your local test data and application traffic are now protected by even stronger encryption during transit, satisfying the most rigorous enterprise compliance standards. 
  • Seamless Authentication: The improved login flow makes it faster and significantly more intuitive to authenticate and connect your local machine to the platform, removing friction from your daily workflow. 
  • Unshakeable Stability: By resolving the core infrastructure issues, we’ve ensured a highly reliable, persistent connection that won’t unexpectedly drop during your long-running desktop automation suites. 

Flawless Connections: Enhanced iOS Device Streaming!

The Challenge:  

Interacting with cloud-hosted iOS devices could sometimes suffer from slight video latency, dropped frames, or momentary disconnections during intense manual testing sessions or heavy automated runs. This streaming instability caused frustration, making it difficult to test UI responsiveness accurately or to confidently debug complex touch interactions on Apple hardware. 

The Fix:  

We have implemented major infrastructure upgrades to the device streaming protocol specifically for iOS device sessions. This includes optimized video encoding and a much more resilient connection architecture to ensure a rock-solid, high-definition stream between the physical iPhones and iPads in our data center and your local browser. 

How will it help?  

This underlying upgrade makes remote iOS testing feel like the device is sitting right on your desk. 

  • Silky Smooth Manual Testing: Experience near-zero latency when interacting with remote iOS devices, allowing for precise gestures, swipes, and taps without frustrating delays. 
  • Rock-Solid Stability: Say goodbye to dropped sessions and frozen screens. The hardened connection ensures uninterrupted testing, even during extended, deep-dive debugging workflows. 
  • Accurate UI Validation: A crystal-clear, lag-free stream means you can confidently validate animations, transitions, and overall application responsiveness without the interference of network jitter. 

Independent Orchestration: Decoupled Licensing!

The Challenge:  

Previously, using Test Orchestration (TO) was strictly tied to your active module licenses for Web, Mobile, API, or Desktop testing. If one of those underlying service licenses expired or became inactive, it created a hard functional blocker within TO—even for users whose primary role was just to build and manage orchestrated workflows. This rigid dependency disrupted continuous testing strategies and unnecessarily complicated license management across large QA teams. 

The Fix:  

We have completely decoupled Test Orchestration from these underlying service-module dependencies. TO now operates as a fully independent orchestration layer. You can seamlessly build, manage, and execute orchestration scripts without requiring active Web, Mobile, API, or Desktop module licenses. Crucially, the platform still securely respects your existing role-based access controls (RBAC) and accurately governs execution capacity based purely on your available Browser and Mobile execution inventory. 

How will it help?  

This licensing update provides greater flexibility and removes arbitrary administrative blockers from your orchestration workflows. 

  • Uninterrupted Orchestration: Continue building, managing, and executing your complex test flows without unexpected access blocks caused by individual module license expirations. 
  • Streamlined Team Access: QA managers and orchestration engineers can now freely utilize the TO workspace to coordinate overarching test strategies without consuming individual service-module licenses. 
  • Resource-Based Scaling: Scale your orchestrations naturally based on your actual execution capacity (Browser/Mobile slots) rather than being restricted by module-level licensing. 

Batch Execution: Folder-Level Scheduling!

The Challenge:  

Managing and scheduling large test suites can quickly become an administrative burden. Previously, if you wanted to schedule a group of related workflows to run at the same time, you had to configure the scheduling parameters for each workflow individually. This repetitive process was not only tedious and time-consuming but also increased the risk of manual configuration errors across your test batches. 

The Fix:  

We have introduced a powerful new Folder-level Scheduler within Test Orchestration. Instead of managing individual scripts one by one, you can now apply a single scheduling configuration to an entire folder. This instantly schedules multiple workflows contained within that folder to execute using the exact same parameters. 

How will it help?  

This enhancement dramatically simplifies the administration of massive test suites. 

  • Massive Time Savings: Eliminate repetitive setup tasks by configuring the schedule once at the folder level, instantly applying it to dozens of underlying workflows. 
  • Guaranteed Consistency: Ensure that all related tests in a specific batch run with the exact same configurations, environments, and timing rules, eliminating configuration drift. 
  • Effortless Scalability: As your test suites grow, managing execution schedules remains simple and organized by leveraging your existing folder hierarchies. 

Enterprise-Ready Execution: Node CLI Plugin Upgrades for qAPI! 

The Challenge:  

Managing API performance and functional testing via command-line interfaces across large, enterprise-level teams can get complicated. Previously, fetching project details via the CLI relied on user email addresses, which didn’t scale well within complex enterprise structures where team-based access is the standard. Furthermore, sharing the results of CLI-triggered test runs often involved manual data extraction or wrestling with clunky file sharing, creating friction for teams trying to review execution reports quickly. 

The Fix:  

We have significantly upgraded the Node CLI Plugin for qAPI to better support enterprise workflows. First, we transitioned project fetching from user emails to team IDs (/projects?teamId), perfectly aligning the CLI with robust, enterprise-grade project management structures. We also introduced a new feature (/get-reports-url) that automatically generates a secure CDN link for your execution reports—valid for seven days—directly from the command line. 

How will it help?  

These CLI enhancements streamline headless API testing for large-scale engineering teams. 

  • Enterprise-Scale Management: Fetching project data based on Team ID ensures the CLI integrates flawlessly with complex organizational structures and role-based access configurations. 
  • Instant Report Sharing: Automatically generate secure, temporary CDN URLs for your test reports straight from the CLI, making it incredibly simple to share results with your team or attach them to build logs. 
  • Streamlined Automation: With a dedicated CLI plugin type and x-api-key support for URL generation, building secure, automated qAPI testing pipelines into your CI/CD processes is smoother than ever. 

Seamless Navigation: Enhanced Project Listing!

Enhanced Project Listing

The Challenge:  

As enterprise teams scale their API testing footprints, the number of active projects can grow rapidly into the dozens or hundreds. Previously, the qAPI dashboard restricted the project view—only loading the first page of 15 projects and preventing users from scrolling or navigating to see the rest of their portfolio. This forced teams to rely on direct links or search workarounds just to access older or lower-priority projects. 

The Fix:  

We have resolved this limitation by overhauling the data-fetching and pagination logic within the qAPI project dashboard. Following successful validation in our staging environments, the fix is fully deployed, ensuring that your complete catalog of projects now loads fluidly and accurately across all pages. 

How will it help?  

This fix restores complete visibility and smooth navigation to your workspace. 

  • Full Portfolio Visibility: Effortlessly browse through your entire history of API testing projects without arbitrary UI cutoffs or missing entries. 
  • Frictionless Browsing: Experience smooth, reliable page loading as you scroll through large collections of enterprise projects. 
  • Better Team Coordination: Large testing teams can now confidently organize and locate their respective projects from a single, uncompromised dashboard view. 

Enhanced Traceability: Script-Level Xray Visibility within Suites!

The Challenge:  

When managing large API test suites integrated with Jira Xray, it can be difficult to track which individual scripts are properly linked to your test management tools. Since Xray determines suite execution status based on its underlying linked scripts rather than a standalone suite-level configuration, testers previously had to open each script individually to verify its Xray integration details. This lack of centralized visibility made auditing large test suites time-consuming and error-prone. 

The Fix:  

We have enhanced the visibility of Xray integration configurations directly within the qAPI test suite view. While direct suite-level configuration isn’t native to Xray, you can now click the integration icon at the suite level to immediately view a clear breakdown of the linked scripts alongside their respective Xray integration details and script names. 

How will it help?  

This update centralizes your integration tracking, making test management much more transparent. 

  • Centralized Integration Audits: Instantly verify which scripts within a suite are correctly mapped to Xray without toggling back and forth between individual script configurations. 
  • Clear Execution Mapping: Easily understand how your suite-level execution status will flow back to Jira based on a clear visual summary of its underlying scripts. 
  • Streamlined Troubleshooting: Quickly identify unlinked or misconfigured scripts directly from the high-level suite overview, keeping your test management system perfectly synchronized. 

Ready to Leverage May’s Innovations? 

We are committed to providing a unified platform that not only adapts to your evolving needs but also streamlines your critical processes, empowering you to release high-quality software with greater speed and confidence. 

Eager to explore how these advancements can transform your testing efforts? The best way to appreciate the Qyrus difference is to experience these new capabilities directly. 

Ready to dive deeper or get started? 

Book a Personalized Demo

Featured Image-Self-healing Test Automation

It’s Monday morning. Your CI pipeline ran overnight and you open your test dashboard to find 180 tests failing. The app isn’t broken. No bug was introduced. Over the weekend, a developer refactored the frontend component library, wiping out every CSS class name your test suite depended on. Not a single real defect. Just 180 broken locators standing between your team and the Friday release. 

This is the maintenance trap that quietly drains QA programs every single week. The more you invest in test automation, the larger the surface area that shatters the moment your application evolves. And in teams shipping multiple times a day, that means an endless cycle of triage, diagnosis, and manual repair work that pulls engineers away from the things that actually matter: building new coverage, exploring edge cases, and shipping features. 

Built to break this cycle, self-healing test automation leverages artificial intelligence and machine learning to detect failures caused by UI or element modifications. The system dynamically identifies the intended element using alternative architectural attributes, updates the script in real time, and resumes execution without human intervention. 

This guide covers everything you need to know: what self-healing is, how it works under the hood, where it makes the biggest difference, what to watch out for, and how to implement it well. Whether you’re a QA engineer drowning in broken locators, an engineering manager trying to protect release velocity, or a CTO evaluating your automation strategy, this is your practical reference. 

What Is Self-Healing Test Automation? 

Self-healing test automation is an AI-powered capability that allows an automated test to detect when it cannot find a UI element, search for that element using alternative identifiers, repair the broken locator, and continue executing without any manual intervention. 

Think of it like GPS navigation. When you miss a turn, your GPS does not shut off and report failure. It recalculates the route, finds a new path, and gets you to the destination anyway. Self-healing test automation works on exactly the same principle: when the expected path breaks, the system finds another way and keeps going. 

The root problem it solves is locator brittleness. Traditional automated tests rely on locators such as IDs, XPath expressions, CSS selectors, element names, and text content to find and interact with UI elements. These locators are recorded at test creation time and hardcoded into the script. The moment a developer renames a button ID from ‘login-btn’ to ‘auth-submit’, or moves a div inside a new container, every test that referenced that element fails with a NoSuchElementException. 

With traditional testing, the mentioned failure looks like this: test fails, engineer gets paged, engineer investigates, engineer updates the locator, pipeline resumes. That cycle can span from 30 minutes to several days, based on the number of affected scripts and the complexity of the change. 

Conversely, a self-healing framework completely alters this. When a missing element is detected, the healing engine instantly evaluates secondary attributes, resolves the locator drift, resumes the test execution, and logs the event for asynchronous engineering review. The pipeline remains uninterrupted, eliminating false-positive pages. This is not about making tests that never fail. It is about making sure tests fail only when there is a real problem with the software, not because a button label changed.

qyrus-traditional-vs-self-healing-flow

Why Test Maintenance Is Quietly Killing Your QA Program 

The numbers are hard to argue with. Research from Capgemini’s World Quality Report 2024-25, cited by QASource, found that script maintenance consumes up to 50% of test engineering time due to constant application changes. An analysis of 40 startups published on Medium in 2026 found teams spending 60 to 70% of QA time on upkeep, leaving only 30 to 40% for actually building new coverage. 

 This maintenance burden compounds destructively over time. Early in a product lifecycle, frontend elements remain relatively stable. However, as the application scales, three primary forces accelerate degradation: expanding feature sets increase test volume, widening the surface area vulnerable to code changes; modernizations like React framework upgrades trigger cascading locator failures; and growing test suites multiply the number of scripts referencing a single volatile element. 

There is also a talent cost that rarely gets quantified. A 2026 analysis found that triaging flaky tests requires both application architecture knowledge and test framework expertise simultaneously. That work concentrates on your most senior engineers. A senior QA engineer earning $140,000 annually who spends 30% of their time on test maintenance is absorbing roughly $42,000 of pure overhead per year. Not fixing bugs. Not building coverage. Updating locators. 

Then there is the false positive problem. When tests fail not because the software is broken, but because a class name shifted, it erodes trust in the entire test suite. Engineers start ignoring failures. Red pipelines stop being alarming. The automation you invested in stops being a safety net and becomes background noise. 

One more widely misunderstood reality: most tools marketed as ‘self-healing’ only address locator breakage. But according to QA Wolf research published in 2026, brittle selectors cause only about 28% of test failures in real-world suites. The remaining 72% come from timing problems, invalid test data, runtime errors, visual assertion failures, and interaction changes. Fixing only the locators while ignoring the rest means 72% of flakiness remains untouched. 

For an automation strategy to deliver a true return on investment, teams must look past basic locator-fixing utilities and adopt comprehensive platforms that handle data states, environment availability, and timing synchronization dynamically. 

qyrus-test-failure-causes-chart

How Self-Healing Test Automation Works 

Understanding self-healing at a mechanical level helps you choose the right tool and implement it correctly. The process follows four distinct phases. 

Phase 1: Element Fingerprinting 

When a test is first created, the self-healing system captures a rich fingerprint of every UI element it interacts with. Rather than recording a single locator, it records multiple attributes simultaneously: the element ID, name, CSS selector, XPath, text content, ARIA labels, and the element’s relative position within the DOM tree. Some advanced systems also capture visual attributes through screenshots. 

This multi-attribute profile gives the healing engine a redundant set of identifiers to fall back on when the primary one breaks. It is the difference between knowing one route to a destination versus knowing five. 

By shifting from a single locator strategy to an object-model representation, the framework constructs a dynamic map of the application’s user interface rather than a fragile list of hardcoded coordinates. 

Phase 2: Test Execution 

During a test run, the framework attempts to locate elements using their primary identifiers exactly as scripted. The vast majority of steps will execute normally. When the primary locator succeeds, no healing occurs and no performance overhead is added. 

The system only activates when an element cannot be found via its primary identifier. At that point, rather than immediately reporting a failure, the healing engine is triggered. 

Phase 3: Diagnosis 

This is where more sophisticated self-healing tools differentiate themselves. A basic tool assumes every failure is a locator problem and tries alternative selectors. A diagnosis-first tool asks: what type of failure is this? 

Diagnosis-first systems capture runtime artifacts including DOM snapshots, network activity logs, console errors, and application state. They categorize the root cause before applying any fix. If the element is missing because an API response was slow and the page has not finished rendering, patching the locator achieves nothing and may cause a false pass. The right fix is adding a resilient wait or retry. If the element’s ID changed, updating the locator is correct. If it is a visual assertion failure, a screenshot comparison is needed. 

The AI and machine learning techniques involved include: computer vision using convolutional neural networks (CNNs) for visual element identification; natural language processing (NLP) to understand semantic meaning (so ‘Sign In’ and ‘Log In’ are recognized as functionally equivalent); supervised learning from historical test execution data to predict stable locator strategies; and fuzzy matching to score candidate elements by similarity of text, attributes, and DOM structure. 

Phase 4: Self-Healing Action 

Once the correct element is located through an alternative strategy, the system updates the test script with the new locator value and resumes execution. The original run completes and future runs use the healed locator. 

Critically, every healing event is logged. Best-in-class tools display the old locator value alongside the new one and prompt an engineer to review and approve the change before it is permanently committed. This human-in-the-loop validation ensures that legitimate functional regressions are never masked by over-eager healing. The script adapts to real UI changes. It does not silently pass when something actually broke. 

qyrus-4-phases-self-healing

Key Benefits of Self-Healing Test Automation 

“Teams using AI-based testing tools reduced maintenance effort by up to 70% and improved CI/CD pipeline stability by nearly 50%.” – Capgemini World Quality Report 2024-25 

The most immediate and quantifiable benefit is the reduction in time spent on test maintenance. Capgemini’s World Quality Report 2024-25 found that teams using AI-based testing tools reduced maintenance effort by up to 70% and improved CI/CD pipeline stability by nearly 50%.  

The second major benefit is the elimination of false positives. When tests no longer fail due to minor UI changes, the signal-to-noise ratio in your test suite improves dramatically. Engineers stop ignoring red builds. When a test does fail, the team can trust it represents a real issue. This rebuilds confidence in the automation program and makes QA a reliable partner in the release process rather than a bottleneck. 

Self-healing directly accelerates CI/CD pipelines. With healing running automatically on every build, the pipeline stays green through routine UI changes without any human intervention required. Developers get fast, reliable feedback after every commit. The feedback loop that makes continuous delivery work remains intact even as the application changes constantly underneath it. 

Better test coverage is another downstream benefit that often goes unrecognized. When QA engineers are no longer spending half their time fixing broken locators, they have capacity to build new tests. Coverage expands. More business flows get validated. The automation program actually grows instead of just trying to maintain what already exists. 

For mobile testing specifically, self-healing addresses a particularly acute pain point. Mobile applications update frequently, often with UI structures that change significantly between versions and behave differently across iOS and Android. Teams that implement self-healing in mobile CI/CD pipelines report 20 to 30% faster release cycles according to Quinnox’s 2025 analysis. Healing corrects locator differences across device types without any per-device manual tuning. 

Finally, the return on investment is measurable and arrives quickly. CloudQA’s 2026 testing trends report found that enterprise organizations adopting self-healing scripts demonstrated a 95% reduction in manual maintenance overhead. The upfront investment in tooling is typically recovered within a single release quarter when measured against the engineering hours no longer lost to locator repair. 

Where Self-Healing Test Automation Makes the Biggest Difference 

Web Applications with Frequent Releases 

Consider an e-commerce team that ships a CSS refactor as part of a brand refresh. The development team renames dozens of button class names and updates div structures across checkout, cart, and account pages. Under traditional automation, this triggers mass test failures. Not because checkout is broken. Because the test scripts are looking for class names that no longer exist. 

With self-healing in place, the testing platform detects the broken selectors, identifies each button via its visible text label, ARIA role, and relative DOM position, updates the locators, and completes the run. The pipeline stays green. A healing report is generated summarizing every locator that was updated, which the QA lead reviews the next morning. The release ships on schedule. 

Mobile Testing Across Devices and OS Versions 

A fintech mobile app ships a redesigned payment screen to comply with updated accessibility guidelines. The Submit button has been repositioned, its ID has changed, and the surrounding layout is different on smaller devices than on larger ones. Tests that were working perfectly on iPhone 14 now fail on iPhone SE. 

Self-healing handles the positional differences automatically. By capturing multiple locator strategies at test design time, including text content, ARIA labels, and proximity to other stable elements, the healing engine identifies the correct button regardless of where it landed on each device. The test suite runs cleanly across the full device matrix without any per-device locator maintenance. 

SAP Fiori and Enterprise ERP Testing 

This is where self-healing delivers some of its most significant enterprise value, and where most competitors leave organizations on their own. 

SAP operates on a structured release cycle that includes major upgrades, Feature Package Stacks (FPS) delivered three times per release, and regular Support Package Stacks (SPS). Each release changes Fiori control IDs, app structures, and field names in ways that systematically break traditional test automation. According to ContextQA’s 2026 SAP testing guide, manual regression for a SAP environment with 200 or more active business processes takes 4 to 8 weeks. With automated testing, that same coverage takes 4 to 8 hours. 

Without self-healing, those 4 to 8 hours of automated testing become days of manual locator repair after every SAP quarterly update. With self-healing integrated into the SAP testing workflow, the automation adapts to each new release automatically, keeping the regression suite operational across upgrades. 

This drastically compresses the traditional testing timeline, allowing enterprise IT leaders to align their core ERP updates with rapid agile sprint cadences without risking business process downtime. 

When to Be Cautious 

Self-healing is not appropriate everywhere, and a credible guide should say so directly. For security-sensitive flows such as banking transactions or authorization changes, the consequences of a false pass are serious enough that human review should precede any test continuation. For exact layout or copy validation tests, where the precise position of an element or its exact text content is what you are testing, visual regression testing is the more appropriate tool. Self-healing adapts to change; visual regression detects it. 

qyrus-self-healing-use-cases

How Qyrus Healer Takes Self-Healing Further 

Most self-healing tools pick a lane: web or mobile, UI or API, one platform or one framework. Qyrus Healer was built differently. 

A patent-backed approach. Qyrus Healer holds U.S. Patent 11,205,041 B2 for self-healing test automation. This is one of the few solutions in the market where the core healing algorithm is protected by a registered patent, reflecting the proprietary nature of the approach rather than a repackaging of generic AI libraries. 

No advance training required. Many AI-based testing tools need a period of historical execution data before their healing becomes reliable. Qyrus Healer’s patented algorithm works out of the box on any application, without requiring prior training runs. From the first execution, it intelligently identifies element changes across the application lifecycle and updates locators using a custom distance metric. 

99.9% accuracy. Healer achieves an accuracy rate of over 99.9% on locator identification and repair, minimizing false positives and ensuring that healed scripts genuinely reflect the current state of the application rather than introducing new errors. 

Web and mobile in one. Most self-healing solutions are siloed to either web or mobile testing. Qyrus Healer works across both platforms within a single unified environment. Web application tests and mobile application tests running on real devices through Qyrus Device Farm both benefit from the same healing capabilities. 

SAP Fiori integration. Qyrus Healer powers a unique SAP Fiori testing workflow through the Fiori Test Specialist module. When the AI-assisted test generator produces test steps with incorrect or missing Control IDs, the Healer pauses execution at the failing step, automatically scans the live Fiori/UI5 application to identify the correct technical field names and control IDs, corrects the values, and resumes execution. The healed values are shown alongside the original for review before being committed.  

Baseline script approach. Healer AI activates for Execute Test runs where a previous passed scenario report exists. It references that successful baseline and suggests updated locators, primarily ID, Class, and XPath values, to accommodate discrepancies found in the current run. This baseline-anchored approach means healing is always grounded in a known-good state of the application. 

For teams using Qyrus across web, mobile, API, and SAP testing, Healer provides a consistent self-healing layer across the entire testing program rather than requiring a different healing strategy per platform. You can learn more about Qyrus’s approach to web testing, mobile testing, and SAP testing, or book a demo to see Healer in action. 

Self-Healing Test Automation in CI/CD Pipelines 

CI/CD is where self-healing delivers its sharpest return on investment. Multiple deployments per day mean multiple opportunities for locator breakage. Without healing, every UI change is a potential pipeline blocker. With healing integrated at the pipeline level, those changes are absorbed automatically, and the deployment cadence is never interrupted. 

Integration works by hooking the self-healing engine directly into your pipeline trigger. When a developer merges a pull request or a build completes in Jenkins, Azure DevOps, or a similar tool, the test suite fires. If any locators have changed, the healing engine repairs them during that run. No human needs to intervene. No deployment waits for a QA engineer to investigate a false positive. 

Teams that implement CI-integrated healing typically find that 5 to 10% of locators fail after each UI update under normal conditions. With healing running at the pipeline level, the majority of those failures are resolved instantly. Quinnox’s analysis found that teams adopting this approach achieve 20 to 30% faster release cycles and experience far fewer pipeline halts due to broken tests. 

The recommended practice is not to auto-commit every healed locator without review. Instead, the AI proposes the fix and the pipeline continues. At the end of the sprint, a QA engineer reviews the healing log, which shows every step that was updated with the old and new values side by side. They approve changes that reflect genuine UI evolution, and flag any that look suspicious. This human-in-the-loop rhythm maintains trust in the test suite without sacrificing deployment speed. 

Qyrus integrates natively with the full range of CI/CD and version control tools that enterprise teams rely on, including Jenkins, Azure DevOps, Bitrise, TeamCity, Concourse, GitHub, and Bitbucket. Self-healing is available as a toggle in the run configuration, so it can be enabled or disabled per execution type without requiring any pipeline reconfiguration. 

Best Practices for Implementing Self-Healing Test Automation 

Self-healing is powerful, but it works best when you design your test suite to support it rather than expecting it to compensate for poor locator hygiene. 

  • Start with stable locator design. The best locators to use as primary identifiers are role-based selectors, visible text content, ARIA labels, and dedicated test attributes like data-testid. These change less frequently than generated IDs or dynamic class names. Self-healing compensates for locator drift, but fewer healing events mean faster runs and less noise in the healing log. 
  • Do not over-trust automatic fixes. If the healing engine is configured to be too permissive, it can mask real functional regressions. A button that has genuinely been removed from the application should fail the test, not be healed into clicking something else. Review healing logs regularly and configure confidence thresholds appropriately for your risk tolerance. 
  • Maintain a complete audit trail. Every healed step should be logged with the old locator value, the new locator value, the alternative matching strategy used, and the timestamp. This trail is essential both for debugging unexpected behavior and for demonstrating test reliability to auditors in regulated industries. 
  • Combine with visual regression testing for layout-sensitive flows. Self-healing adapts to locator changes. It does not validate that the visual layout of a page is correct. For flows where the exact positioning of elements matters, use visual regression testing alongside self-healing. The two capabilities are complementary, not interchangeable. 
  • Schedule periodic manual reviews. Monthly or quarterly reviews of healed steps confirm that the healing engine’s updates genuinely reflect intended UI changes rather than masking defects. This is especially important as the application scales and the volume of healing events grows. 
  • For SAP and ERP environments, run healing against a validated baseline first. Use a known-good, full-regression baseline execution as the reference point. Healing suggestions are always evaluated against that baseline, so the system knows what ‘correct’ looks like before proposing any changes. This prevents healing from propagating errors forward if a previous run already contained a defect. 

 The Future of Self-Healing Test Automation 

The self-healing tools available today are reactive: they detect a failure, diagnose it, and apply a fix. The next generation will be predictive. 

Predictive healing analyzes upcoming code commits before tests run. It identifies which locators in the existing test suite are likely to be affected by a proposed change, and pre-updates them so that the test run after the commit completes cleanly from the start. Instead of healing after a failure, the system prevents the failure from occurring in the first place. 

Agentic AI is the broader force reshaping how this works. Gartner forecasts that AI agents will independently handle up to 40% of QA workloads by 2028, including regression testing, smoke testing, maintenance, and bug triage. Standard self-healing addresses individual broken locators. Agentic AI reasons across entire test suites, makes decisions about test strategy, and executes multi-step recovery workflows without any human direction. 

Vision-based testing is another emerging direction that could reduce DOM dependency entirely. Rather than relying on HTML attributes and DOM structure, vision-based tools identify UI elements the way a human tester would: by looking at the screen. A button is a button because it looks like a button and sits in the context of a form, regardless of what its underlying ID happens to be on any given day. 

The 2026 software testing trends report from CloudQA puts this trajectory in concrete terms: self-healing scripts have demonstrated a 95% reduction in manual maintenance in early enterprise adopters, and organizations embedding generative AI into testing workflows are reporting a 40% increase in test coverage and a 10x improvement in overall productivity. 

For business and engineering leaders, the strategic implication is straightforward. The teams that invest in self-healing and agentic testing infrastructure now are not just reducing a maintenance overhead. They are building the quality assurance foundation that makes it possible to release confidently at the speed their customers expect. 

qyrus-test-automation-evolution-timeline

FAQs on Self-Healing Test Automation 

 1: What is self-healing test automation?  

 Self-healing test automation is an AI-powered capability that allows automated test scripts to detect when a UI element or locator has changed, find the correct element through alternative identifiers, update the script automatically, and continue running without any manual intervention. Instead of failing with a NoSuchElementException and waiting for an engineer to fix it, the test adapts on the spot. 

2: How is self-healing different from traditional automated testing?  

Traditional automated tests rely on a single hardcoded locator (an ID, XPath, or CSS selector) to find each UI element. When that locator breaks due to a UI change, the test fails and a human has to investigate and repair it. Self-healing tests capture multiple attributes for each element at test creation time, so when the primary locator fails, the system tries alternatives automatically. The key difference: traditional tests are brittle by design. Self-healing tests are built to absorb change. 

3: Does self-healing work for both web and mobile testing?  

Yes, though not every tool supports both. Most self-healing solutions focus exclusively on web automation. Qyrus Healer is specifically built to work across both web and mobile platforms within a single environment, including on real devices through Qyrus Device Farm, which means teams running both web and mobile test suites get consistent healing behavior without switching tools or strategies. 

4: Can self-healing test automation handle SAP Fiori testing?  

Most self-healing tools do not address SAP Fiori at all, which is a significant gap. SAP upgrades regularly change Fiori control IDs and app structures, making traditional test scripts fragile after every release. Qyrus Healer powers a dedicated SAP Fiori workflow through the Fiori Test Specialist module. When a test step fails due to an incorrect control ID, Healer pauses, scans the live Fiori/UI5 application, identifies the correct field names, corrects the values, and resumes execution. 

5: Will self-healing hide real bugs by making failing tests pass?  

This is the most important concern to address honestly: yes, it can, if implemented poorly. If a healing engine is too permissive, it may fix a locator when the real issue is that a feature has been removed or a flow has genuinely broken. The safeguard is human-in-the-loop review. Best-in-class self-healing tools log every healing event with the old and new locator values, and prompt an engineer to approve changes before they are permanently committed. Self-healing should never run silently with no audit trail. When implemented correctly, it reduces noise from false positives without masking real defects. 

Stop Fixing Tests. Start Shipping Software. 

Go back to Monday morning. Your pipeline ran overnight. You open the dashboard. 180 tests ran. 180 passed. The frontend team’s CSS refactor landed cleanly. The component library update was absorbed automatically. The healing log shows 23 locators that were updated overnight, each one reviewed and approved, each one correct. And your team ships on Friday. 

That is what self-healing test automation actually delivers. Not a magic system that never breaks. A practical infrastructure that stops tests from failing for the wrong reasons, keeps your CI/CD pipeline moving, and gives your QA team back the time they need to do the work that actually requires human judgment. 

The data is clear. Maintenance consumes up to 50% of QA engineering time under traditional automation. Teams that adopt AI-based self-healing reduce that burden by 70%. The releases come faster. The test suite grows instead of stagnating. The Monday morning dashboard becomes something you look forward to rather than dread. 

The technology is here, it works, and the organizations investing in it now are building a sustainable competitive advantage in release quality and speed. 

If you want to see how Qyrus Healer handles self-healing across web, mobile, and SAP Fiori testing in a single platform, book a demo with the Qyrus team.