How To Evaluate LLMs: A Guide for People Who Need Real Answers
 Varun RS
Everyone is potentially planning to build or already built their built their own LLM tool to make their jobs easier. But setting it up has taken more than anyone had planned for. With Claude, OpenAI and even Meta (muse) bringing in their products to the public there has been a lot of noise and less in terms of customized implementation.
Only the one’s with hands-on experience have managed to actually build a completely customized and functional LLM. But where is the other half, are they able to build and evaluate LLMs to ensure it works as they wanted?
Keep that thought on hold
Let’s say at work you’ve been handed a task. Maybe it’s “pick the best LLM for our product.” Maybe it’s “figure out why our AI responses are getting worse.” Maybe it’s “build a system that tells us when our model is failing before a customer notices.”
Whatever the task, you quickly run into the same problem some will have a preference or search online and get recommendations. Eventually post some research and validation everyone will have a preference. For some driven by benchmarks for some a simple engineering decision.
All this started when GPTs actually was released to public and we are still trying to play catch up on the pace these tools and their capabilities are evolving.
So where do you go from here?
Let’s say the existing tools are no longer enough. There is a high chance that the reports you are referring to aren’t accurate/updated, or it can be a case where research quality is inconsistent, or the outputs simply don’t meet your expectations.
So then you decide to build your own solution using existing toolkit or custom infrastructure.
QyrusAI has built this guide is for the people who have to make real decisions engineers who are building production systems, architects choosing new service providers, people who are building chatbots or agents, researchers building evaluation pipelines completely from scratch.
We’ll start to see what these models are made of and walk through how to compare them with ease, how to go deep on methods and math, and end with the exact tools you need to build something that works.
What is an LLM?
Large language models (LLMs) is a framework that is developed by using Artificial Intelligence to make them capable of understanding and generating natural human language so it can understand prompts and generate human-like responses.
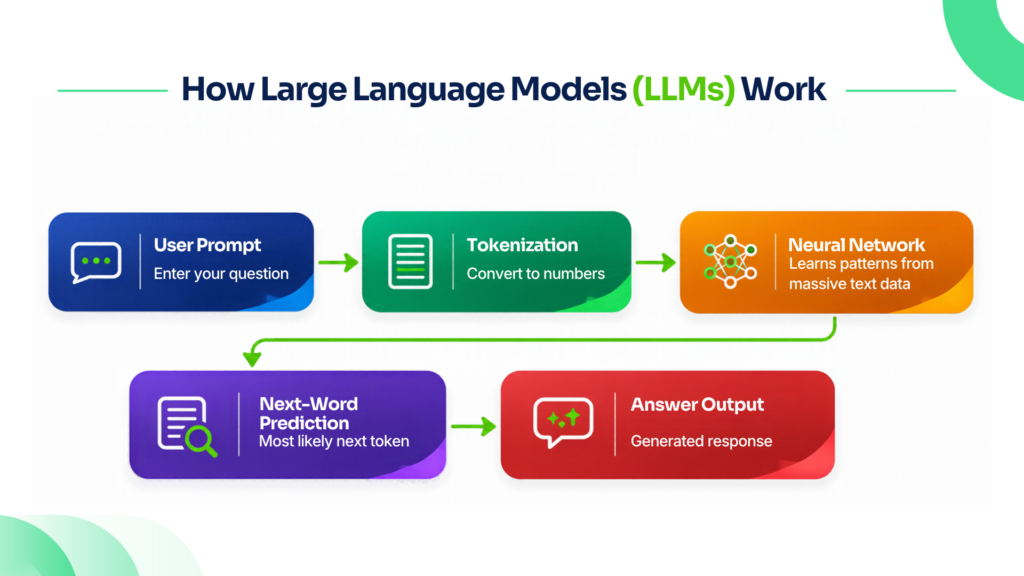
How Does an LLM Work?
LLM is a computer program that is trained through large data sets, from where it learns and understands context. And with the power of AI it puts it all together and gives us the output. It works by predicting and learning based on the patterns it learned during training.
An LLM works on a divide and conquer concept, first it breaks your text into smaller pieces or tokens, then turns those tokens into numbers the model can process. It uses a transformer architecture with attention framework to understand how words and phrases relate to each other which includes context and meaning and then moves to predicting the next token one step at a time to create a response.
In simplest of terms, it’s like you’re using a advanced model that can read the whole sentence, understands the relationships between words, and writes the most likely ideal response in a natural way.
How to Evaluate any LLM?
Before you get to evaluating anything, you need to understand what and how you’re evaluating. Simply asking “Best LLM” is a question that can only be answered by finishing the sentence: best for what? That is the part where you need to think.
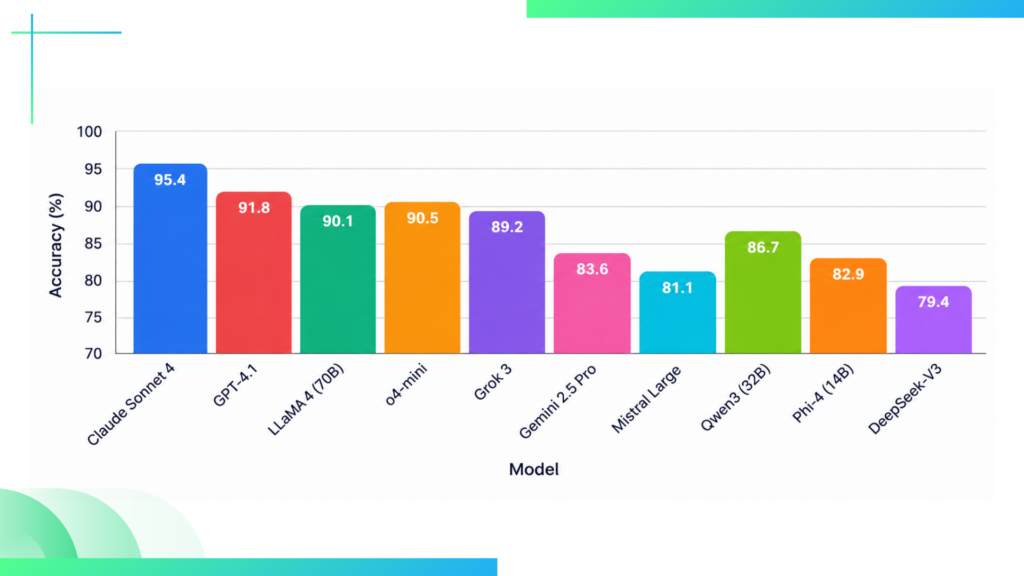
If you can see in the image above, the LLMs have been mapped for intelligence, but is that useful for your usecase?
Model | Best For |
Claude Opus 4.6 | Reasoning, coding and research |
GPT-5.6 and more | Equalized performance on all fronts, they have improved image generation |
Grok 4 | Math, agentic tasks and research |
Gemini 3.1 Pro | Multimodal, value, writing, scripting and coding |
GLM-5 | Open-source leader |
o1-preview | Context memory |
Claude Sonnet | Long context |
DeepSeek V3.2 | Coding efficiency, and feasible token usage |
Llama 4 70B | Fine-tuning, it doesnt need constant feedback |
Mistral Medium 3.1 | Cost-effective best for long usage |
What if you’ve used one of these tools to develop your own LLM?
How will you evaluate or check that it works as expected? How do you plan to identify its limitations, edge cases, or failure points before it reaches users? Have you marked the edge cases and parameters rightly? Using these tools are just the starting point, and while there are many available to help build models, building is only half part of the equation.
The real challenge will start post development which is validation phase. And I think we all are on the same page for that already.
For you an LLM might perform well in a demo environment yet fail when exposed to some random prompts, domain-specific questions, or large-scale production traffic. Without structured evaluation, teams are left relying on subjective testing. This approach clearly will not scale, nor will it provide measurable confidence in model quality in the future.
This is why LLM evaluation has become a critical part of our development lifecycle. You and your teams need to introduce frameworks to benchmark outputs against expected results, score responses for relevance and accuracy, compare prompt or model versions, and continuously monitor regressions over time. Challenge the model to situations that may arise apart from the one’s that already have.
Much like modern software testing has transformed application development, systematic LLM evaluation ensures that AI systems are not just functional—but that it’s reliable, measurable, and production-ready for you at all times.
What an LLM Evaluator Actually Does
An LLM evaluator is just like your exam supervisor it acts like a person, a script, another model, or a combination that can take an LLM’s output and validate it through a preset or custom made parameters about its quality.
That’s a deliberately broad definition, because the field has fractured into several distinct evaluation paradigms and each is appropriate for different contexts and use cases.
LLM-as-judge is the approach that’s taken over the field in the last two years. You use a capable model usually GPT-5 or Claude to score another model’s outputs on a scale. You can evaluate, without paying for human annotators, and you can evaluate open-ended outputs that would break any reference-based metric.
LLM judges are usually known to favor responses over concise ones, to prefer the first response shown in a pairwise comparison, and to represent stylistic preferences that may not match human preferences.
Your mitigation response should be to use multiple judges, randomize presentation order, and calibrate against human judgments to estimate your bias correctly.
The gold standard for code and structured output tasks is Execution-based evaluation. Why?
Because then you can run the generated code against a test suite and count whether the tests pass. The result is you get no subjectivity, no rubric as it either works or it doesn’t.
HumanEval and MBPP (the standard code benchmarks) have been constantly using this approach. SWE-bench goes a step ahead and evaluates whether a model can actually close real GitHub issues, which is a much harder test.
In actual workplace implementations, a mature evaluation system must be able to use all of the mentioned approaches above. As automated metrics run on every launch for regression detection.
LLM-as-judge should handle the open-ended quality signal. Execution-based evaluation takes over any tasks where the output can be mechanically verified. Human evaluation happens on a sample basis to keep the automated signals calibrated.
How to Compare LLMs Properly
Most LLM comparison tools fail for one reason: they use someone else’s test results to make a choice for your specific use case.
This does not mean benchmarks are bad. They are real and useful. But they measure tasks that may have little to do with what you are building.
For example, a model that scores high on MMLU (a test of general knowledge across 57 school and university subjects) may still do poorly on your customer support tickets. A model that scores low on HumanEval (a Python coding test) may be very good at the SQL queries your team needs.
Here is a simple way to compare LLMs for your own needs.
1. Step one: Build and deploy your LLM.
Once your LLM is deployed, set up your output XPath/JSON mapping. This tells the evaluator where to find the model’s answer.
The LLM output is the answer your model sends back. Where you find it depends on how you run the model:
If your LLM runs behind an API, the output is usually inside the JSON response.
Example:
{
“id”: “chatcmpl-123”,
“choices”: [
{
“message”: {
“content”: “The capital of France is Paris.”
}
}
]
}
In this case your output JSON path would be:
$.choices[0].message.content
If you’re using either of these tools:
- OpenAI Playground
- Azure AI Studio
- Hugging Face
- Internal LLM dashboards
The raw response/output panel will show exactly what the model returns.
In case If you are using frameworks like:
- LangChain
- LlamaIndex
- Haystack
The output may be wrapped in another object, e.g.:
{
“result”: {
“answer”: “Paris”
}
}
Path becomes:
$.result.answer
This shows where the required values are extracted from the model’s response so evaluating systems can process them correctly. If your mapping was incorrect, even valid outputs will break integrations.
So we suggest that you should also standardize response formatting, validate schema structure, and handle incomplete or malformed outputs before planning your next step.
2. Step two: Define your evaluation criteria.
What does “good” mean for your specific task? For a customer support use case, you might care about: accuracy, consistency, reasoning and edge-case handling.
Test prompts should always be validated against expected outputs, repeated runs should be cross-referenced for response drift, and failure scenarios should be tested to ensure stable behavior under unexpected input. In addition, you should implement monitoring, prompt/model versioning, confidence thresholds, and rollback mechanisms to maintain reliability after deployment.
3. Step three: Generate outputs blindly.
Run each model on your full prompt set without any important model related information in the evaluation process. If you’re using LLM evaluator, you should run tests with different models. This is harder to enforce than it sounds but it makes it easy to compare differences between different models.
4. Step four: Score on same parameters.
For each prompt, compare outputs reports for all. Which is better, or is it a tie? Pairwise comparison is more reliable than absolute scoring because it’s easier to judge relative quality than to assign a consistent score on an abstract 1–5 scale. Aggregate your pairwise results into a win rate or an Elo score (the same rating system used in competitive chess).
5. Step five: Analysis should be segmented.
We recommend that you don’t just look at overall win rate. Break your results down by task category if Model A wins on lets say 70% of reasoning tasks but loses on more than 50% of extraction tasks, and your product is mostly extraction, the overall win rate is not promising. Find the model that wins on the tasks that matter most to you.
The Evaluation Method That Actually Works
QyrusAI has launched LLM evaluator feature here’s how you can use it to evaluate your LLM.
Step 1: Once you’ve logged into the application, you need to open your test suite.
Step 2: Click on LLM Eval tab.
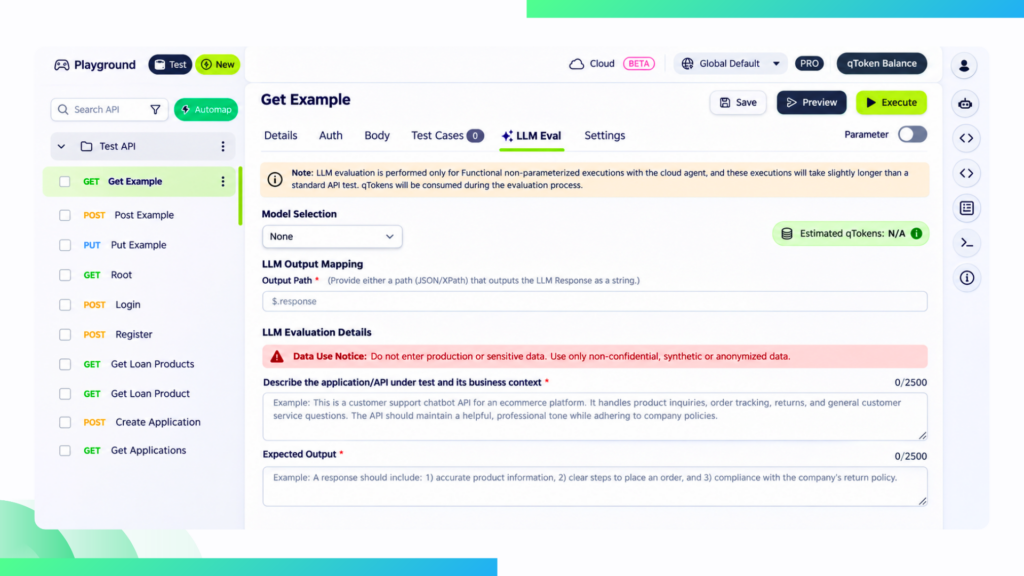
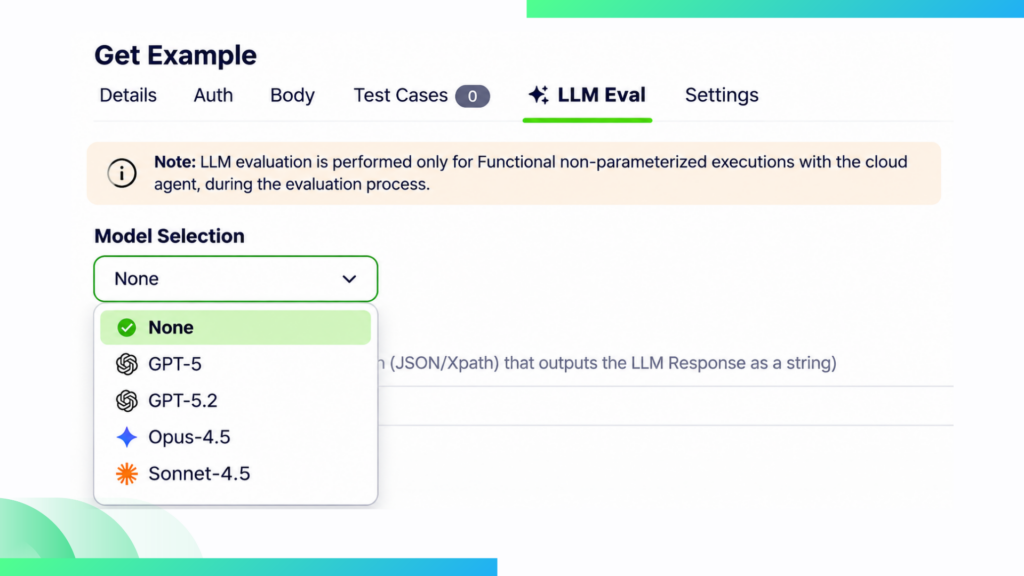
Step 3: Select the model you want to evaluate with
Step 4: Add context
Briefly describe the application or API you are testing and the business it serves.
Cover these points:
- What it is
- The type of system, such as a chatbot API, order management API, or payment API.
- Who it serves
- The industry or platform, such as e-commerce, banking, healthcare, or SaaS.
- What it does
- The problem it solves or the function it provides.
- Who uses it
- End users, customers, internal teams, partners, and so on.
- How it should respond (optional)
- For example: professional, friendly, and compliant with policy.
Template:
This API is used for …
It supports …
Its main users are …
It should respond in a … manner.
A one-line description also works, as in our example.
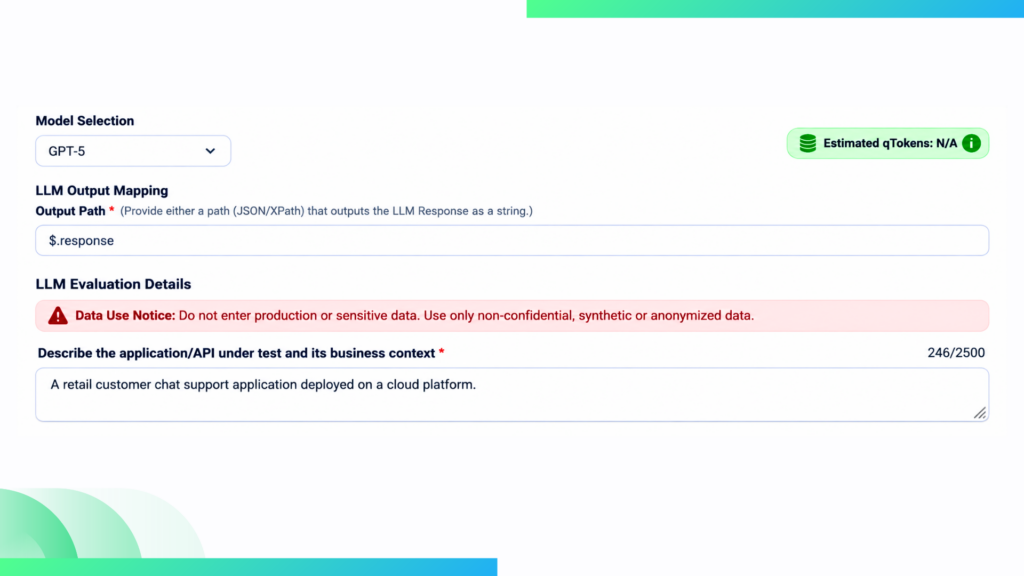
Step 5: Define Expected Output
Again, you can:
- Describe what a successful response should include
- Give the order or structure of the response
- Greeting → main information → additional details → closing (if applicable).
- Add accuracy requirements
- Data must be correct, complete, and relevant.
- Mention formatting rules
- Date formats, field names, response structure, etc.
- Include tone or clarity expectations
- Clear, concise, professional, helpful.
Example :
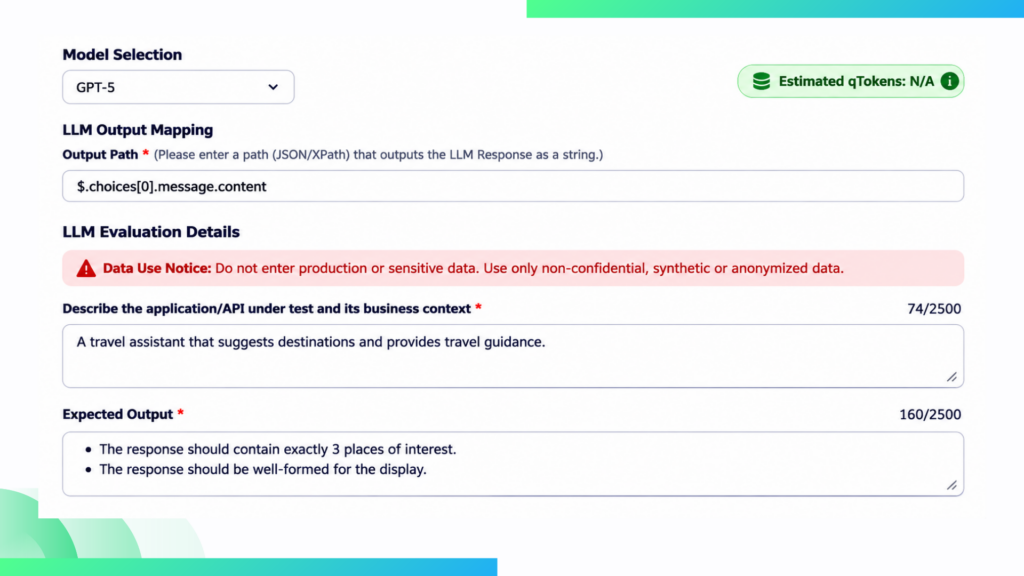
Step 6: Add some Rules/Guardrails (Optional)
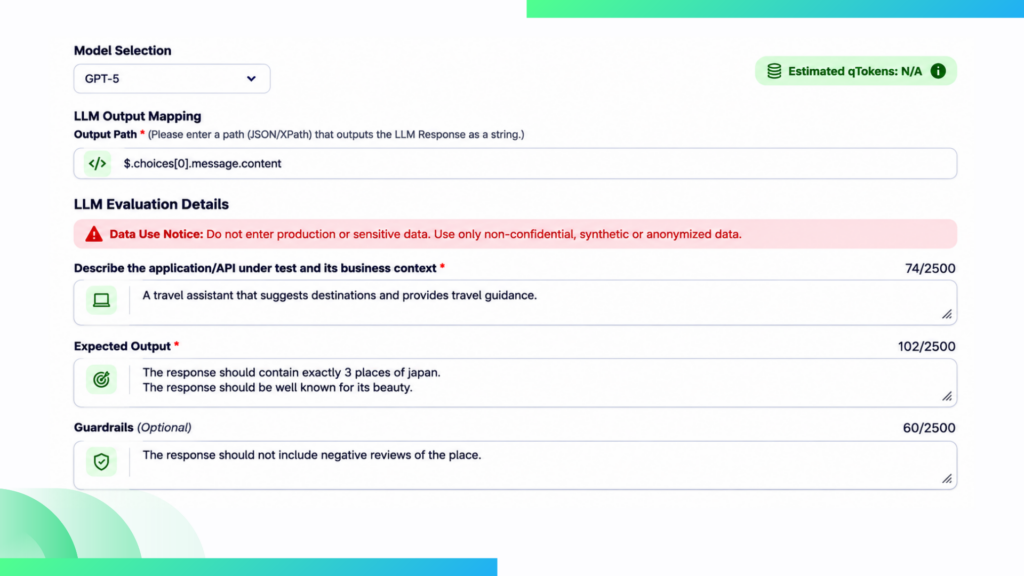
Step 7: Click on save and hit on execute.
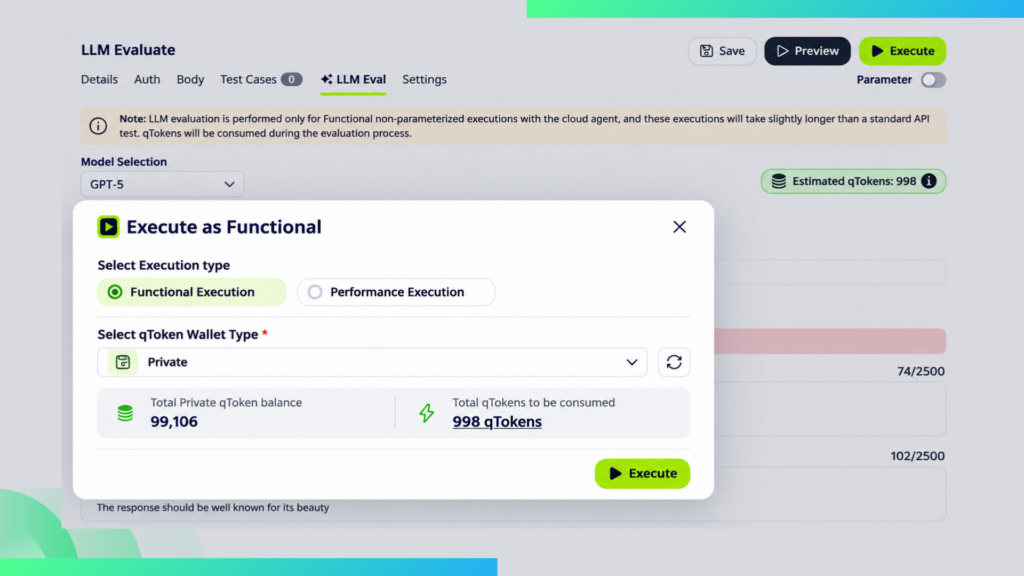
Select the functional execution type, select the token wallet type. And click on execute.
Step 8: Evaluate results.
Once the evaluation is complete, you’ll find it in the reports tab as shown below. Click on the test script to get the detailed report.
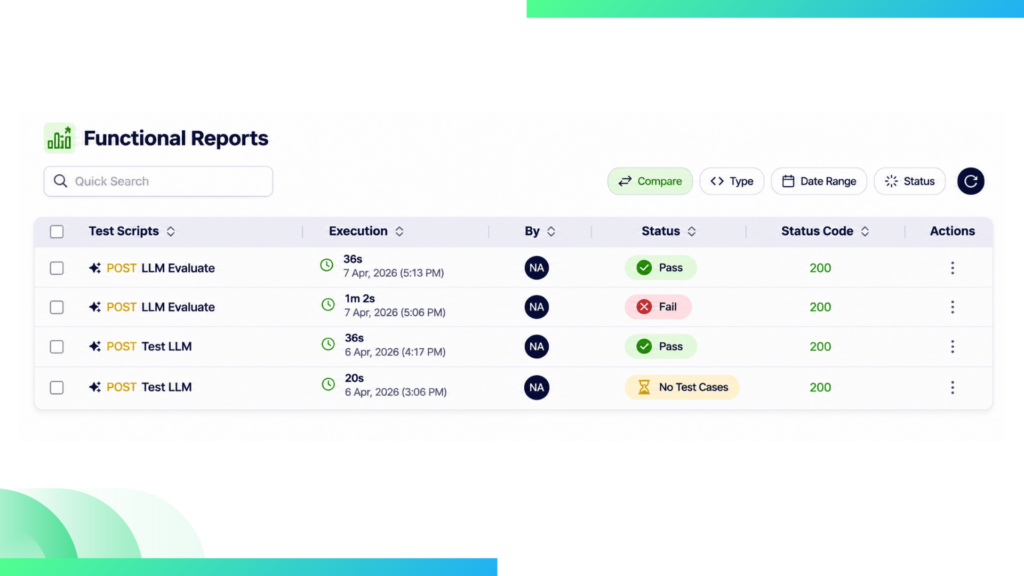
Once the report is open click the LLM evaluation tab.
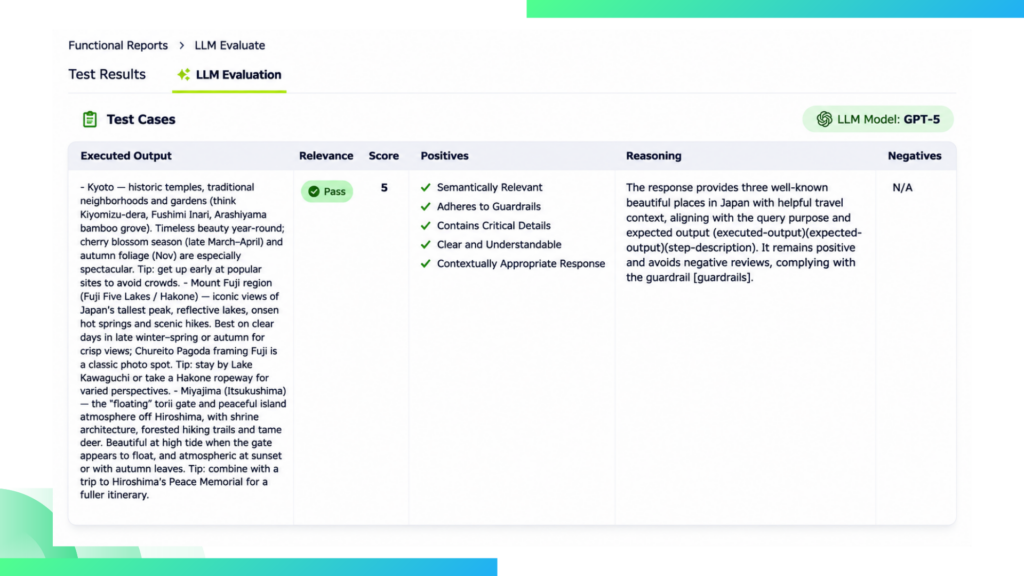
As you can see here the report shows if the LLM passed the tests, and also rates it form 1-5(5 being the highest) and also lists down the positives it was tested against.
Now you can run the process again with different model and then compare the evaluation results for your LLM.
In Closing
Most teams evaluate whether their LLM answers are correct. Almost no teams evaluate whether their LLM answers are confidently wrong in a way that causes harm.
Most teams today evaluate LLMs in the simplest way possible: “Was the answer correct?”
But that’s no longer enough.
The real risk isn’t just when a model gets something wrong — it’s when it gives a confident, polished, believable answer that is wrong, and traditional evaluation tools fail to catch it.
Most current LLM evaluation platforms are still lagging behind because they focus heavily on binary scoring:
- Right vs wrong
- Pass vs fail
- Keyword match vs no match
What they often miss is quality beyond correctness.
That’s where QyrusAI’s LLM Evaluator changes the game.
Instead of limiting evaluation to surface-level correctness, we help teams assess whether responses are:
- Semantically relevant to the prompt
- Adherent to defined guardrails and policies
- Inclusive of critical required details
- Clear and understandable for end users
- Contextually appropriate to the intended use case
Build your LLM and get it evaluated on QyrusAI. The validation for your product’s future just got easier.
Stay Ahead, Stay in the Loop with QyrusAI!
One Platform for Modernization, Quality Assurance and Intelligent IT Operations.
 November 20, 2026
 12 min